
Insights
Product, design, AI, and engineering perspectives from our team.
Reducing SaaS and Vendor Sprawl as You Scale
As Australian scale-ups grow, SaaS tools and vendor contracts accumulate faster than governance can keep up. This guide covers how to audit, evaluate overlap, negotiate renewals, and cut integration and security overhead.
When to Renegotiate Software Contracts During Rapid Growth
Renegotiating a software contract during a growth phase is about timing and leverage, not just price. This guide covers the triggers that should prompt a renegotiation, the 90–120 day window that preserves your leverage, and how to tell a commercial fix from a genuine modernisation need.
Sustainable, Cost-Efficient Cloud Architecture for Scale-Ups
Cost-efficient cloud architecture at scale starts with governance, not infrastructure choice. This piece covers the account structure, guardrails, and cost levers that keep spend under control as engineering teams grow, and how to choose between a SaaS governance layer and an embedded consultancy model.
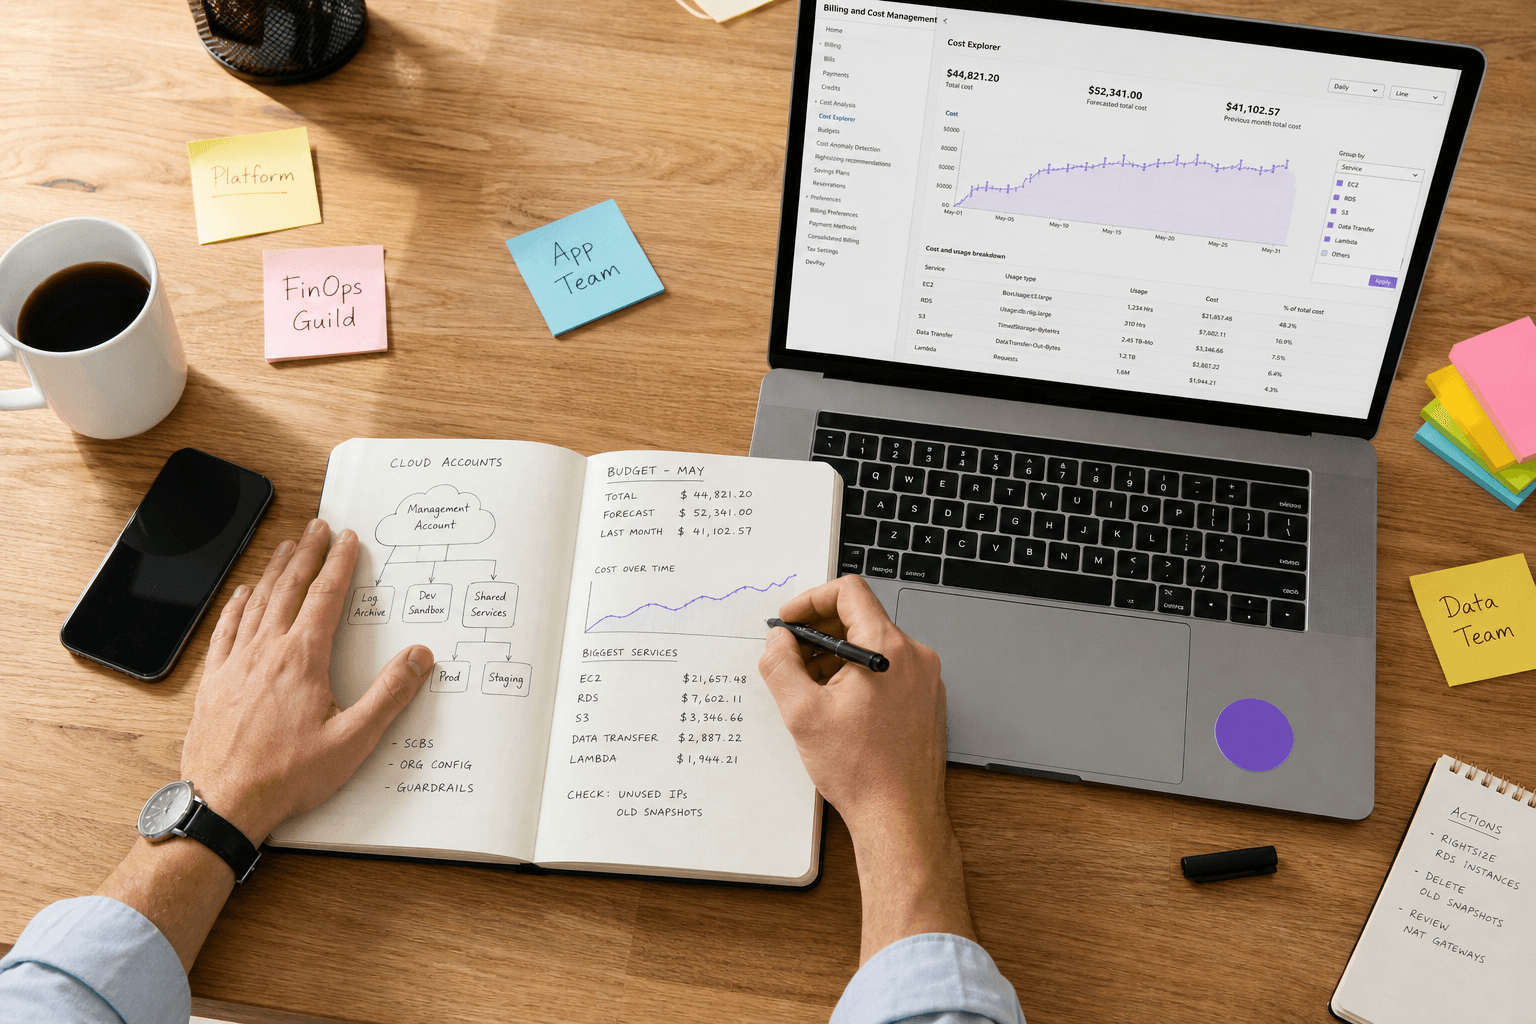
FinOps for Engineering Leaders: Controlling Cloud Spend
Cloud spend rarely spikes overnight — it creeps until the AWS or Azure bill becomes a board-level issue. Here's a practical framework for Australian engineering leaders to structure account governance, attribute spend, and decide between SaaS tooling and embedded support.
LLM Cost Optimisation: Cutting Spend Without Cutting Quality
Cutting LLM spend doesn't have to mean cutting quality. This guide covers the practical engineering levers — model tiering, prompt caching, batching, prompt budgets, and observability — with a worked example showing how they compound.
AWS SageMaker vs Self-Hosted GPU Serving: Cost and Control
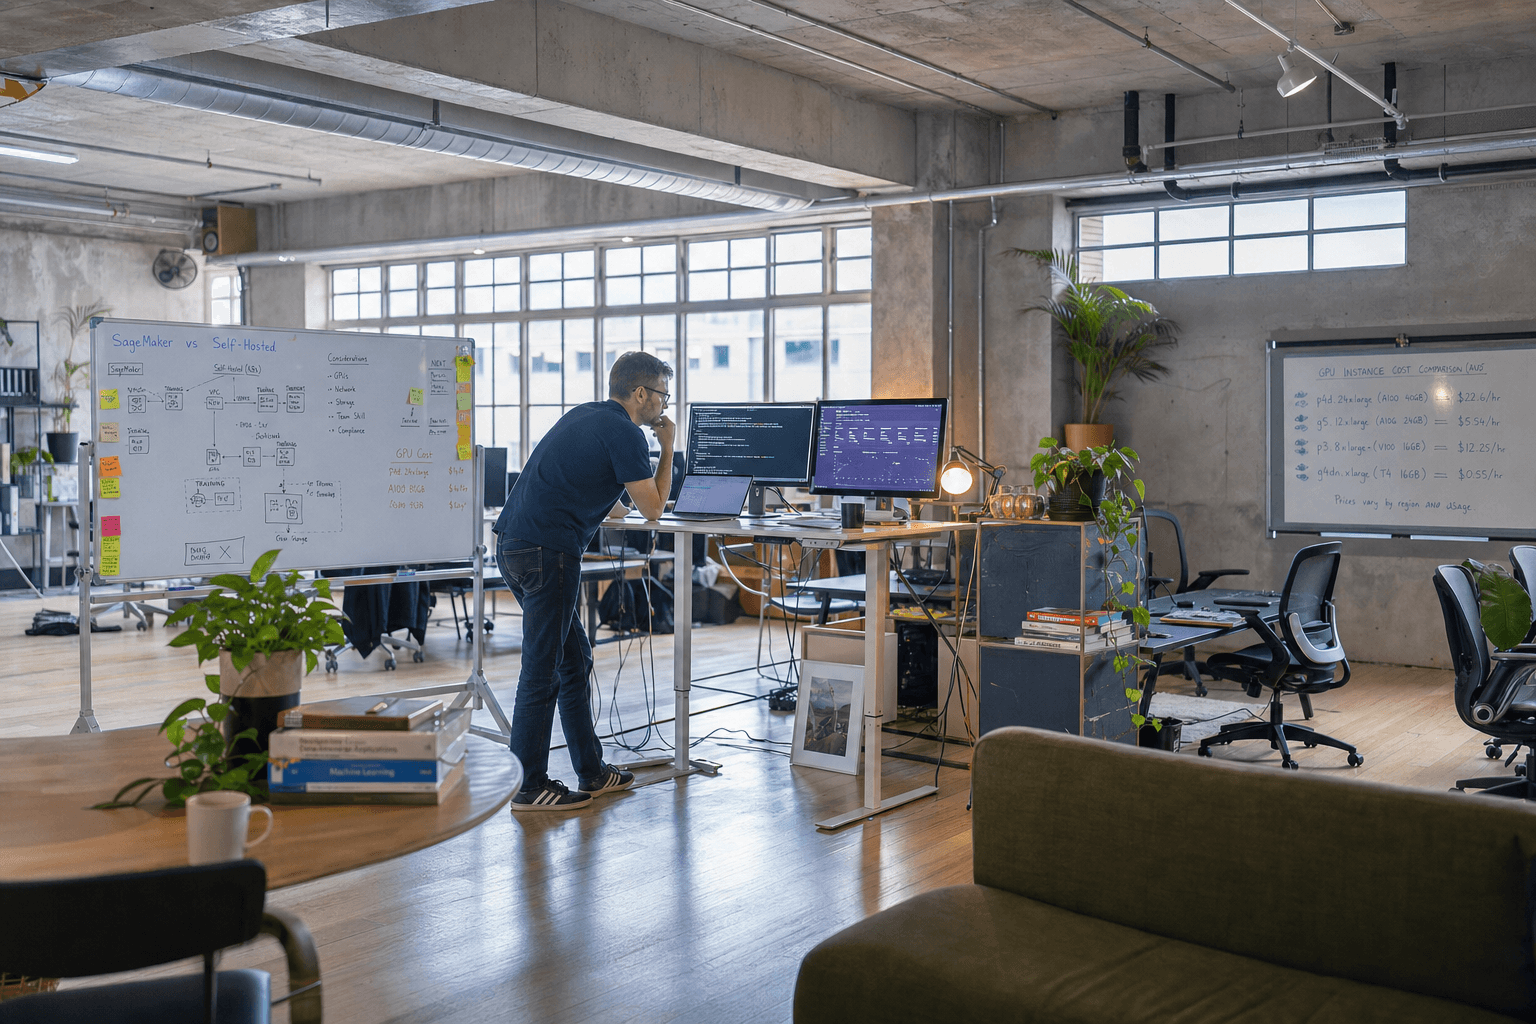
AWS SageMaker and self-hosted GPU serving on A100 or H100 hardware each make sense under different conditions — and the wrong choice becomes expensive quickly. This article breaks down the cost structure, operational trade-offs, and decision framework for Australian engineering teams moving ML models to production.
Multi-Model Routing: Cut LLM Costs Without Sacrificing Quality
Multi-model routing sends each AI request to the cheapest model capable of handling it well, rather than routing everything through a frontier model. Combined with semantic caching and fallback chains, it is one of the most effective ways to control LLM costs in production without degrading quality. This post covers the core patterns and what a practical production architecture looks like.
Application Modernisation Cost Guide for Australia
Application modernisation costs in Australia vary significantly depending on your architecture, chosen approach, and cloud provider. This guide breaks down realistic cost ranges for common modernisation paths — from rehosting to full re-architecture — so you can plan and budget with confidence.
AI Consulting Pricing Models in Australia: A Guide for CTOs
Understanding the three main AI consulting pricing models—fixed price, time and materials, and retainer—helps CTOs choose the right commercial approach for different project types and risk profiles. The key is matching pricing structure to project uncertainty and organisational needs.