
Insights
Product, design, AI, and engineering perspectives from our team.
Feature Stores for Machine Learning at Scale
Growing data teams often outgrow spreadsheets and ad hoc pipelines long before they need a full feature store platform. Here's how to tell the difference — and how Google Cloud's Vertex AI implements feature management as a concrete example.
CLV Modelling for SaaS and E-commerce Growth Teams
A practical guide for SaaS and e-commerce data leaders on building customer lifetime value models that inform retention and acquisition spend. Covers data requirements, modelling approaches, and common pitfalls for teams scaling past product-market fit.
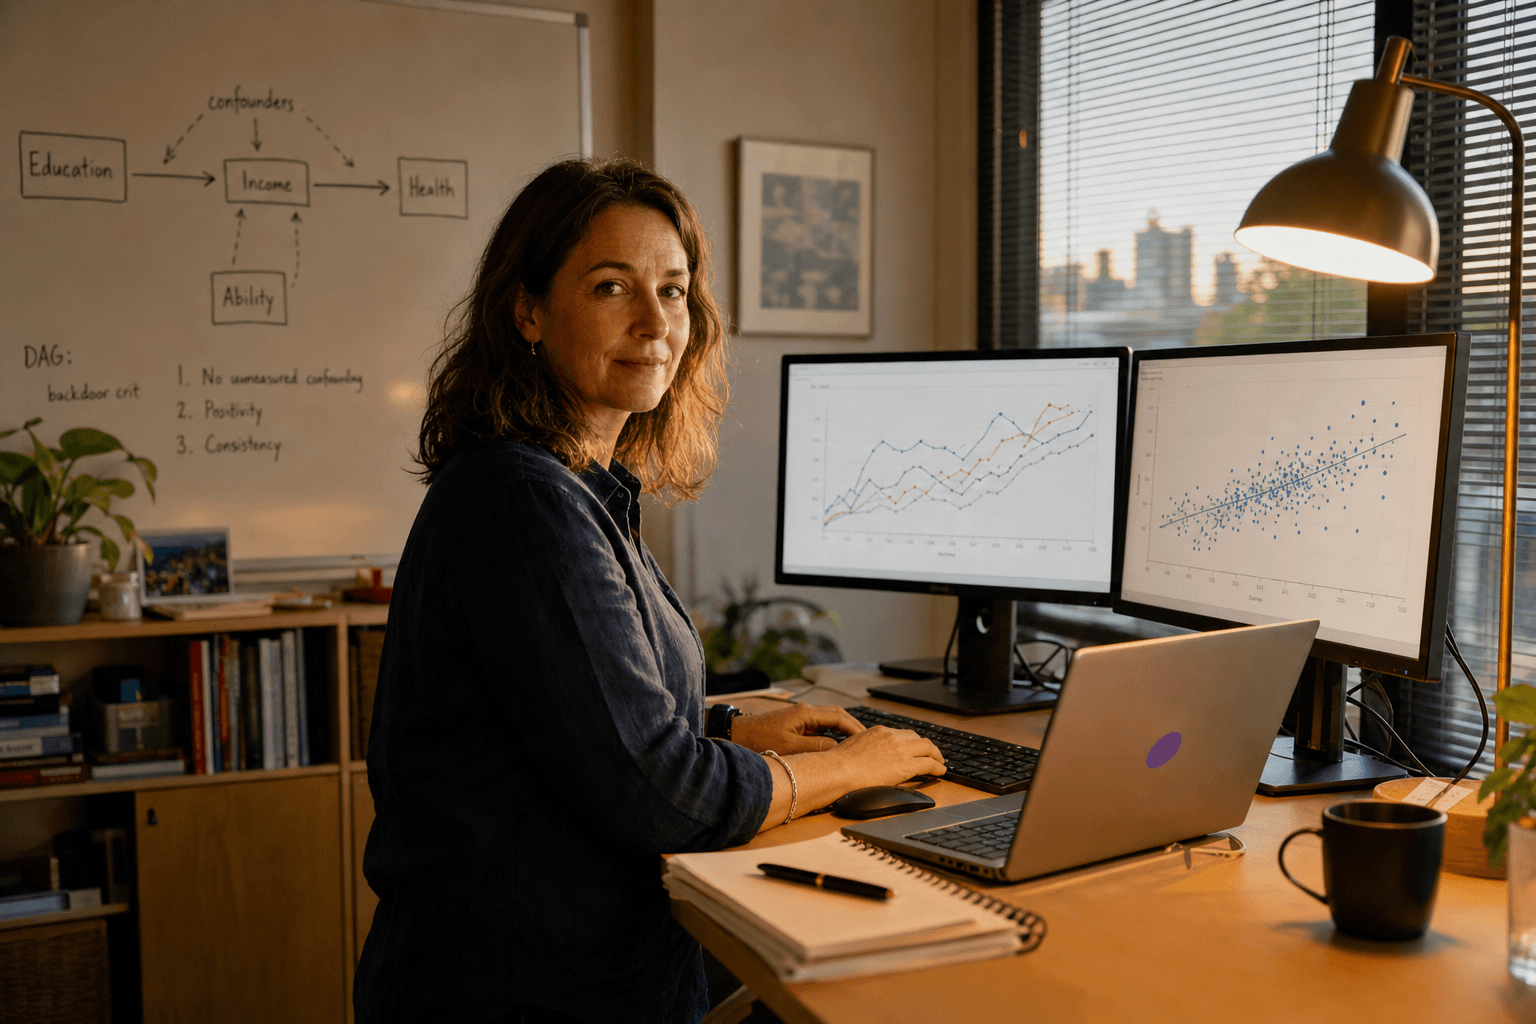
Causal Inference for Business: Beyond Correlation in Analytics
Correlation-based dashboards can tell you what happened, but not what will happen if you change something. This article explains when that gap misleads resourcing and pricing decisions, and how A/B testing, quasi-experiments and uplift modelling give growing Australian companies more reliable answers.
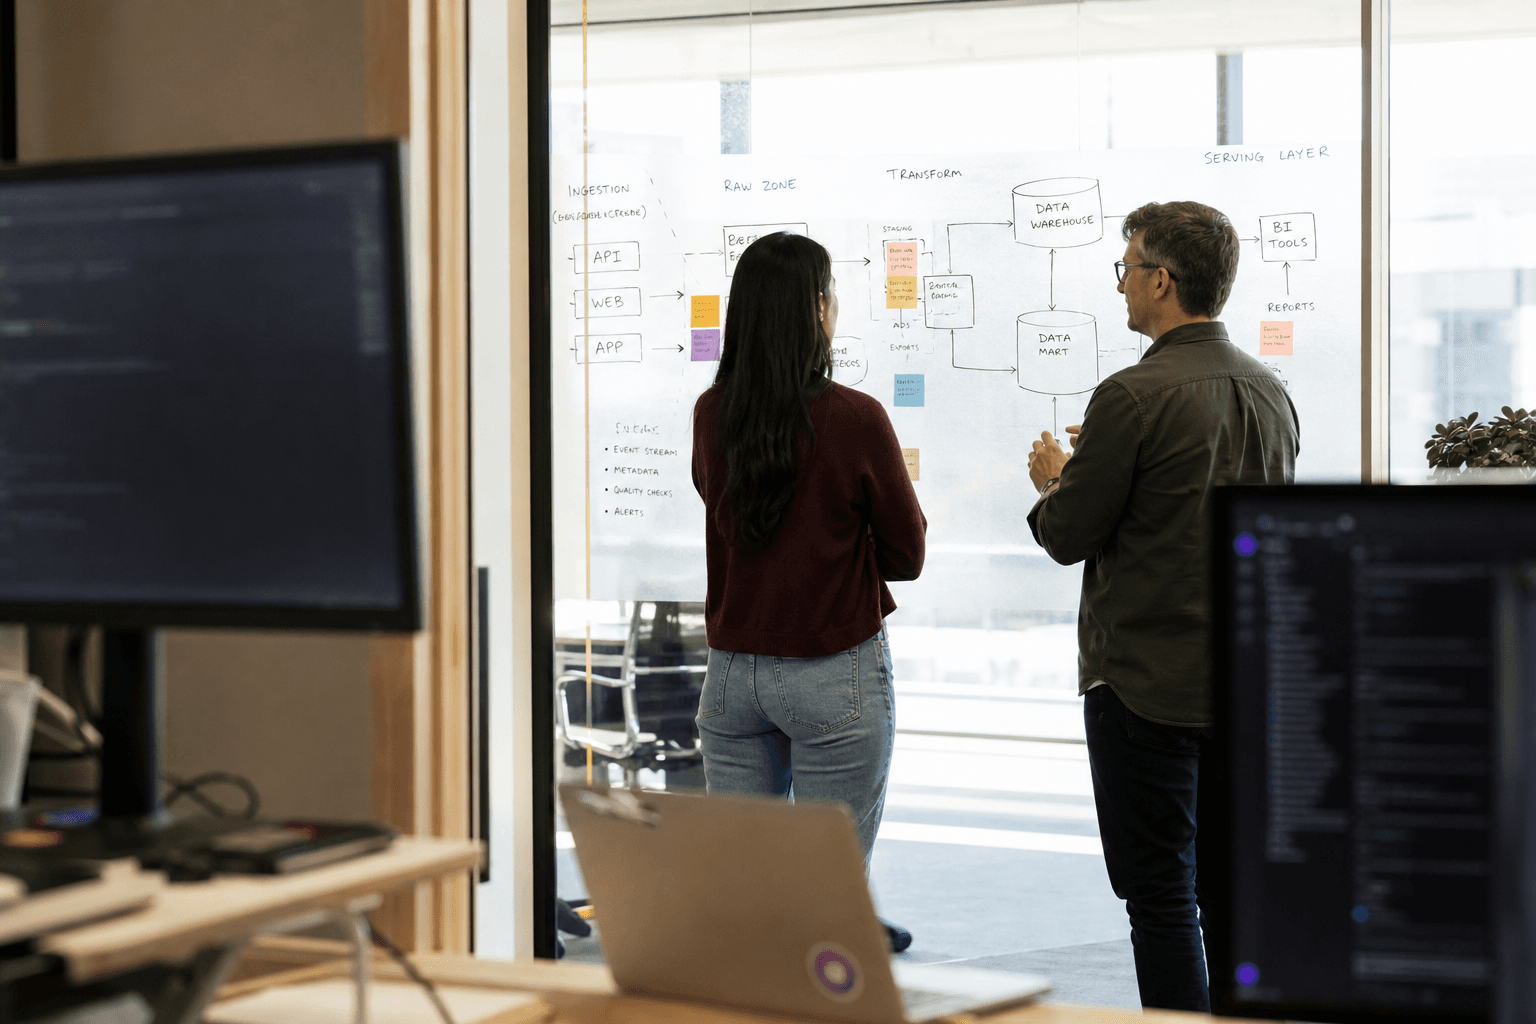
Data Lineage and Cataloging: Trustworthy, Discoverable Data
Data lineage and cataloging are the unglamorous foundations that make AI and self-serve analytics trustworthy. This guide covers what to build, in what order, and how the Australian Privacy Principles shape the work.
Data Mesh vs Centralised Data Platforms for Mid-Market Growth
Choosing between data mesh and a centralised data platform is an organisational decision as much as a technical one. This guide walks Australian scale-up leaders through team structure, governance overhead, and when each pattern fits.
Building an Experimentation Platform for Product Teams
Moving from ad hoc A/B tests to a real experimentation platform means getting event tracking, statistical rigour, and feature-flagging right — together. Here's what that infrastructure actually requires.
Building an A/B Testing Platform for Product Teams
An experimentation platform stands on three pillars — event tracking, statistical rigour, and feature-flagging infrastructure. This article breaks down why ad hoc A/B testing breaks at scale and how to decide whether to build, buy, or combine.
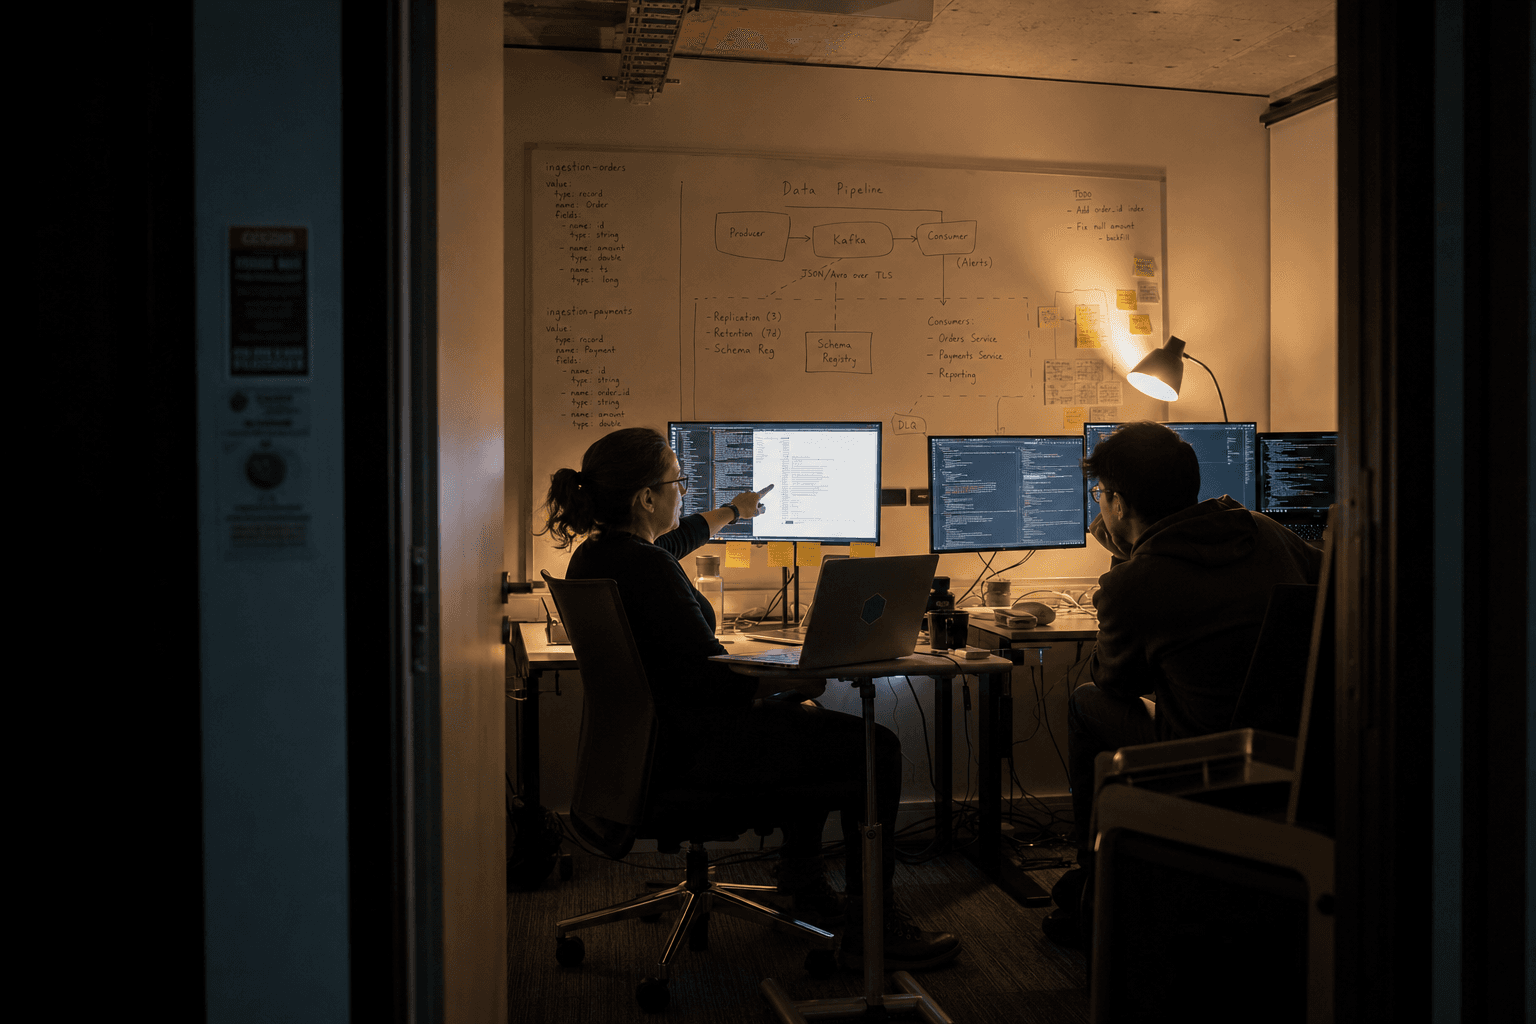
Data Contracts: Stopping Pipeline Breakage Before It Starts
Silent schema drift is one of the most common and costly causes of broken data pipelines and degraded AI models — and it rarely announces itself. Data contracts are the structural mechanism that catches upstream changes before they reach production, enforcing schema, quality, and freshness expectations at the producer level. This post explains what data contracts are, how to implement them with modern tooling, and why they are foundational to reliable AI and analytics infrastructure.
The Open Knowledge Format: AI-ready knowledge without lock-in
The Open Knowledge Format (OKF) is a vendor-neutral way to turn scattered organisational knowledge into a portable, AI-ready asset. Here's what it is, why it matters for RAG and AI readiness, and how to start.