
Insights
Product, design, AI, and engineering perspectives from our team.
PyTorch vs TensorFlow in 2025: Choosing a Production ML Framework
PyTorch and TensorFlow are both production-capable ML frameworks in 2025, but they suit different teams, workloads, and deployment environments. This guide helps technical leaders make a defensible framework choice based on ecosystem fit, serving requirements, and team context — not benchmarks or hype.
LLM Evaluation in Production: A Three-Layer Approach
Shipping an LLM feature is the easy part. Knowing whether it still works correctly six weeks later — after a prompt change, a model version bump, or a shift in user behaviour — is where most teams struggle. This post covers a three-layer evaluation approach that gives engineering teams real confidence in production LLM systems.
Claude vs GPT-4 vs Gemini: Choosing the Right Enterprise LLM
Claude, GPT-4, and Gemini are all genuinely capable enterprise LLMs — but they have different strengths, deployment models, and compliance profiles. This guide helps Australian technical leaders compare the three across reasoning, coding, multimodal capability, cost, latency, and data residency, and choose the right model for each task.
Kubernetes for AI Workloads: When It's Worth the Complexity
Kubernetes is worth the complexity for AI workloads when you are serving multiple models in production, managing GPU scheduling across workloads, and have platform engineering capacity to operate it. For teams at earlier stages, managed services are the more pragmatic starting point. This guide helps technical leaders make the call clearly.
AI Inference Optimisation: A Production Decision Guide
Shipping a model is the beginning, not the end. Once an AI feature is live, inference cost and latency become real engineering problems that compound at scale. This guide explains the key optimisation levers available to technical leaders — and how to choose between them.
Multi-Agent Orchestration: Semantic Kernel vs AutoGen vs LangGraph
Semantic Kernel, AutoGen, and LangGraph represent three genuinely different bets on how multi-agent systems should be structured. This decision guide covers orchestration models, state management, production-readiness, and how to match the right framework to your problem — before you commit to an architecture you will live with.
LangChain vs LlamaIndex vs Vercel AI SDK: Choosing an AI Framework
LangChain, LlamaIndex, and the Vercel AI SDK each solve different problems — and picking the wrong one creates real maintenance overhead for your engineering team. This guide breaks down the strengths, trade-offs, and ideal use cases for each framework so you can make a grounded architecture decision.
Open-Source vs Proprietary LLMs: When to Self-Host
Self-hosting open-weight models like Llama or Mistral gives Australian teams data residency, cost control at scale, and deployment flexibility — but it comes with real infrastructure and operational tradeoffs. This post works through when each approach makes sense, with a practical framework for mid-market teams deciding between open-weight self-hosting and proprietary APIs like GPT-4 or Claude.
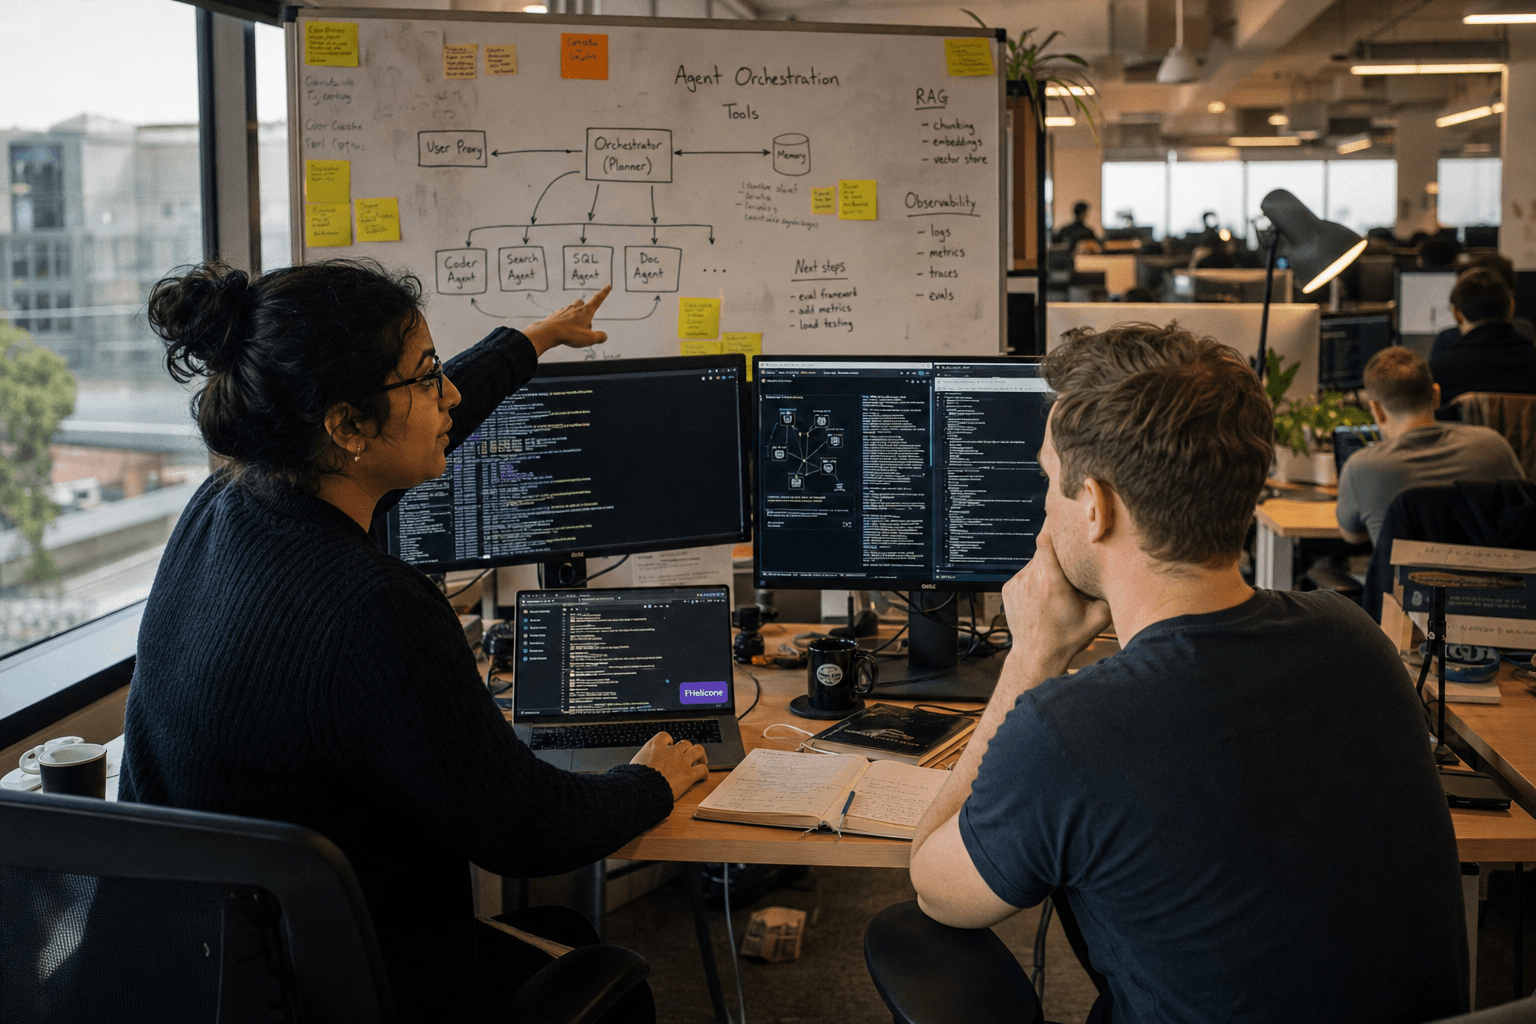
AI Agents in Production: Lessons from Real Enterprise Deployments
Enterprise AI agents require careful orchestration, robust failure handling, and strategic cost management to work reliably at scale. Here's what we've learned from real deployments.