Measuring AI Feature Adoption: A Framework for SaaS Teams
Usage counts don't tell you whether an AI feature is actually working. This framework covers event design, cohort analysis, and qualitative feedback loops for measuring real adoption of AI features in SaaS products — distinct from financial ROI modelling.
Why AI features need their own adoption metrics
AI features fail silently more often than they fail loudly. A user might open a copilot panel, see an unhelpful suggestion, and never return — with no error logged, no support ticket raised, and no obvious signal in standard product analytics. If you are measuring an AI feature the same way you measure a button or a form, you will likely overestimate adoption and miss the real reason usage stalls.
Traditional SaaS analytics were built around deterministic actions: a user clicks, a record is created, a page loads. AI features introduce a different failure mode — the feature can work exactly as designed and still disappoint the user, because the output quality, not the interaction itself, determines whether they come back. That means adoption measurement for AI features has to capture not just whether people use the feature, but whether they trust and keep using it.
What does "AI feature adoption" actually mean?
AI feature adoption is the degree to which target users discover an AI-powered capability, engage with it repeatedly, and continue to rely on it over time rather than reverting to manual workflows or abandoning it after a trial. It is distinct from financial ROI modelling, which asks whether the feature justifies its cost — adoption measurement asks whether people actually want it.
These two questions are related but should be tracked separately. A feature can show strong adoption and weak ROI (high usage, high inference cost, unclear revenue impact) or the reverse (low usage but high value per interaction, as with a rarely-used but high-stakes compliance check). Conflating them in one dashboard tends to produce decisions that optimise for the wrong thing.
How should you design events for AI features?
Event design for AI features should capture three things standard analytics usually miss: the quality signal the user gave (explicit or implicit), whether the AI output was actually used, and what the user did immediately afterward. Without these, you can count "AI feature opened" a thousand times and still not know if it helped anyone.
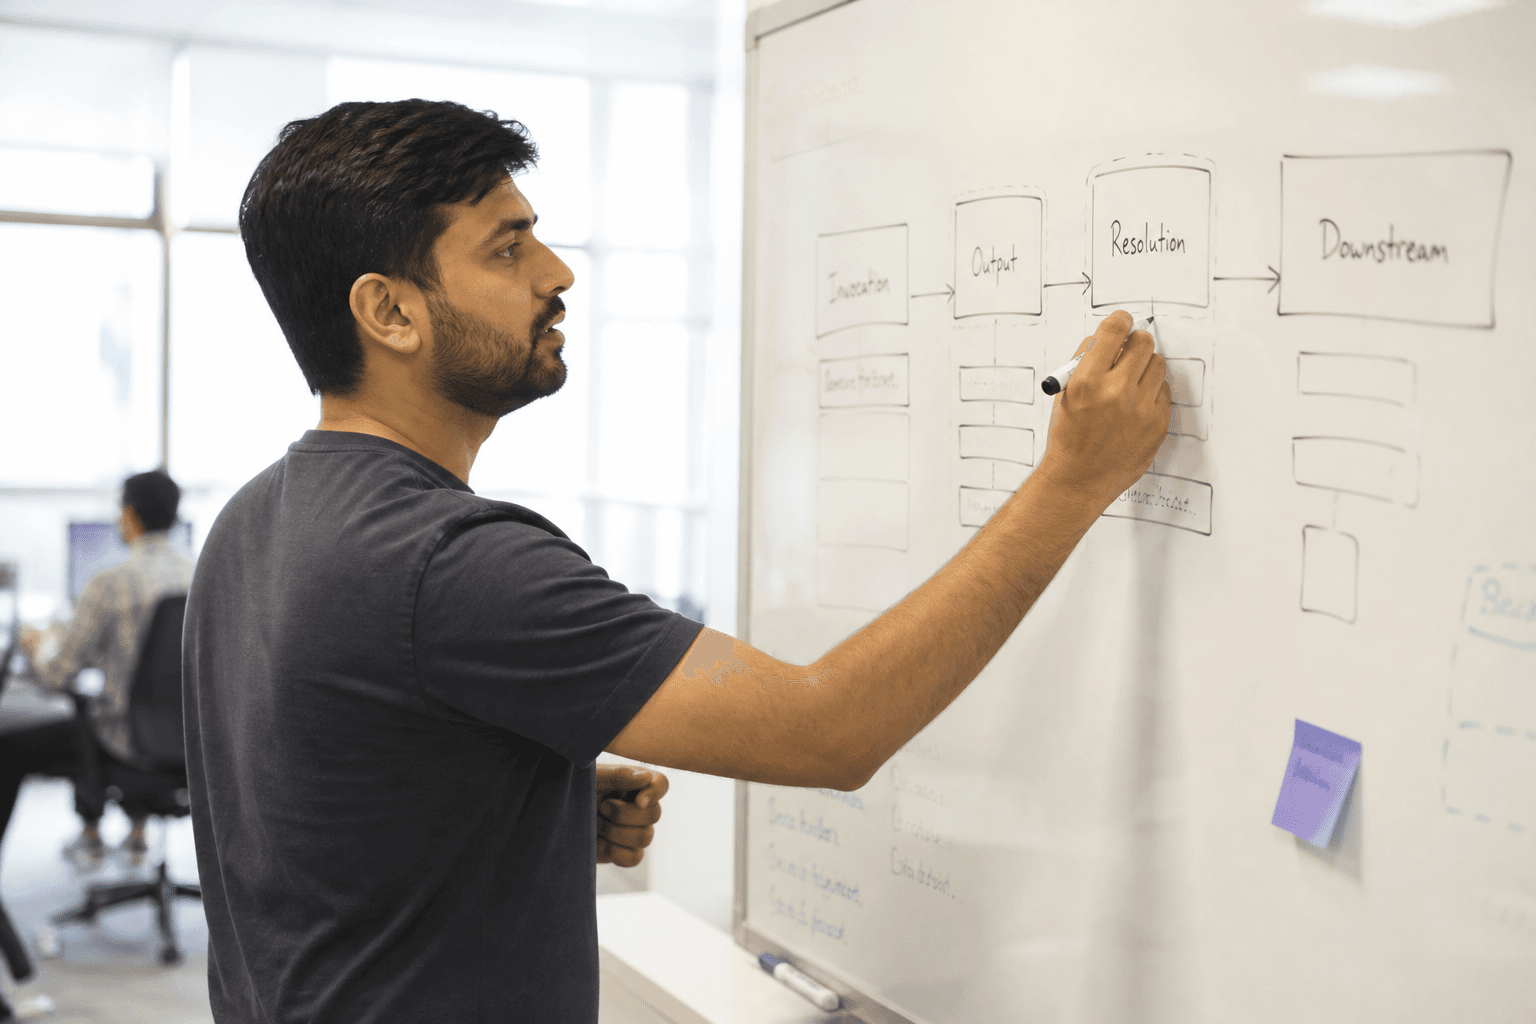
A practical event taxonomy for an AI feature typically includes:
- Invocation events — the feature was triggered (prompt submitted, suggestion surfaced, agent task started). Record the trigger type (user-initiated vs proactive) and the context it fired in.
- Output events — what the AI returned, including latency, whether it errored or returned a low-confidence result, and which model or pipeline version served it.
- Resolution events — what the user did with the output: accepted it unmodified, edited it, discarded it, escalated to a human, or repeated the request with a different input. This is usually the single most informative event for AI products and the one teams skip most often.
- Downstream events — whether the user completed the task the AI was meant to support, and how that compares to users who did not use the AI path at all.
Versioning matters here in a way it doesn't for conventional features: model updates, prompt changes, and retrieval-pipeline tweaks all change behaviour without a visible UI change, so every event should be tagged with the model/pipeline version in effect at the time. Teams building this instrumentation from scratch often find it overlaps heavily with the telemetry needed for AI engineering and ongoing model monitoring, so it's worth designing the event schema alongside the engineering team building the feature rather than bolting it on afterward.
What does cohort analysis look like for AI features?
Cohort analysis for AI features groups users by their first meaningful interaction with the feature and then tracks how their behaviour diverges over subsequent weeks — specifically whether they return to the AI path, revert to the manual alternative, or stop using the product area entirely. This reveals trust decay that a simple daily-active-user count hides.
Useful cuts include:
- First-outcome cohorts: users whose first AI interaction was accepted vs edited vs discarded, tracked for retention over the following four to eight weeks. A sharp drop-off in the "discarded" cohort is an early warning sign long before churn shows up in revenue data.
- Task-complexity cohorts: users working on simple tasks vs complex ones, since AI assistance often adopts quickly for simple cases and stalls on complex ones where trust has to be earned repeatedly.
- Power-user vs casual-user cohorts: whether AI features are used disproportionately by your most engaged users (a sign the feature extends existing value) or by newer users trying to substitute for expertise they don't yet have (a sign the feature may be a crutch rather than a durable habit).
The comparison below is qualitative rather than based on invented figures, but it reflects the kind of pattern teams typically look for when reviewing cohort data:
| Signal pattern | Likely interpretation | Suggested next step |
|---|---|---|
| High first-use, fast decline in return visits | Novelty effect, output quality not meeting expectations | Review output acceptance rate and gather qualitative feedback |
| Steady but low invocation rate | Feature not discoverable or not matched to a real workflow moment | Revisit placement and trigger design, not model quality |
| High edit rate on accepted outputs | Output is useful as a starting point, not a finished answer | Reframe UX around "draft and refine" rather than "answer" |
| Rising reliance over time with stable edit rate | Durable trust, feature embedded in workflow | Candidate for expansion to adjacent use cases |
How do you capture satisfaction, not just usage?
Usage data tells you what people did; it rarely tells you why. Qualitative feedback loops — in-product micro-surveys, structured interviews, and support-ticket analysis — are what connect a cohort pattern like "high edit rate" to an actual cause, such as the AI missing domain-specific context or the output format not fitting the user's workflow.
Lightweight, high-signal methods worth building into the product itself include:
- A single contextual prompt immediately after an AI interaction (thumbs up/down plus an optional one-line reason), kept short enough that response rates stay usable.
- Periodic structured interviews with a small sample of both heavy and light users of the feature, specifically asking what they do when the AI output is wrong, not just whether they like the feature.
- Tagging and coding support tickets that reference the AI feature separately from general product issues, so trend lines in complaint volume are visible against usage trend lines.
These qualitative signals should feed back into the same event schema and cohort structure described above, rather than living in a separate spreadsheet. Teams that treat quantitative and qualitative AI feedback as one connected system, built on solid data infrastructure, tend to spot problems weeks earlier than teams relying on quarterly surveys alone.
How does this differ from ROI measurement?
Adoption analytics and ROI modelling answer different questions and should stay in separate frameworks even though they share data. ROI modelling asks whether the feature's inference cost, engineering investment, and support overhead are justified by revenue, retention, or cost-avoidance outcomes. Adoption analytics asks whether users actually want and trust the feature enough to keep choosing it.
A feature can pass one test and fail the other. Keeping them distinct protects against two common mistakes: killing a feature with strong adoption because early ROI modelling looks unfavourable before the feature has matured, and continuing to invest in a feature with respectable ROI metrics that users are quietly avoiding. If your organisation is still working out which problem to solve first, our AI product strategy work usually starts by separating these two questions before any instrumentation is built.
Common pitfalls worth naming
Most AI adoption measurement programs run into the same handful of problems: tracking invocation without resolution (so "usage" looks healthy while trust quietly erodes), failing to version-tag events against model and prompt changes, and treating a single aggregate satisfaction score as sufficient when cohort-level variation is where the useful insight actually lives. None of these require exotic tooling to fix — they require deciding, before the feature ships, what "adoption" will mean and building the instrumentation to answer it honestly, including cases where the honest answer is that the feature isn't working yet.
For more on related topics, see our insights, including our piece on AI readiness assessment.
If you're building or scaling AI features inside a SaaS product and want a measurement framework that actually reflects how your users behave, get in touch — we can help you design the instrumentation, cohort structure, and feedback loops before you've already shipped a feature you can't properly evaluate.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.