Designing Technical Assessment Frameworks for AI/ML Hiring
Hiring in-house AI and ML engineers requires a different interview loop to general software hiring — and a different lens to evaluating AI vendors. This guide sets out how data and engineering leaders can structure interview loops and take-home assessments to test ML judgement, not just code.
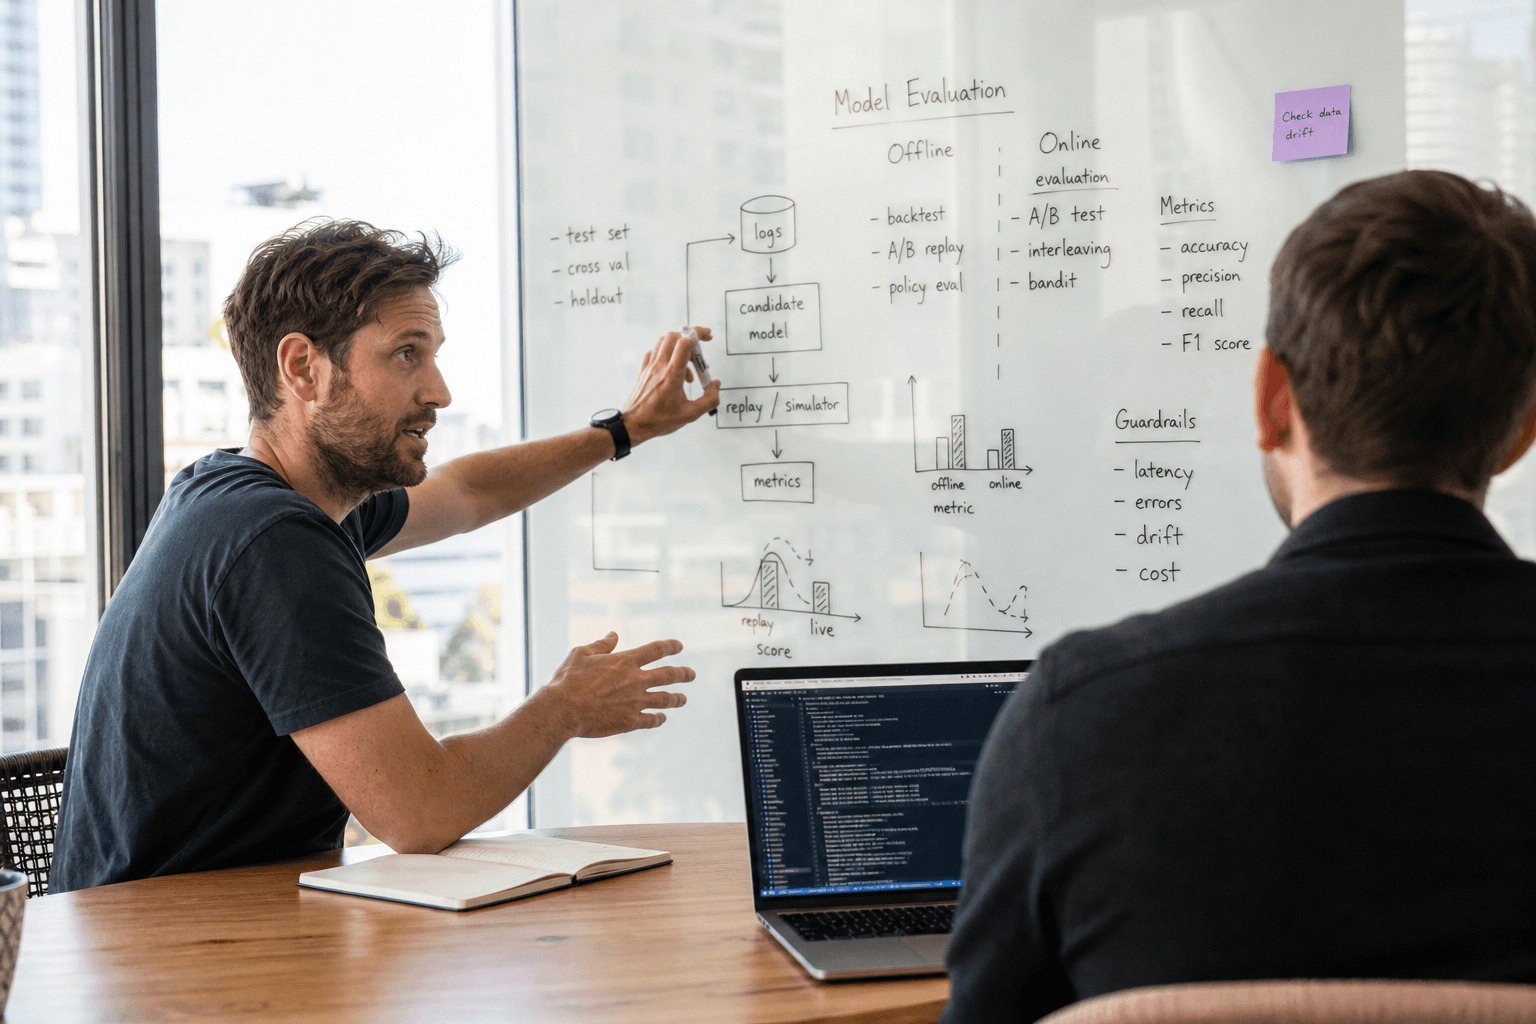
Hiring an in-house AI or ML engineer is a different exercise to evaluating an external AI vendor or platform. When you assess a vendor, you're testing a product against a spec. When you assess a candidate, you're testing judgement, taste, and how someone behaves when the data is messy and the model is wrong. Most engineering leaders inherit their technical interview loops from general software hiring and bolt on a few ML questions. That approach misses the specific failure modes that make AI/ML roles hard to hire for well.
What makes hiring AI/ML engineers different from hiring software engineers?
An AI/ML engineering assessment framework is a structured set of interview stages and exercises designed to evaluate a candidate's ability to build, evaluate, and operate machine learning systems in production — not just write correct code. The core difference from general software hiring is that ML work is probabilistic rather than deterministic: there's rarely a single correct output, and the hardest skill to assess is whether someone can reason about uncertainty, data quality, and failure modes before a model ever reaches production.
A candidate who writes clean, well-tested Python but has never had to debug a silently degrading model in production will approach incidents very differently to one who has. Your loop needs to surface that difference early, not discover it three months into the job.
What competencies should an AI/ML interview loop actually test?
A well-designed loop tests five distinct competency areas, each with its own exercise type, rather than relying on one long technical interview to cover everything. Compressing all of this into a single generalist coding round is the single most common design mistake we see in ML hiring processes.
| Competency | What it covers | Typical assessment format |
|---|---|---|
| ML fundamentals | Model selection, bias/variance trade-offs, evaluation metric choice | Whiteboard or verbal problem-solving session |
| Data engineering judgement | Pipeline design, data quality handling, feature engineering | Take-home or system design exercise |
| Production/MLOps literacy | Model monitoring, drift detection, retraining triggers, rollback strategy | Scenario-based discussion |
| Applied coding ability | Implementing and debugging real code, not pseudocode | Live or take-home coding exercise |
| Communication and judgement under ambiguity | Explaining trade-offs to non-technical stakeholders, pushing back on infeasible requests | Case study discussion with a hiring manager or product lead |
Notice that only one row is a traditional coding test. If your current loop is three rounds of algorithm questions and a culture fit chat, it's testing for a different job.
For related reading, explore our ai product strategy and ai engineering services, or browse more insights.
How should the interview loop be structured end to end?
A strong loop runs four to five stages, moving from broad screening to deep, role-specific evaluation, and should take no longer than two to three weeks from first contact to offer. Dragging ML hiring loops out over six or more weeks is one of the most common reasons strong candidates accept a competing offer before you finish evaluating them.
A sensible sequence looks like this: a recruiter or hiring manager screen to confirm domain and seniority fit; a technical screen focused on fundamentals and reasoning rather than trick questions; a take-home or paired exercise that mirrors real work; a system design or case study round focused on production judgement; and a final conversation with the hiring manager and a cross-functional stakeholder to assess communication and team fit. Each stage should have a single, clearly owned evaluation criterion — avoid having five interviewers all independently judging
If you're looking for guidance on this topic, get in touch — we're happy to help.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.