Engineering Capacity Planning for AI Adoption
Engineering capacity planning for AI adoption means matching team size, skill mix, and engagement model to the real technical workload an AI initiative creates at each stage. This guide covers how to spot the gap early and choose between fractional, contract, pod, and permanent resourcing.
Engineering capacity planning for AI adoption is the process of matching team size, skill mix, and engagement model — permanent, contract, fractional, or pooled — to the actual technical workload an AI initiative requires at each stage of its life. It sits alongside, but is distinct from, ai product strategy, which decides what to build. Capacity planning decides who builds it, and how that resourcing should flex as the initiative moves from pilot to production to scale.
Most engineering leaders don't get a clean slate when AI lands on the roadmap. There's already a product backlog, a support rotation, and a team stretched across existing commitments. The question isn't whether to invest in AI capability — it's how much team, of what kind, and when. Getting this wrong in either direction is costly: over-hire and you carry fixed cost against a roadmap that's still being validated; under-resource and pilots stall in someone's spare cycles indefinitely.
What is engineering capacity planning for AI adoption?
In practice, capacity planning means mapping the technical work an AI initiative actually creates — not the work you assume it creates — against the people and skills you have today, then deciding deliberately how to close the gap. That decision is rarely binary. Most organisations end up blending existing staff, fractional specialists, and time-bound external support rather than making a single hiring call up front. Done well, this planning happens before a pilot starts, not after it stalls.
Why does AI adoption strain existing engineering capacity?
AI initiatives typically demand skills a general product engineering team doesn't have on hand: retrieval pipeline design, model evaluation, vector search tuning, and ongoing monitoring for drift and cost. These aren't skills you pick up mid-sprint, and they don't disappear once a model ships — they become an ongoing operational surface that someone has to own.
This is different from a typical feature build. A checkout flow, once shipped, is largely stable. An AI feature built on a retrieval-augmented generation pipeline, a tuned model, or an autonomous agent keeps needing attention: prompts drift, retrieval quality degrades as source data changes, and evaluation benchmarks need re-running as usage patterns shift. Capacity planning has to account for this steady-state cost, not just the initial build.
What technical surface area does a capacity plan need to cover?
A realistic AI capacity plan should map effort against the full stack an initiative touches, not just "the model." That typically includes agent orchestration and session management, retrieval infrastructure (document ingestion, embedding, context retrieval, prompt augmentation), feature stores and vector search, model tuning and evaluation, and governance policies that constrain what an agent or model is allowed to do. Each of these is a discrete operational surface with its own tooling, SDKs, and failure modes — and each needs an owner, even if that owner is fractional. This is the kind of work we scope directly with clients under ai engineering, because it rarely fits neatly inside an existing sprint cadence.
Most organisations already have strong web and backend engineers. Few have people who've built and operated retrieval pipelines or run model evaluation in production. Recognising that gap early — rather than assuming existing engineers will absorb it — is the single biggest input into a realistic capacity plan. This is closely tied to the state of your data infrastructure: teams with clean, accessible data pipelines typically need meaningfully less new capacity than teams building that foundation from scratch. In the same way, teams still carrying a monolith or legacy backend often need to factor application modernisation work into the same capacity plan, since brittle infrastructure slows down every AI initiative built on top of it.
When should you use fractional support, contractors, a dedicated pod, or permanent hires?
The right engagement model depends on how proven the initiative is and how long the skill will be needed, not on how important the initiative feels. Fractional support and contractors suit exploratory or bounded work; a dedicated pod suits validated initiatives that need sustained focus; permanent hires suit capability you'll need indefinitely and want to own long-term.
| Model | Best suited to | Time to deploy | Ongoing commitment | Institutional knowledge retention |
|---|---|---|---|---|
| Fractional specialist (e.g. fractional CTO or AI advisor) | Strategy, architecture review, early pilot scoping | Fast | Low, flexes with need | Moderate — depends on continuity of engagement |
| Contractor | Well-defined build tasks with clear scope and deadline | Fast to moderate | Low to medium, project-bound | Low — knowledge often leaves with the contract |
| Dedicated external pod | Validated initiatives needing sustained delivery (e.g. building and hardening a RAG pipeline) | Moderate | Medium, scoped to a defined phase | Medium to high — pod can transition capability to internal team |
| Permanent hire | Capability the business will need indefinitely and wants to own | Slow (recruitment cycle) | High, fixed cost | High — but only if the initiative is durable |
A useful rule of thumb: use fractional or contract support to answer "should we build this, and how," use a dedicated pod to answer "can we build and stabilise this quickly," and reserve permanent hiring for capability you're confident you'll need for years, not months. This mirrors the logic behind fractional CTO engagements more broadly — buying strategic depth without committing to a full-time role before you know the shape of the ongoing need.
How should capacity change as an AI initiative matures?
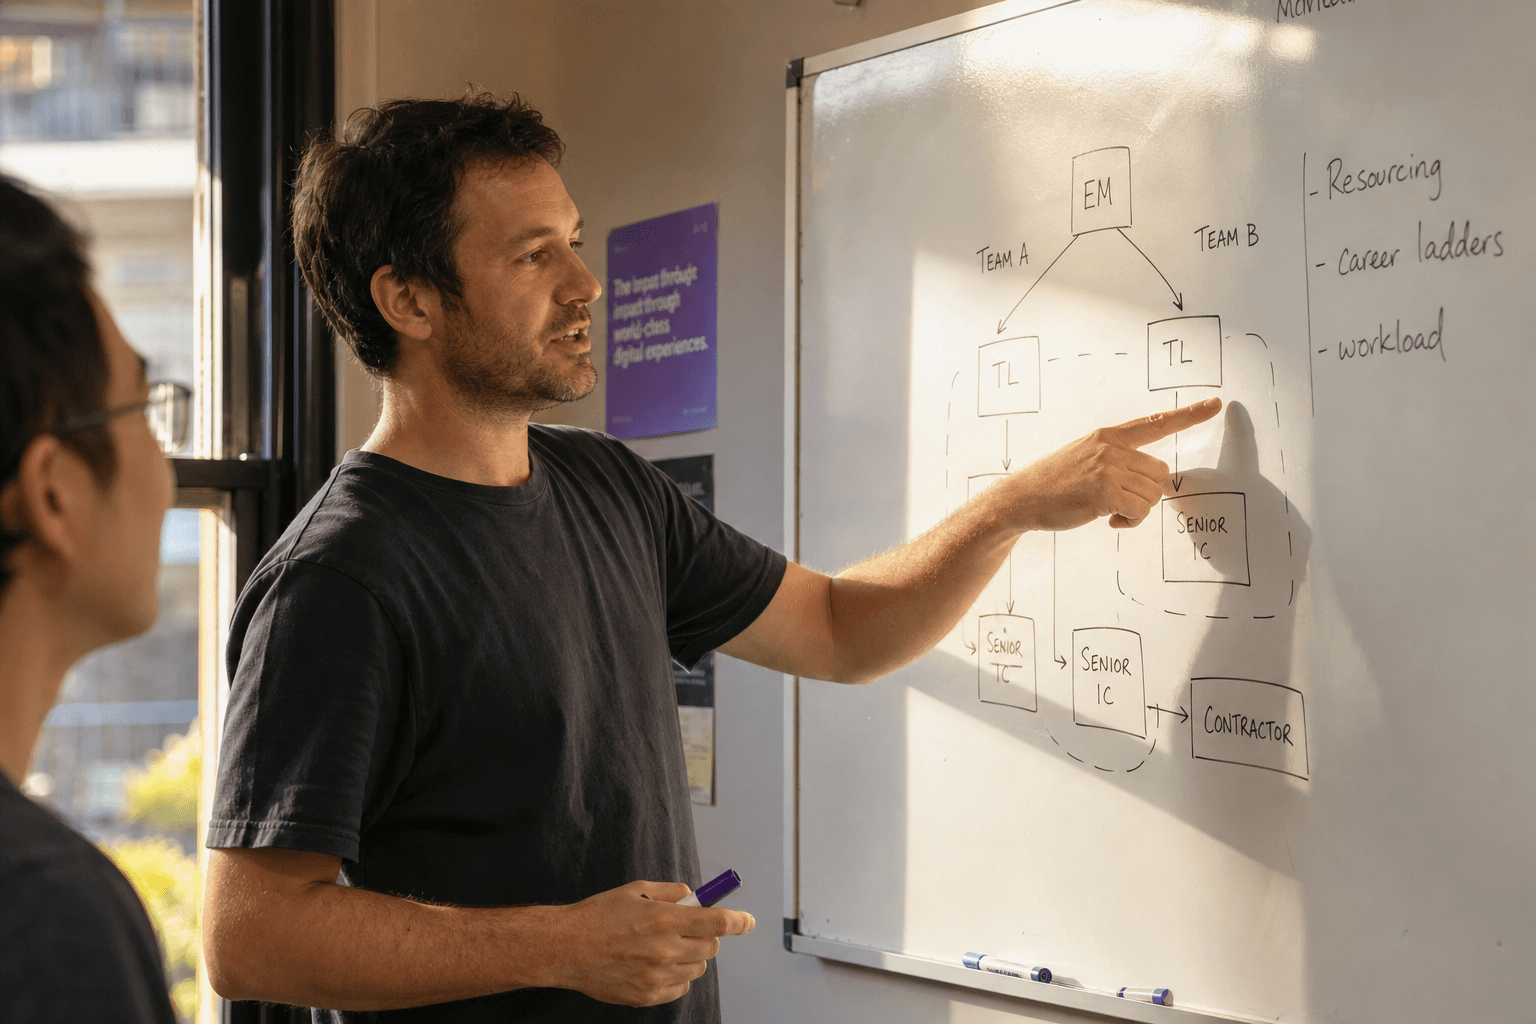
Capacity needs shift predictably as an initiative moves from idea to production, and treating every stage the same way is the most common source of over- or under-hiring. Early-stage work benefits from small, senior, flexible teams who can validate an approach quickly without locking in fixed cost. As an initiative moves toward production, capacity typically needs to expand to cover hardening, monitoring, and evaluation — the operational work that keeps a model or agent reliable once real users depend on it. At scale, the question shifts again: which parts of this capability does the business want to own permanently, and which can stay externally supported because the workload is intermittent rather than constant.
There's no single correct ratio of internal to external capacity, and any framework claiming otherwise is oversimplifying. What matters is revisiting the plan at each stage gate — pilot approval, production readiness, scale decision — rather than setting a team structure once and assuming it will still fit twelve months later. Organisations that build this review into their planning cycle tend to avoid both the over-hire and the stalled-pilot outcome described at the start of this piece.
If you're weighing up how to resource an AI initiative against an already-stretched engineering team, it helps to have that conversation with people who've built the capacity plans, not just the roadmaps. Read more insights on how growing Australian organisations are approaching AI adoption, or get in touch to talk through what capacity planning might look like for your team.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.