AI-Powered Warranty, Returns & Claims Automation for Retail
A practical guide to how AI can automate warranty validation, returns triage, and claims assessment for Australian retail and e-commerce operators — covering fraud risk, customer experience trade-offs, and integration with existing order management systems.
Returns and warranty claims are among the most operationally expensive parts of retail and e-commerce, yet they are often still run on manual review queues, spreadsheets, and tribal knowledge. AI can remove a lot of the repetitive triage work in this process — but it needs to be applied carefully, with fraud risk and customer trust both treated as first-class design constraints, not afterthoughts.
What is warranty, returns, and claims automation?
Warranty, returns, and claims automation is the use of software — increasingly AI-assisted software — to validate a customer's eligibility for a refund, replacement, or warranty repair, assess the evidence they provide, and route the case to the correct resolution path with minimal manual handling. The goal is not to remove human judgement entirely, but to reserve it for the cases that genuinely need it.
Why are retailers turning to AI for this now?
Manual returns and claims processing does not scale with order volume, and rules-only systems struggle with the variability of real-world evidence — damaged-item photos, inconsistent proof-of-purchase formats, and free-text customer descriptions. AI models, particularly those that can process images and unstructured text, let retailers handle this variability without proportionally growing the support team.
The retailers best placed to benefit are those with a high volume of low-complexity claims (wrong size, change of mind, minor defects) sitting alongside a smaller number of high-value or ambiguous cases. AI works well on the former. It should support, not replace, human reviewers on the latter.
What can AI actually automate, and where does it fall short?
AI is genuinely good at structured extraction and pattern matching: reading a receipt or order number from a photo, checking a serial number against a warranty database, flagging an image that doesn't match the claimed defect, or summarising a customer's free-text complaint for a reviewer. It is not reliable, on its own, for final adjudication of high-value, contested, or legally sensitive claims.
A practical automation boundary looks like this: auto-approve low-risk, low-value, policy-clear cases; auto-triage and summarise everything else for a human; and always keep a human decision point for anything involving fraud flags, warranty disputes, or claims above a defined value threshold. This mirrors the broader pattern we see across AI agents deployments generally — the highest-value automation is narrow, well-scoped, and paired with clear escalation paths, not a single model making every decision end to end.
How does AI-powered claims assessment actually work?
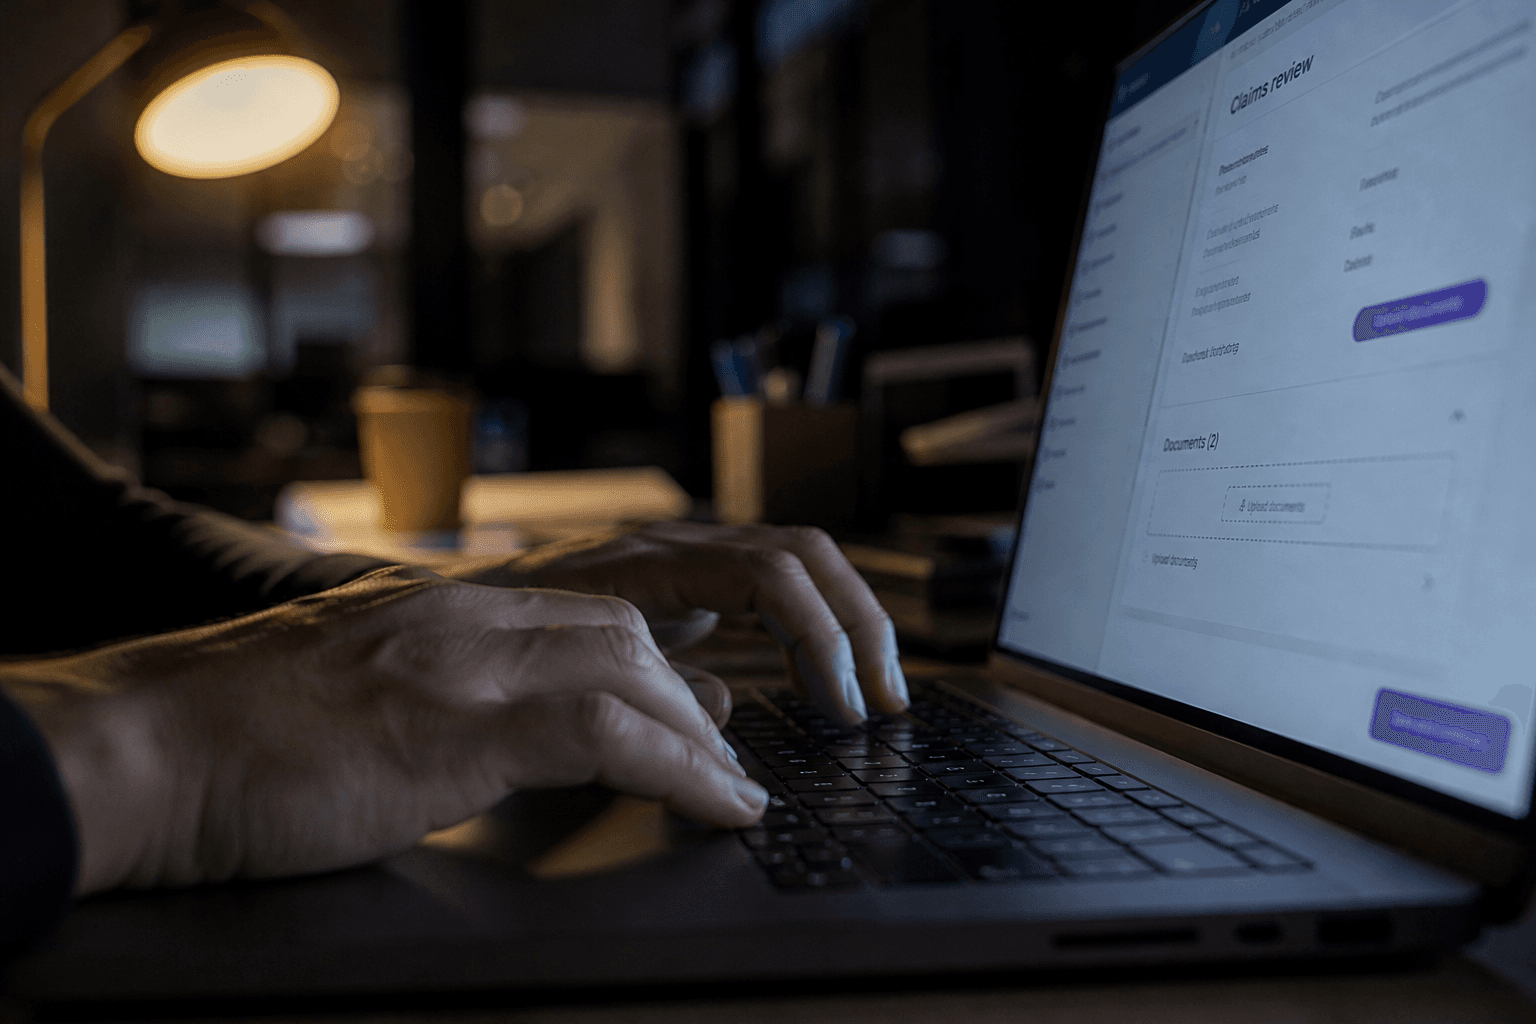
A typical claims pipeline combines several components: document and image understanding to extract order details and assess evidence, a rules or policy engine to check eligibility against warranty terms, a fraud-signal layer to flag anomalies, and a case management step that either auto-resolves the claim or routes it with context to a human agent. None of these components need to be a single large model — in many cases a combination of simpler, well-tested models and deterministic rules outperforms a single end-to-end AI system on cost, explainability, and auditability.
Choosing between a retrieval-based approach (grounding model outputs in your actual policy documents and order data) versus a more general model matters a lot here, for the same reasons we cover in RAG vs fine-tuning — claims decisions need to be traceable back to the specific policy clause or order record that justified them, not just a plausible-sounding model output.
What are the fraud risks of automating returns and claims?
Automating approvals without proportional fraud controls is the single biggest risk in this space. Return fraud and warranty abuse — including wardrobing, item-swap claims, and serial returners exploiting inconsistent policy enforcement — tend to concentrate in exactly the low-friction, fast-approval pathways that automation is designed to speed up. Any automation project needs fraud detection built in from day one, not bolted on afterwards.
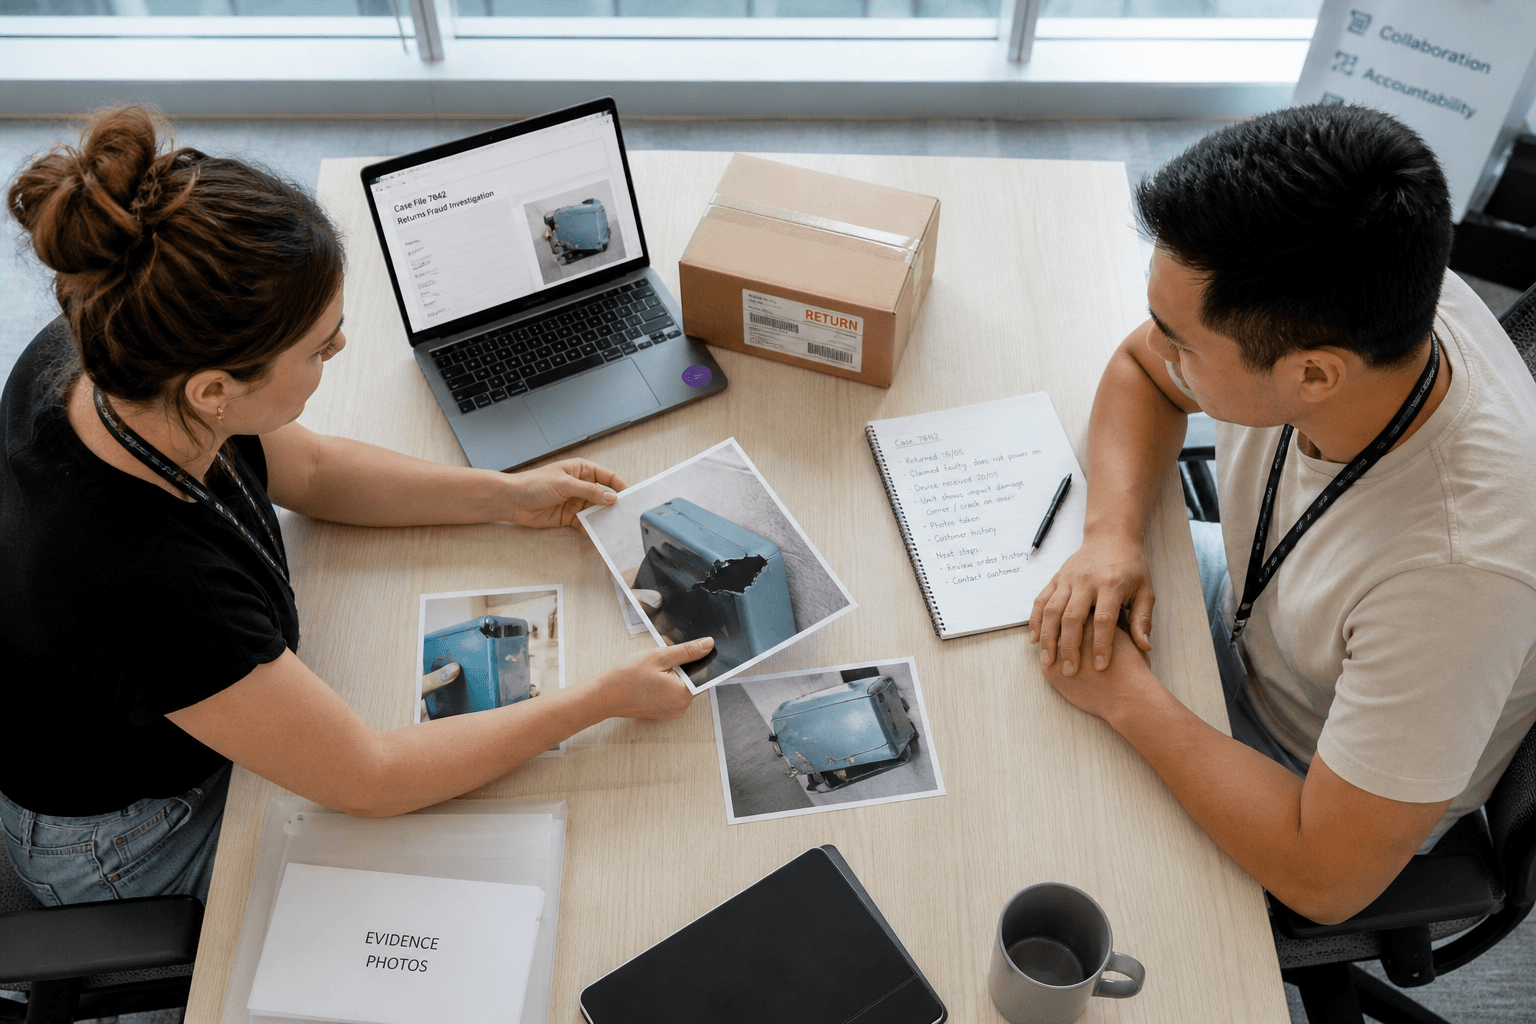
In practice this means layering signals: claim frequency per customer, inconsistencies between claimed and verified evidence, mismatches between delivery and return addresses, and anomaly detection on claim value relative to item history. It also means accepting that no fraud model is perfect — false positives (flagging legitimate customers) carry a real customer experience cost, and false negatives (missing genuine fraud) carry a real financial cost. The right threshold is a business decision, not a purely technical one, and it should be revisited regularly as fraud patterns shift.
What are the customer experience trade-offs?
Faster automated resolution is a genuine customer experience win when the claim is legitimate and low-risk — nobody enjoys waiting days for a straightforward refund. But over-aggressive automation that declines or delays legitimate claims because of a fraud false positive, or that gives customers no visible path to a human when something goes wrong, erodes trust quickly. The design question is not
If you're looking for guidance on this topic, get in touch — we're happy to help.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.