AI for Legal Case Management and E-Discovery, Explained
AI for legal case management and e-discovery helps teams classify and produce electronically stored information faster — but it doesn't replace human judgment on relevance, privilege, or production decisions. Here's what it actually does, where it goes wrong, and how it needs to integrate with existing practice management systems.
AI for legal case management and e-discovery refers to software that uses machine learning and natural language processing to help legal teams run matters and manage litigation document workloads. In case management, that means organising matter data, deadlines, and billing records. In e-discovery, it means identifying, classifying, and producing electronically stored information (ESI) that is relevant to litigation or investigation — ranking documents by likely relevance, flagging potential privilege, and integrating with the practice management systems a firm already runs on. It does not replace legal judgment. It narrows the document population a human reviewer has to assess, with a person making the final call on every production and privilege decision.
Most discussion of AI in legal technology still centres on contract review — clause extraction, risk scoring, redline suggestions. That's a narrower and, frankly, easier problem than what litigation teams and in-house legal functions actually spend their time on. This guide looks at where AI genuinely helps in case management and e-discovery workflows, where accuracy and privilege risk demand caution, and how any AI layer needs to sit alongside the systems a firm already depends on.
What is e-discovery AI and how is it different from contract review AI?
Contract review AI works on a bounded, structured document type — contracts — with a relatively stable vocabulary of clauses and obligations. E-discovery AI works on an open-ended, heterogeneous document population: emails, chat logs, spreadsheets, scanned PDFs. The task is relevance and privilege classification under time pressure, not clause extraction, and the document set is rarely consistent from one matter to the next.
That difference matters more than it sounds. A contract review model can be validated against a known set of clause types. An e-discovery review model has to generalise across document formats, writing styles, and context it has never seen before, often within a single matter's discovery deadline. The stakes of a missed or misclassified document are also different in kind: in contract review, an error is usually commercial. In e-discovery, a missed privileged document or a wrongly produced one can have direct legal and professional consequences.
What accuracy can law firms realistically expect from AI-assisted document review?
AI-assisted review (sometimes called technology-assisted review or predictive coding) is a supervised learning process where a model ranks or classifies documents by likely relevance, trained on decisions made by a senior reviewer on a sample set. It can meaningfully reduce the volume of documents a human needs to look at manually, but it does not eliminate human review, and its accuracy is only as good as the seed set and the ongoing quality control applied to it.
Firms should expect — and plan for — an iterative validation cycle: sample-based quality checks, disagreement analysis between the model and human reviewers, and documented decisions about the confidence threshold used to cut off manual review. Courts and regulators generally expect a defensible, documented methodology rather than a specific accuracy number, because no public, independently verified accuracy benchmark exists that applies uniformly across matters, document types, and review tools. Treat any vendor claim of a fixed accuracy percentage with scepticism unless it's tied to validation performed on your own document population.
What privilege risks does AI introduce into e-discovery workflows?
Legal professional privilege protects confidential communications made for the dominant purpose of giving or obtaining legal advice, or for use in litigation. AI privilege review tools classify documents as privileged, non-privileged, or uncertain, based on patterns learned from training examples — but privilege is a legal judgment, not a pattern-matching exercise, and the two don't map perfectly.
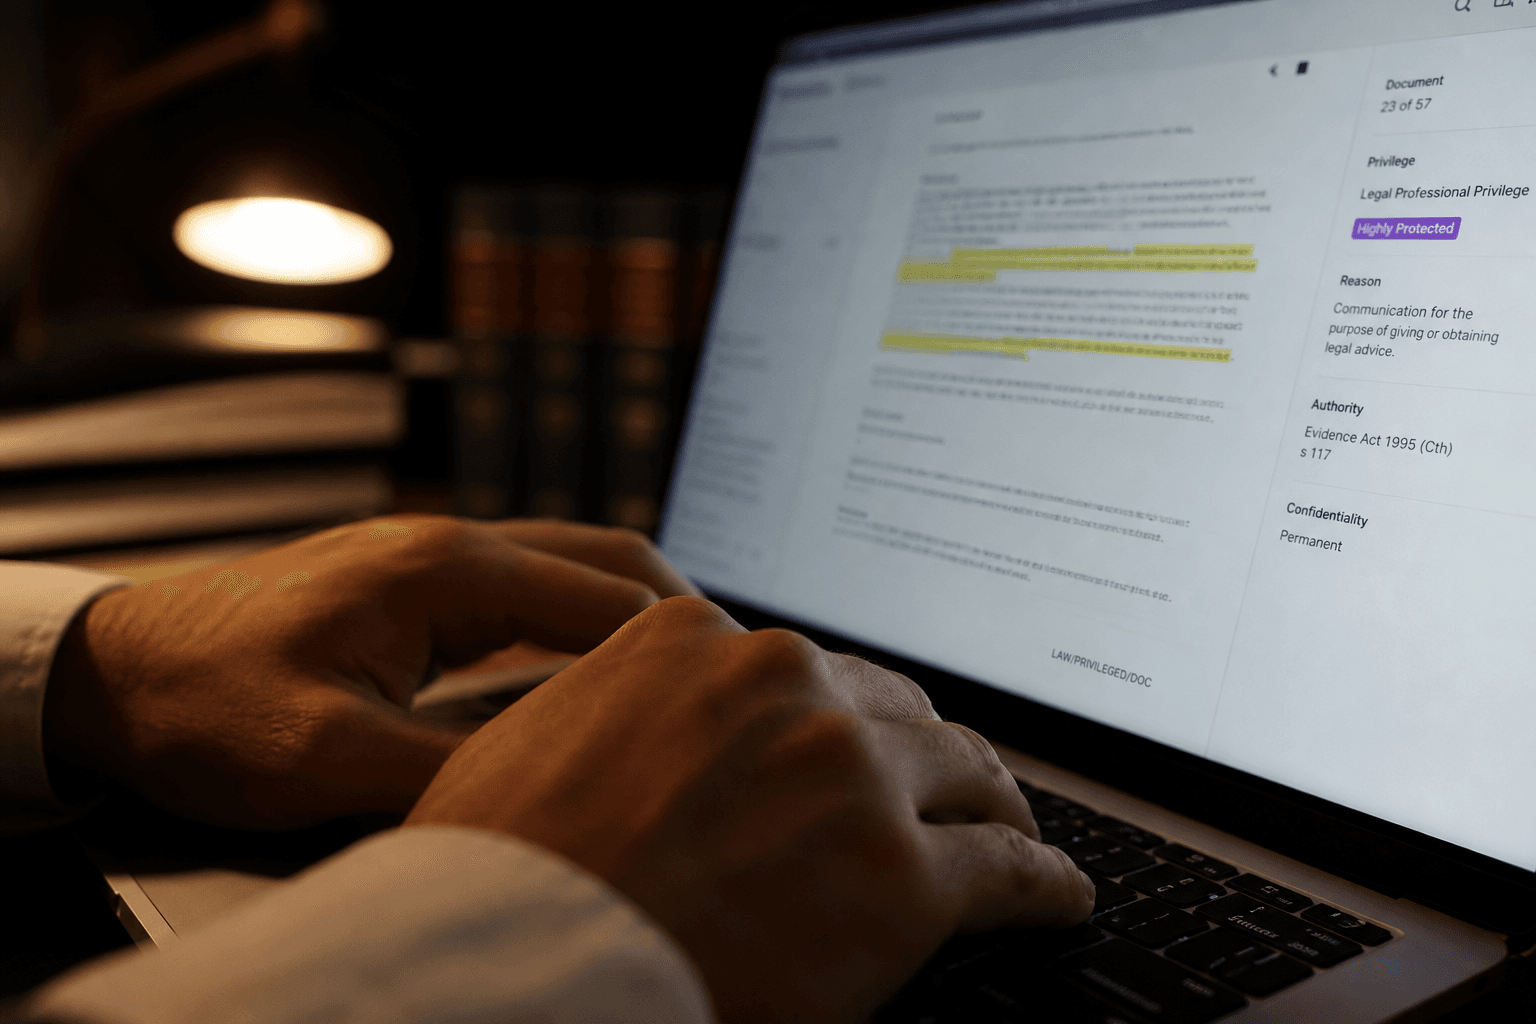
The practical risk is twofold. First, false negatives: a privileged document gets classified as producible and is inadvertently disclosed, which can trigger waiver arguments depending on jurisdiction and the steps taken to claw it back. Second, false positives at scale: over-withholding documents on privilege grounds can draw challenge from the opposing party or the court. Any AI-assisted privilege workflow needs a human-in-the-loop checkpoint before production, a clear audit trail of how classification decisions were made, and clawback or non-waiver agreement protocols agreed up front. The AI narrows the review population; it doesn't make the privilege call.
How does AI integrate with existing practice management systems?
Case management systems hold matter data, deadlines, document indexes, and billing records; e-discovery platforms handle collection, processing, and review. For an AI layer to be useful rather than a parallel system nobody trusts, it needs to read from and write back to whatever practice management or document management system the firm already runs — not sit as a disconnected tool that requires re-keying matter metadata or exporting document sets.
In practice this is an integration and data engineering problem as much as an AI one: consistent matter identifiers, access controls that respect ethical walls and conflict checks, and audit logging that satisfies both the court and the firm's own risk function. Firms evaluating AI tools for case management or e-discovery should ask the vendor directly how the tool integrates with their existing practice management system, what data it stores outside that system, and who can see what.
| Dimension | Contract review AI | Case management / e-discovery AI |
|---|---|---|
| Document population | Bounded, structured (contracts) | Open-ended, heterogeneous (email, chat, scans) |
| Primary task | Clause extraction, risk scoring | Relevance and privilege classification |
| Error consequence | Mostly commercial | Potentially legal and professional |
| Validation basis | Known clause taxonomy | Sample-based review of an evolving document set |
| Integration need | Document repository | Practice management, document management, and matter systems |
This is the kind of problem we see across legal technology and other regulated sectors: the AI model is rarely the hardest part. The harder part is the surrounding engineering — connecting models to legacy systems, maintaining audit trails, and keeping humans in the loop at the right checkpoints. That work spans ai product strategy to decide where AI genuinely helps versus where it introduces risk, ai engineering to build and validate the models and review pipelines, and application modernisation where case management platforms are old enough that integration itself is the bottleneck.
If you're assessing AI tools for case management or e-discovery, start with the integration question, not the accuracy claim. A tool that can't connect cleanly to your existing systems, or that can't show you a defensible validation methodology on your own documents, isn't ready for production use in a legal workflow — no matter what the vendor demo shows.
For more on how organisations evaluate AI readiness and where it does and doesn't fit, see more insights. If you're working through where AI fits in your legal technology stack, or how to integrate it with systems you already run, get in touch — we're happy to talk through what we've seen work and where the real risks sit.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.