AI-Assisted Rostering for Logistics and Field Service Teams
AI-assisted rostering can reduce overtime, travel time, and missed service windows for logistics and field-service operators — but only with the right data foundations and constraint models. Here's what's actually involved, and how it fits with existing dispatch systems.
What is workforce rostering optimisation?
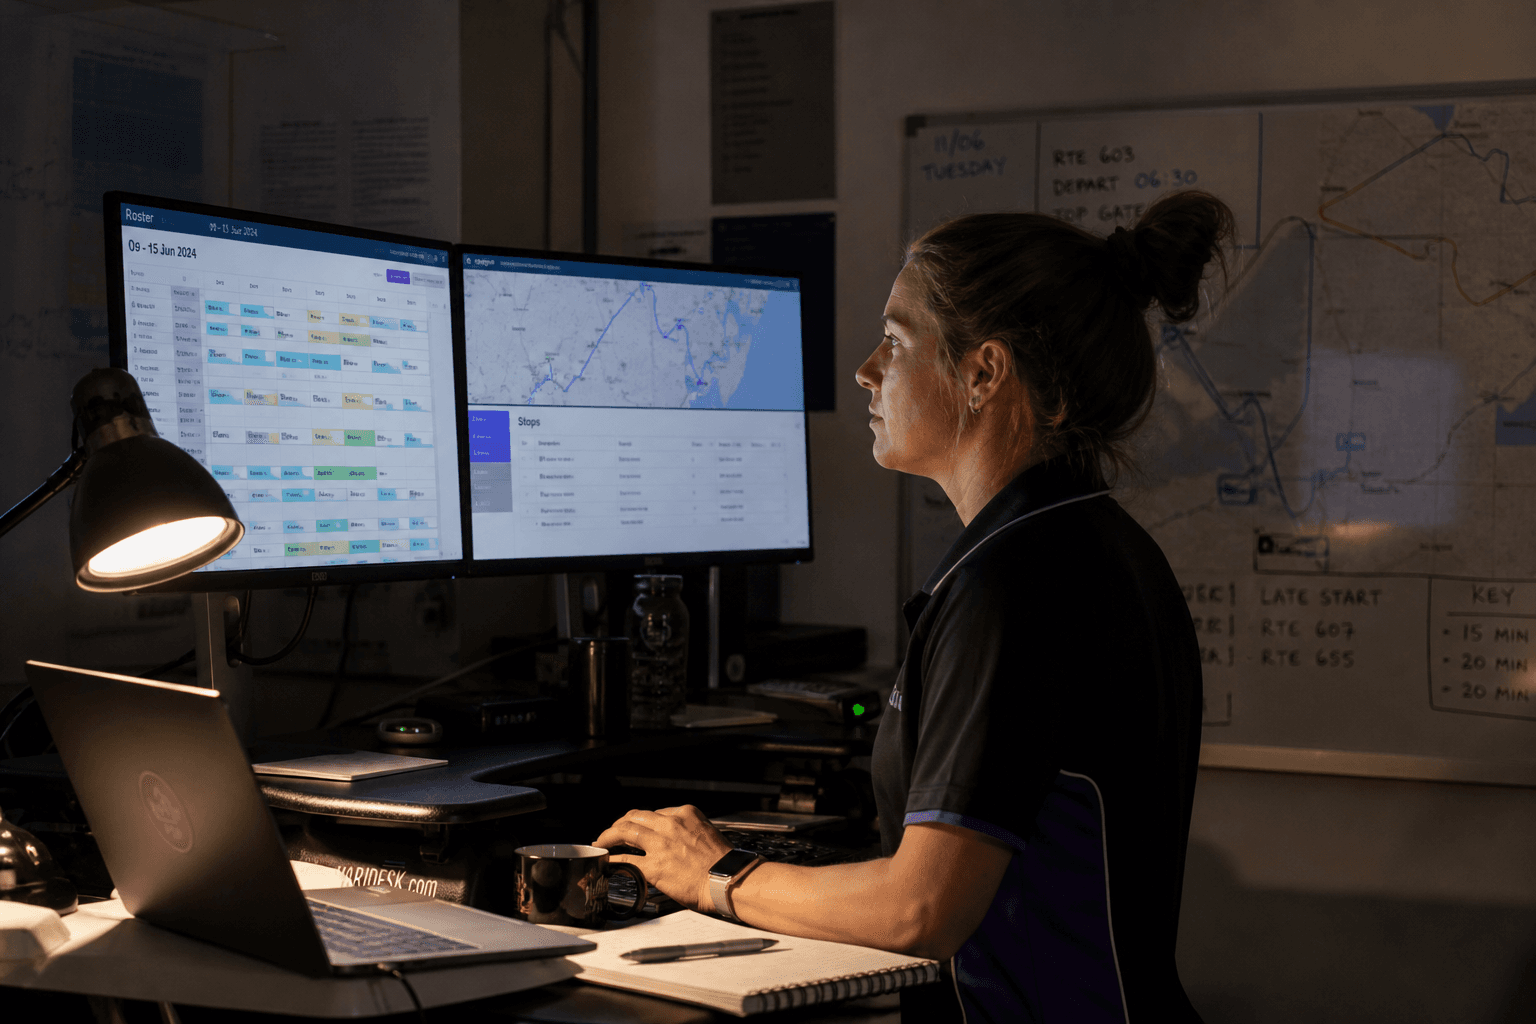
Workforce rostering optimisation is the process of using data and algorithms to assign the right people to the right shifts, routes, or jobs, while satisfying operational constraints such as skills, availability, travel time, and compliance rules. For logistics and industrial operators, this usually means matching drivers, technicians, or crews to jobs in a way that reduces idle time, overtime, and missed service windows — without breaching award conditions or safety limits.
Most operators already have a rostering system. The problem is rarely the absence of a tool — it's that the tool relies on static rules or manual judgement, and can't adapt quickly when a truck breaks down, a technician calls in sick, or ten new jobs land after the roster is locked. AI-assisted scheduling doesn't replace the dispatcher's judgement; it narrows the search space so a good roster can be found in minutes rather than hours, and re-optimised as conditions change through the day.
Why is field-service and logistics rostering so hard to get right?
Rostering in logistics and field service is a constraint satisfaction problem with a large number of variables that interact non-linearly. A change to one job's time window can cascade through dozens of other assignments. Traditional spreadsheet or rules-based rostering handles the common case well but breaks down at the edges — which is exactly where the cost and risk sit.
The variables typically include:
- Staff skills, certifications, and equipment access (not every technician can do every job)
- Fair Work award rules, minimum rest periods, and overtime thresholds
- Vehicle or equipment availability and maintenance windows
- Geographic clustering and travel time between jobs
- Customer time windows and service-level agreements
- Real-time disruptions — breakdowns, absences, traffic, weather
A human planner can reason about two or three of these at once. An optimisation engine can reason about all of them simultaneously, and recompute when something changes — which is the core value proposition over manual or purely rules-based scheduling.
What data do you actually need before you can optimise?
Useful rostering optimisation depends on clean, structured data about people, jobs, and constraints — not a perfect data warehouse, but a reliable source of truth for the inputs that actually drive decisions. Most operators underestimate how much of this already exists in fragmented form across HR systems, dispatch tools, and spreadsheets, and overestimate how much new data collection is required.
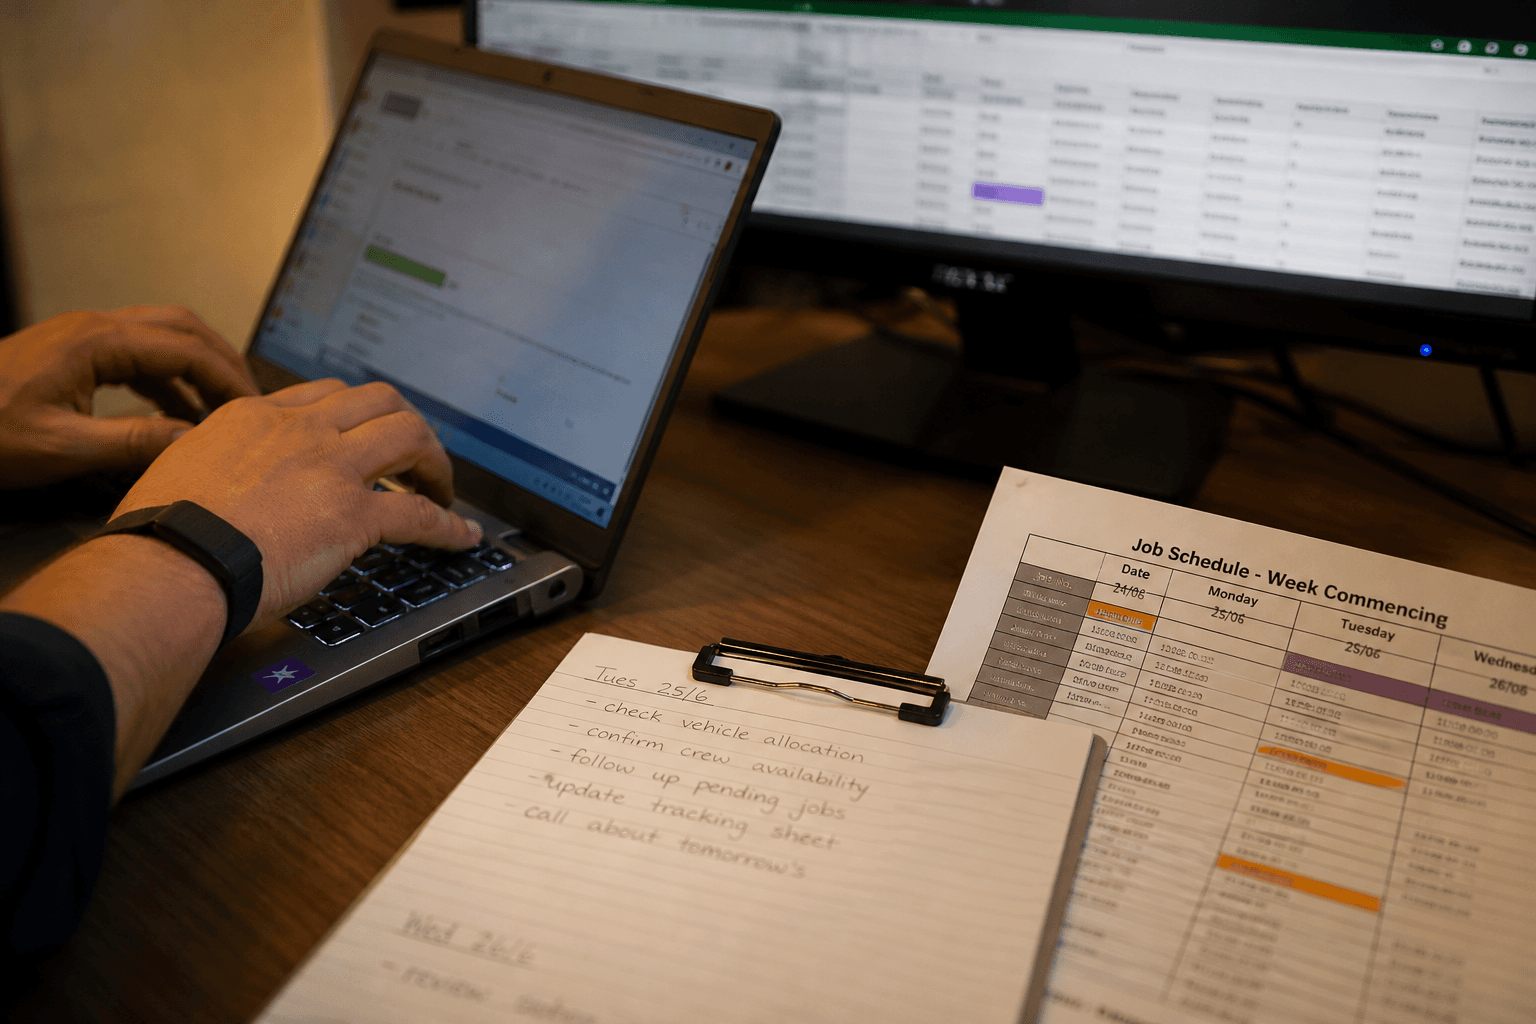
At minimum, you need:
- Workforce data — skills, certifications, home base, contracted hours, leave balances, and award or enterprise agreement rules that apply to each worker.
- Job or demand data — job type, duration estimate, location, required skills, time windows, and priority or SLA tier.
- Asset data — vehicle, tool, or equipment availability if jobs depend on shared resources.
- Historical performance data — actual job durations versus estimates, travel time variance, and no-show or reschedule rates, used to calibrate the model rather than rely on optimistic planning assumptions.
- Real-time status feeds — GPS or telematics, job completion events, and exception flags from the field.
If this data is scattered across legacy systems with no consistent identifiers, the optimisation project becomes a data integration project first. This is common, and it's worth treating as a distinct phase rather than a blocker — our data-infrastructure work is often the precursor to a rostering optimisation build, not a parallel track.
How does constraint modelling actually work?
Constraint modelling means encoding the rules that make a roster valid or invalid — hard constraints that can never be broken, and soft constraints that should be minimised but can be traded off against each other. A well-modelled system separates these explicitly, so the optimisation engine knows which rules are non-negotiable and which are preferences.
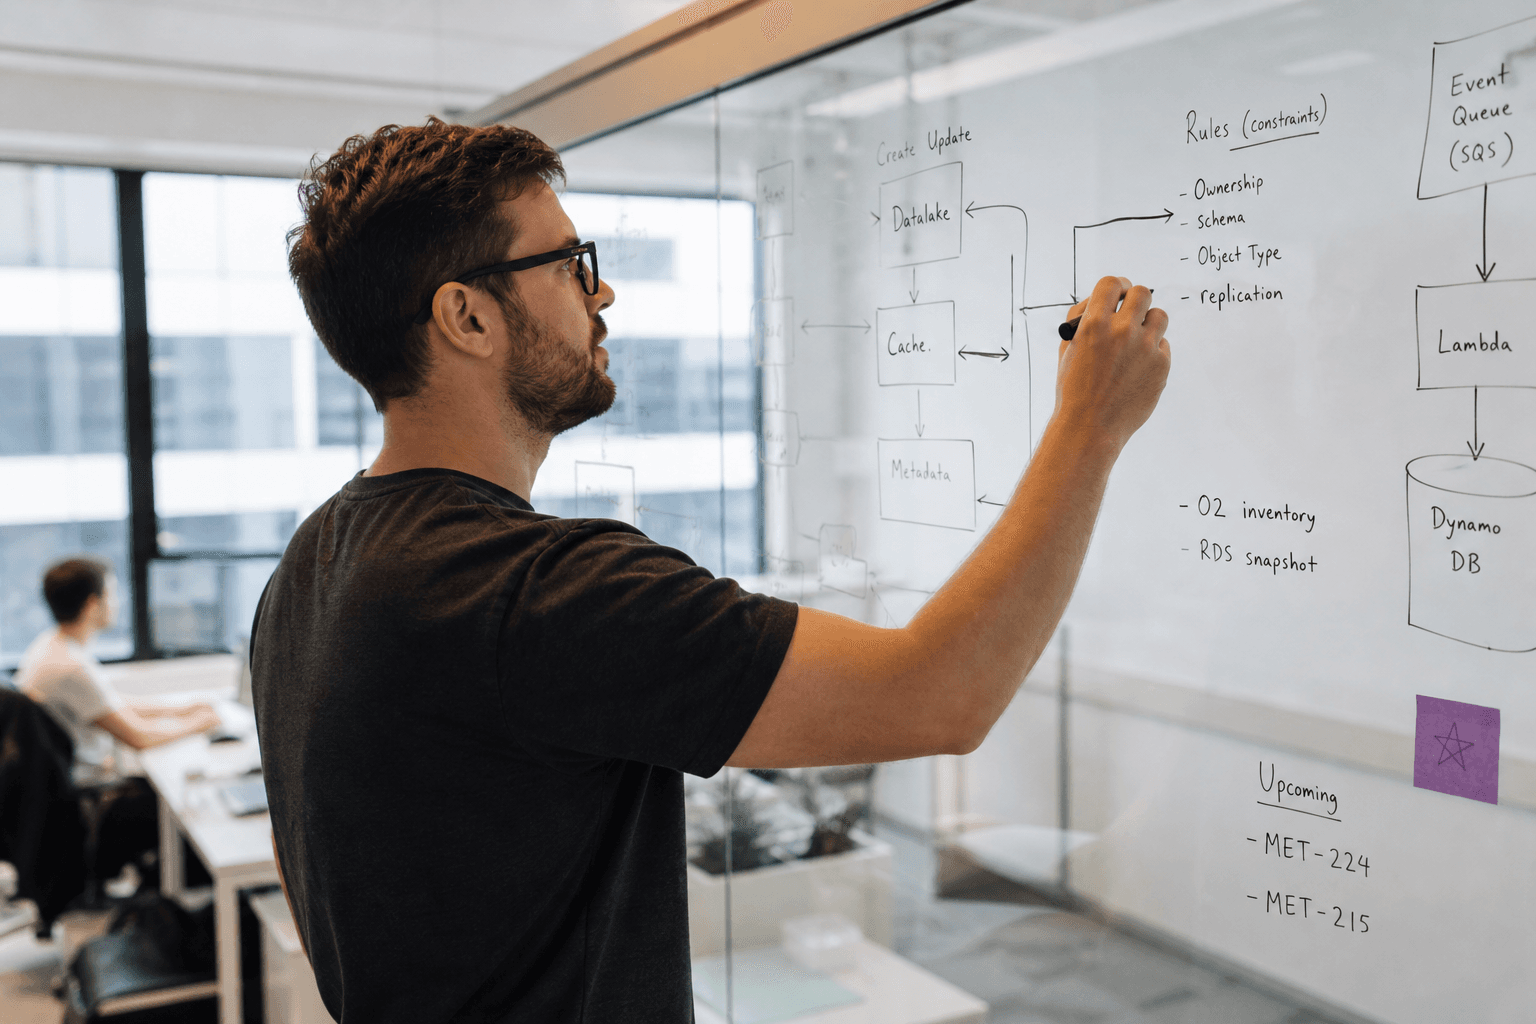
Hard constraints typically include legal and safety requirements: minimum rest between shifts, maximum consecutive hours, mandatory qualifications for hazardous work. Soft constraints are the things you'd like to minimise — total travel distance, overtime hours, split shifts, or deviation from a worker's preferred roster pattern. The optimisation engine, whether it's a mathematical solver, a constraint programming approach, or a learned heuristic, searches for an assignment that satisfies every hard constraint while scoring as well as possible against the weighted soft constraints.
Getting the weighting right is where most of the iteration happens. An engine that over-weights cost minimisation will produce rosters that are efficient on paper but exhausting in practice, with high attrition as the downstream cost. This is a modelling and change-management exercise as much as a technical one, and it's why we treat the first phase of any engagement as ai-product-strategy work — defining what
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.