Cloud Repatriation for AI Workloads: A Decision Guide
Cloud repatriation — moving AI and data workloads from public cloud back to owned or colocated infrastructure — is worth modelling for specific high-utilisation workloads, not as a blanket strategy. Here's how engineering leaders should weigh the cost drivers, latency gains, and migration risks.
Cloud repatriation is back in the conversation among Australian engineering leaders running AI and data-intensive systems. After a decade of cloud-first defaults, some teams are asking a harder question: does keeping every workload in public cloud still make financial sense, or is it time to bring some of it home?
This is not a call to abandon public cloud. For most workloads, the elasticity, managed services, and reduced operational burden of AWS, Azure, or GCP remain the right default. But AI and data workloads have cost and performance characteristics that differ from typical web application traffic, and those differences are exactly where repatriation economics start to shift.
What is cloud repatriation?
Cloud repatriation is the process of moving workloads, data, or infrastructure from a public cloud provider back to on-premises or colocated infrastructure that an organisation owns or directly controls. It is the reverse of the cloud migration most organisations completed over the past ten to fifteen years, and it is typically partial rather than total — specific workloads move, not the whole estate.
The decision is rarely ideological. It is driven by a handful of measurable cost and performance factors that become more visible as AI and data workloads scale: sustained compute utilisation, data transfer patterns, and latency requirements that public cloud's pricing and architecture were not originally optimised for.
When does repatriation make financial sense for AI workloads?
Repatriation tends to make financial sense when a workload runs at high, predictable utilisation over a long time horizon — the opposite of the bursty, unpredictable traffic that cloud elasticity is designed for. GPU-intensive training or inference pipelines that run continuously are the clearest candidate, because public cloud's on-demand pricing model is built to reward variability, not steady-state load.
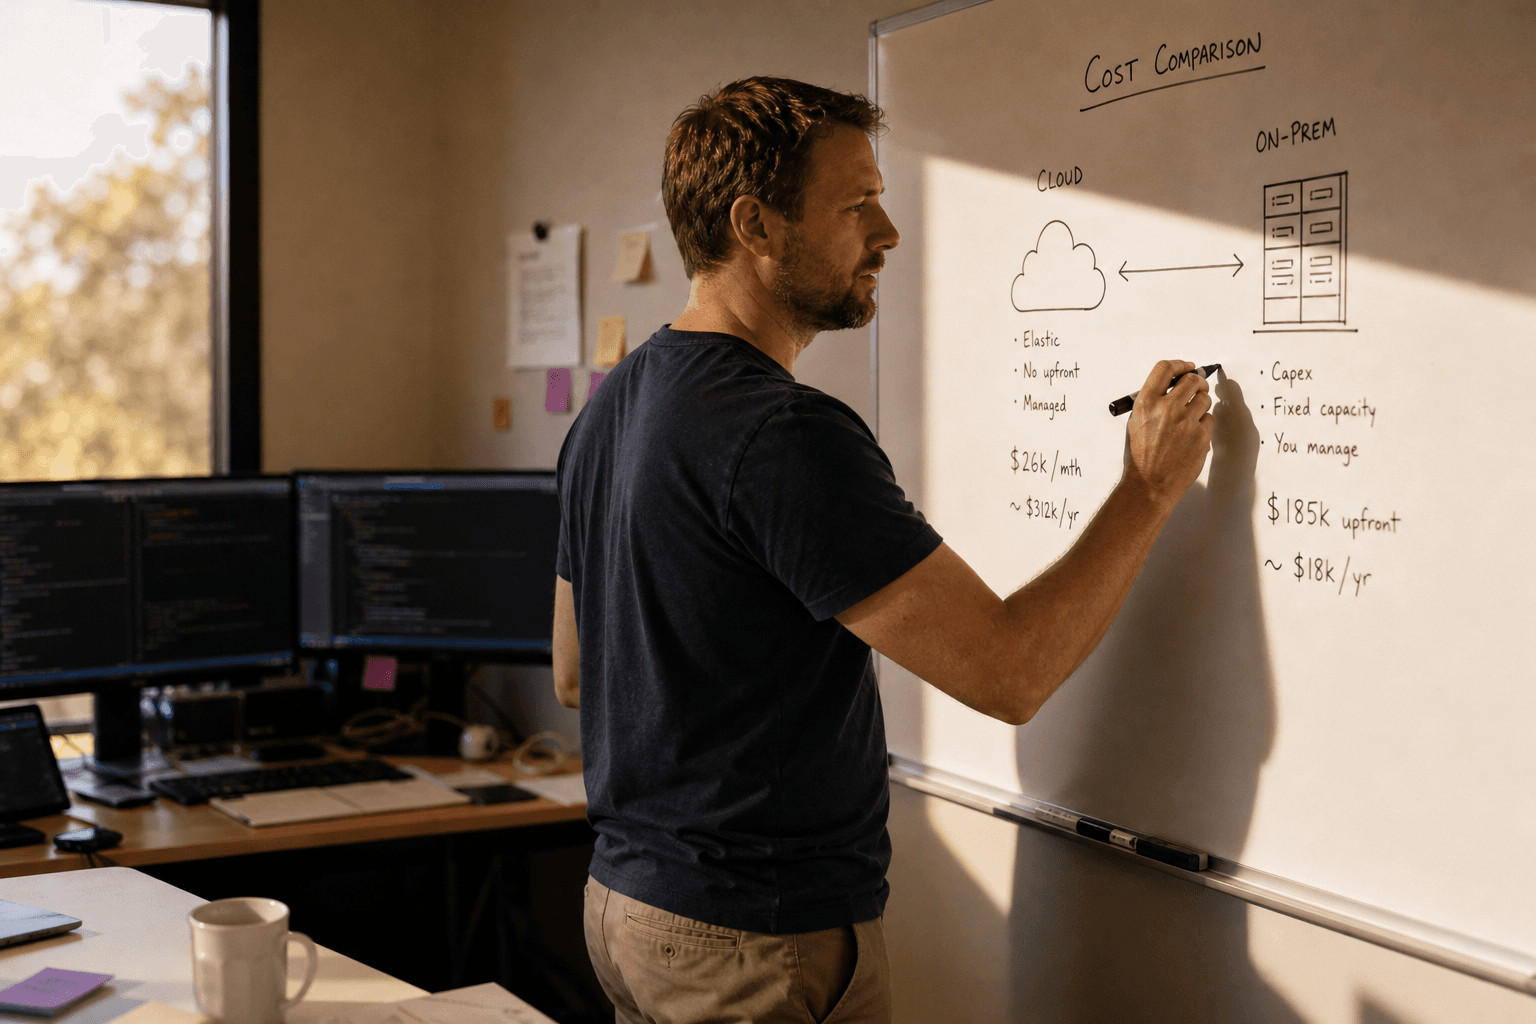
The core cost drivers worth modelling before making a call are:
- Sustained GPU or compute utilisation. If training or inference infrastructure runs near-constantly rather than in short bursts, the premium organisations pay for cloud elasticity stops buying anything useful. Owned or colocated hardware amortised over several years can carry a lower total cost of ownership for this specific pattern — but only if utilisation stays high; idle owned hardware is the fastest way to erase any saving.
- Data egress fees. Public cloud providers charge for data leaving their network, and AI pipelines that move large training datasets, model checkpoints, or inference outputs between regions or back to on-premises systems can accumulate meaningful egress costs over time. This is a genuine structural cost of the public cloud model, not a hypothetical one.
- Data gravity. Data gravity is the tendency for applications, analytics, and services to cluster around the location of the data they depend on, because moving large datasets is expensive and slow. Once an organisation has accumulated a large volume of training data or a data lake in one location, the cost of keeping compute close to that data — wherever it lives — starts to outweigh the convenience of defaulting to cloud for everything new.
- Compliance-driven data residency. Some Australian regulatory regimes constrain where certain data can be processed or stored. Organisations handling health records need to consider obligations under the My Health Records Act, financial services firms operate under APRA's CPS 234 information security standard, and the Privacy Act 1988 (Cth) sets baseline obligations for personal information regardless of industry. None of these automatically mandate on-premises infrastructure — AWS, Azure, and GCP all offer Australian regions — but they do require organisations to know precisely where data sits and who can access it, and that clarity is sometimes easier to guarantee on infrastructure you control directly.
Does repatriation improve latency for AI and data systems?
Latency improvements from repatriation are real but workload-specific, and they depend more on physical proximity between compute and data than on the cloud-versus-on-premises question itself. Co-locating inference infrastructure next to the data or devices it serves typically reduces round-trip latency more than the underlying ownership model does.
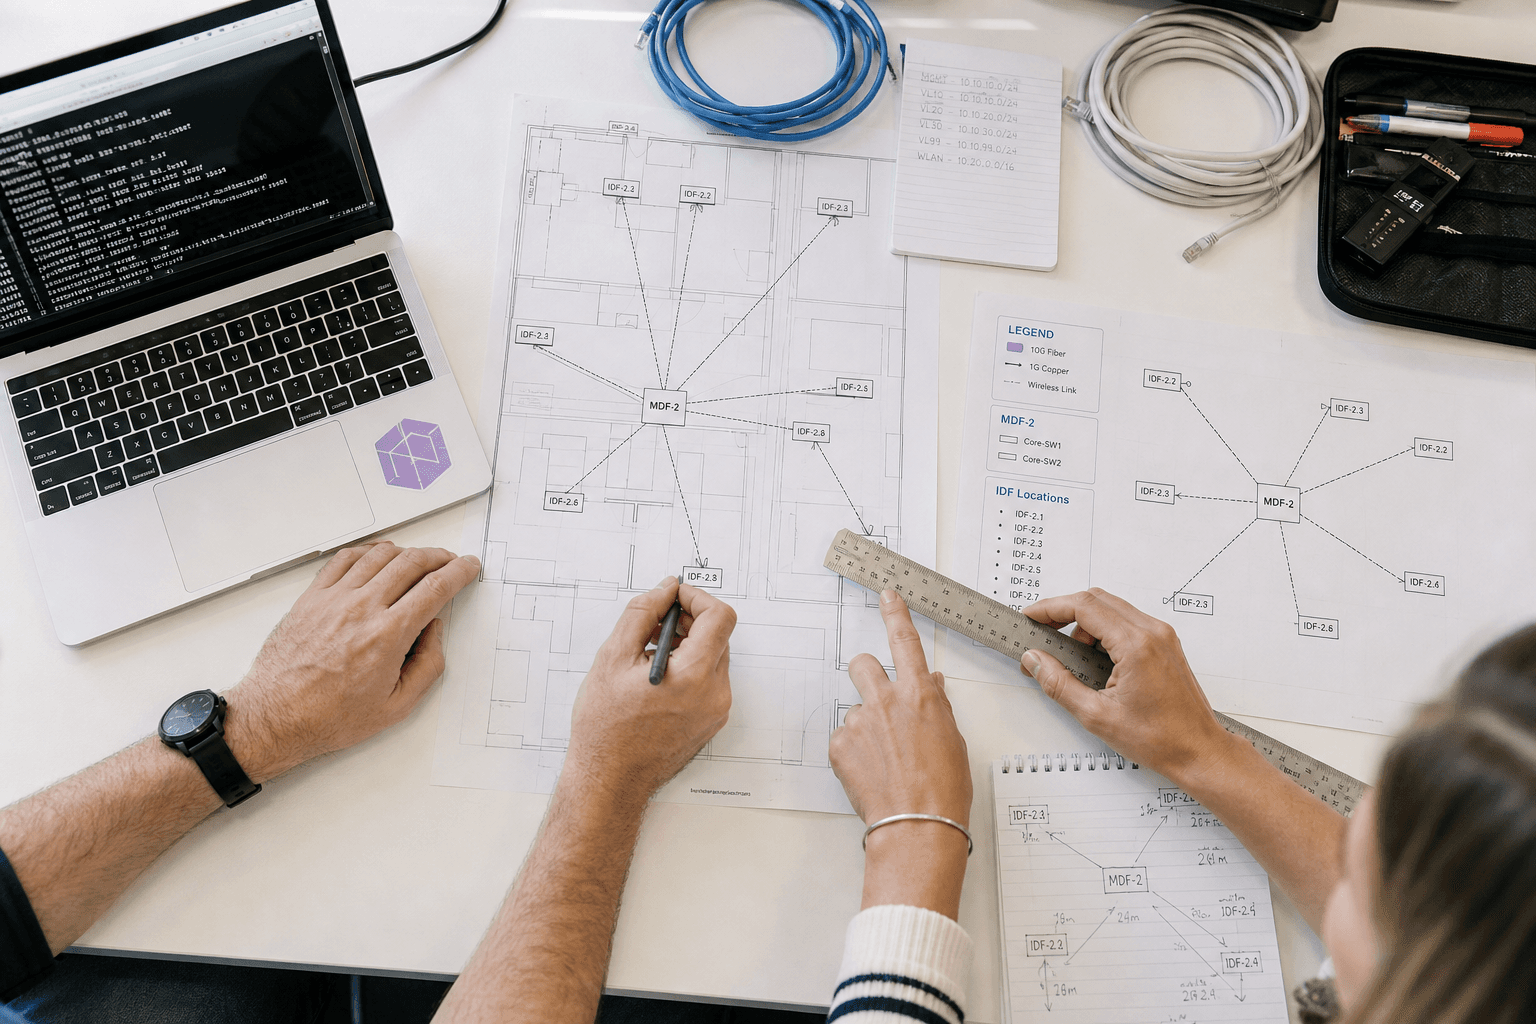
For real-time inference serving latency-sensitive applications — fraud detection at the point of transaction, industrial sensor processing, or logistics routing — the relevant variable is network distance and contention, not whether the hardware is leased or owned. A well-placed colocation facility near the data source can outperform a public cloud region simply because the physical path is shorter and more predictable. This is a networking and architecture decision as much as a financial one, and it is worth modelling separately from the pure cost case.
What are the risks of a repatriation migration?
Repatriation carries real migration risk, and treating it as a simple reversal of the original cloud migration understates the work involved. Organisations that move too quickly, or move the wrong workloads, often end up with higher total costs and lower reliability than before.
The main risks to plan for:
| Risk area | What tends to go wrong |
|---|---|
| Utilisation forecasting | Owned or colocated hardware is only cheaper at sustained high utilisation; demand that turns out to be bursty erases the saving |
| Operational capability | Running hardware, networking, and failover without cloud-managed services shifts operational burden back onto the engineering team |
| Hidden costs | Power, cooling, hardware refresh cycles, and physical security are easy to underweight against a clean cloud invoice |
| Partial migration complexity | Hybrid architectures that split workloads between cloud and owned infrastructure add integration and data-sync overhead |
| Compliance verification | Moving infrastructure does not automatically satisfy a compliance obligation — residency and access controls still need to be designed and evidenced |
The Australian Cyber Security Centre publishes guidance on cloud and infrastructure security that is a useful starting point for organisations weighing the security implications of either direction — cyber.gov.au covers baseline controls relevant regardless of where infrastructure sits.
How should engineering leaders approach the decision?
The right approach is to model the economics of specific workloads rather than making a single enterprise-wide call. Cost and latency drivers vary enormously between a steady-state training pipeline, a bursty analytics workload, and a latency-sensitive inference service, so a workload-by-workload assessment will surface genuine repatriation candidates without disrupting everything that is working well in the cloud.
In practice, this means building an honest utilisation and cost model for each AI or data workload under consideration, checking it against actual egress and data-gravity patterns, and treating compliance requirements as a design constraint rather than an afterthought. Organisations building out data infrastructure or scaling AI engineering work are well placed to run this analysis early, before workload growth makes the eventual migration more disruptive. For teams carrying legacy platforms alongside newer AI systems, this decision often overlaps with broader application modernisation planning, since the same workloads are frequently candidates for both re-architecture and infrastructure relocation.
We deliberately have not put invented dollar figures or percentage savings in this piece — anyone offering a universal repatriation ROI number without seeing your actual workload data is guessing. The honest answer is that repatriation is worth modelling for specific high-utilisation, data-gravity-heavy, or latency-sensitive workloads, and rarely worth it as a blanket strategy.
If you're weighing a repatriation decision for AI or data workloads and want a second opinion grounded in your actual usage and cost data, get in touch — we can help build the model before you commit to a migration. You can also browse our insights for more on data infrastructure and AI engineering decisions facing Australian technical leaders.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.