Responsible Disclosure & Bug Bounties for AI SaaS
AI features introduce attack surface — prompt injection, data exfiltration via retrieval, system prompt leakage — that most existing disclosure policies and bug bounty scopes don't cover. Here's how to close that gap.
What is responsible disclosure, and why does AI change it?
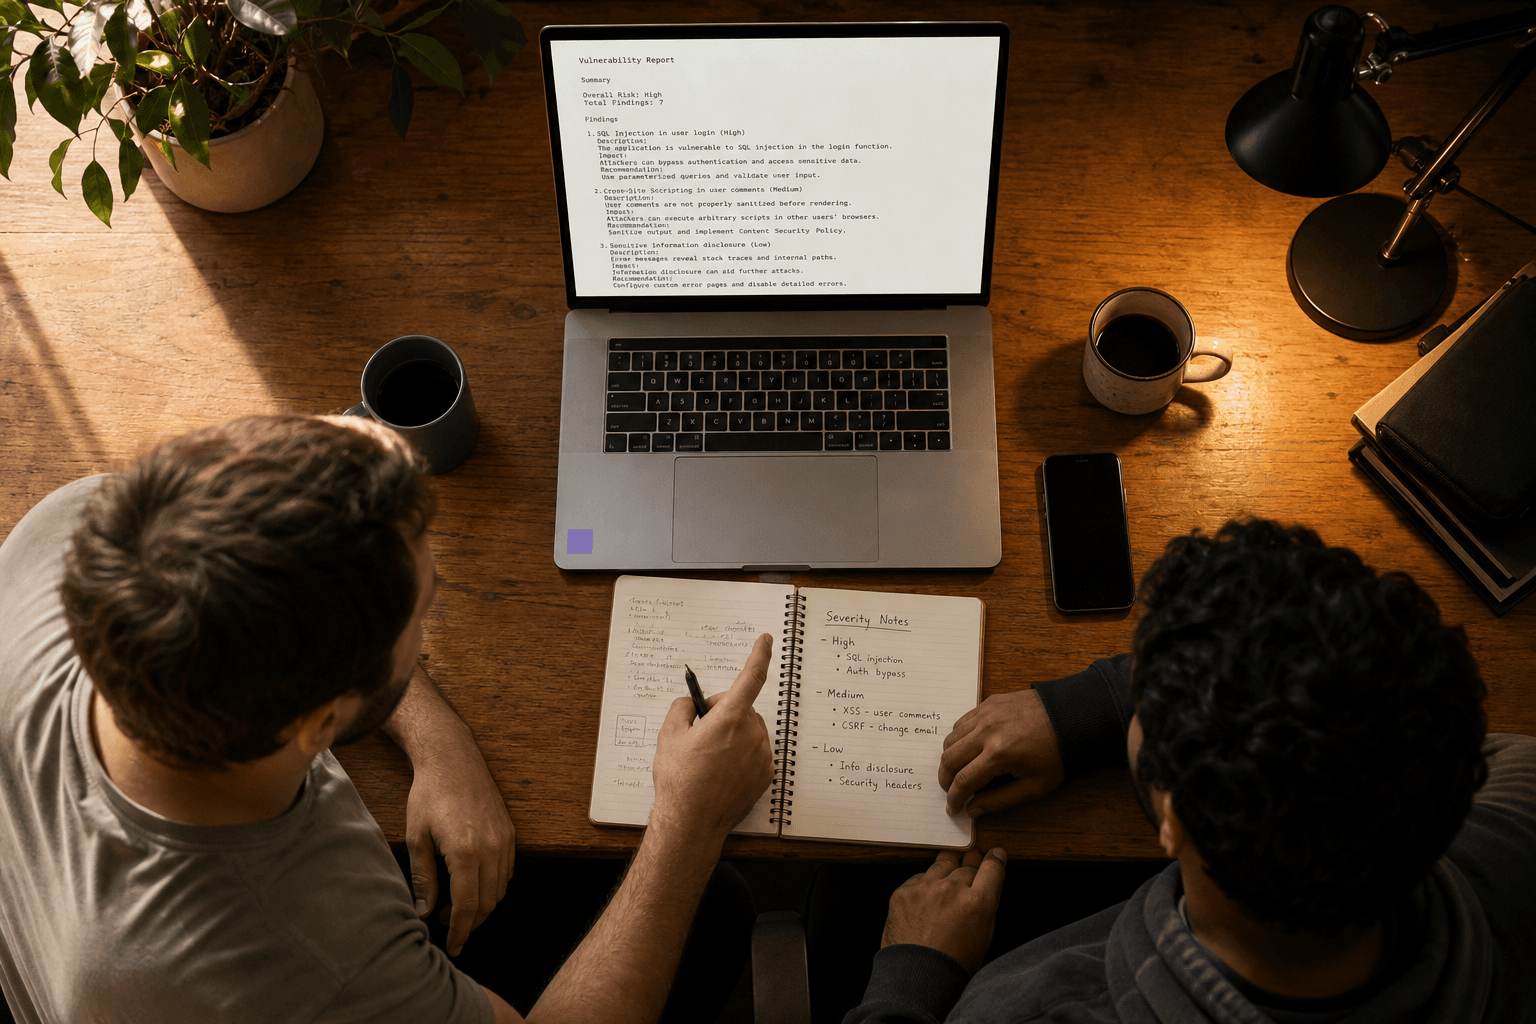
Responsible disclosure is a coordinated process where security researchers report vulnerabilities privately to an organisation, giving it time to fix the issue before any public disclosure. A bug bounty program is the structured, often financially incentivised version of this process, with defined scope, reward tiers, and response commitments. AI features change what counts as a vulnerability — and that means your existing policy probably doesn't cover it.
Most disclosure policies were written for traditional web application risks: SQL injection, broken authentication, insecure direct object references. Large language model (LLM) features introduce a different class of failure — the model itself can be manipulated through natural language input, and the boundary between "user content" and "system instruction" is far less clean than in conventional software. If your policy and bounty scope haven't been updated since you shipped an AI feature, there is a real gap between what researchers can find and what your program tells them to report.
How does prompt injection expand your attack surface?
Prompt injection is an attack where crafted input causes an LLM to ignore its intended instructions and instead follow instructions embedded in the input — whether that input comes directly from a user or indirectly from a document, email, or web page the model retrieves and processes. This matters for disclosure programs because prompt injection often doesn't look like a traditional bug. There's no stack trace, no crashed server, no obvious data breach — just a model that did something it wasn't supposed to do.
This creates two practical problems for a vulnerability disclosure program. First, researchers need clear guidance on what constitutes an in-scope AI finding, because "I got the chatbot to say something embarrassing" and "I got the chatbot to exfiltrate another customer's data" are very different severities that your triage process needs to distinguish quickly. Second, your engineering team needs a way to reproduce and verify model-behaviour reports, which is harder than reproducing a conventional exploit because LLM outputs are non-deterministic.
What is data exfiltration via LLM, and how does it differ from a traditional data leak?
Data exfiltration via LLM is the unauthorised extraction of sensitive information — training data, system prompts, retrieved documents, or other users' data — through conversational interaction with a model rather than through a conventional access-control bypass. Where a traditional breach exploits a misconfigured permission or an unpatched server, an LLM exfiltration exploit can occur even when every permission is correctly configured, because the model was tricked into retrieving and repeating information it had legitimate access to.
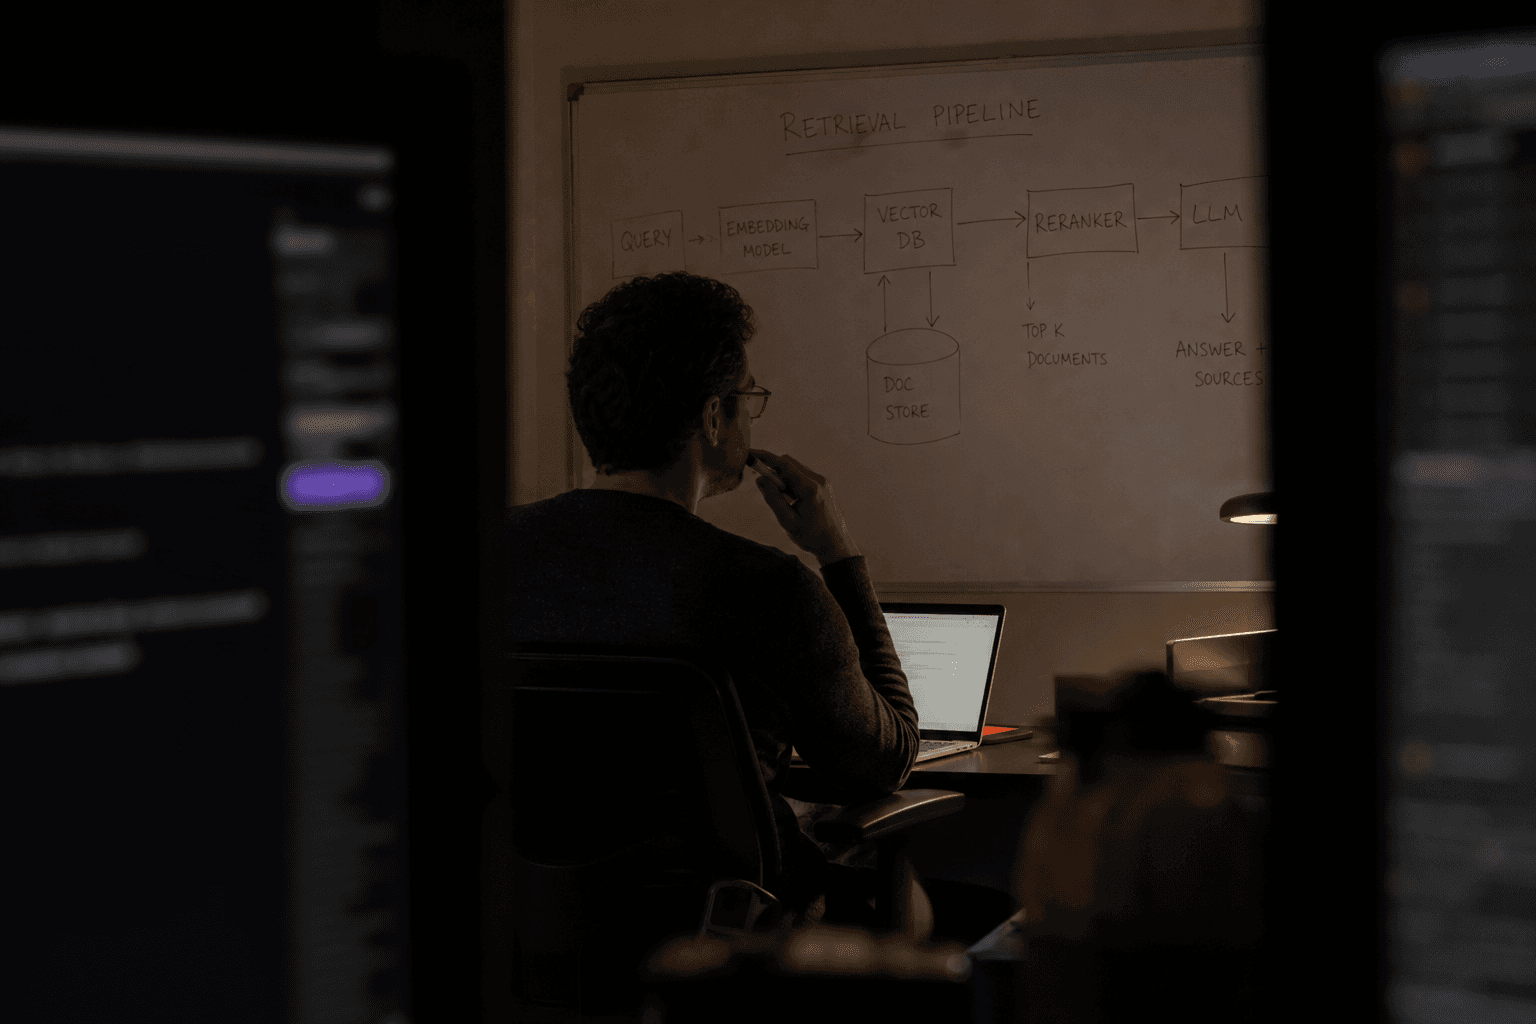
This is particularly relevant for products built on retrieval-augmented generation (RAG), where the model pulls from a knowledge base or customer data store at query time. A disclosure program that only asks researchers to test authentication and authorisation will miss this class of issue entirely, because the access control itself may be functioning as designed. Teams building or hardening these pipelines should treat the retrieval layer as part of the trust boundary — something we cover in more depth when working through data infrastructure design with clients.
How should you scope an AI-aware bug bounty program?
Scope should explicitly name the AI-specific behaviours you want tested, not just the infrastructure around them. That means listing prompt injection (direct and indirect), jailbreak attempts, training or fine-tuning data leakage, system prompt extraction, cross-tenant data exposure via retrieval, and model denial-of-service (e.g. resource-exhaustion prompts) as distinct, in-scope categories — alongside your standard web and API scope.
Severity grading also needs rework. A conventional CVSS-style score doesn't map cleanly onto "the model revealed part of its system prompt" versus "the model revealed another tenant's customer record." Many organisations running mature AI bug bounty programs now grade AI findings on business impact — what data or action was actually exposed — rather than on technical exploit mechanics alone, since a low-complexity prompt injection can still cause a high-impact leak.
| Area | Traditional SaaS scope | AI-enabled SaaS scope |
|---|---|---|
| Input handling | Form validation, injection (SQLi, XSS) | Prompt injection, jailbreak attempts |
| Data boundary | Auth/authorisation, IDOR | Cross-tenant leakage via retrieval, system prompt extraction |
| Availability | Rate limiting, DoS | Token/resource exhaustion via adversarial prompts |
| Output risk | N/A | Model generating harmful, biased, or policy-violating content |
| Severity basis | Technical exploit complexity | Business impact of exposed data or action |
What does Australian AI governance say about disclosure?
It's worth being precise about terminology here, because "responsible disclosure" means something different in Australian AI policy than it does in security research. Australia's AI Ethics Principles use "responsible disclosure" to describe transparency obligations — ensuring people understand when AI significantly impacts them — which is about disclosing AI use to affected individuals, not disclosing security vulnerabilities to researchers. These are related but distinct obligations, and conflating them in your policy documentation will confuse both your legal and security teams.
What Australian guidance does support is the broader principle that responsible AI requires robust testing, monitoring, and incident response, not just pre-deployment evaluation — a security posture that a well-scoped bug bounty program directly reinforces. The Department of Industry, Science and Resources (DISR) oversees Australia's AI Safety Institute, which focuses on AI safety research and evaluation, and previously published the Voluntary AI Safety Standard's ten guardrails for safe and responsible AI development and deployment (now superseded). Neither framework specifies bug bounty mechanics directly, but both reinforce that ongoing, adversarial testing of deployed AI systems — not just launch-day review — is expected practice.
How should growing SaaS and fintech teams get started?
Start by auditing where LLMs touch customer data in your product — chat interfaces, RAG pipelines, agentic workflows, embedded copilots — before writing a single line of policy. You can't scope a disclosure program for attack surface you haven't mapped. This is foundational work we typically do alongside AI product strategy engagements, because the security scoping and the product scoping are really the same exercise viewed from different angles.
From there, update your existing vulnerability disclosure policy to explicitly name AI-specific categories, set realistic response SLAs for AI findings (triage often takes longer because reproduction is non-deterministic), and decide whether AI findings sit in your existing bounty tiers or need their own. If you're still building the AI features themselves, it's far cheaper to design prompt isolation, output filtering, and tenant-boundary enforcement in from the start than to retrofit them after a researcher reports the gap — something our AI engineering team builds directly into delivery, alongside modernisation work for teams still running the underlying platform on legacy infrastructure. For more on building AI responsibly from the ground up, browse our insights.
If you're exploring how to structure a disclosure program or harden an AI feature before it ships, we can help.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.