Multi-Tenant Architecture for AI-Powered B2B SaaS
Adding AI to a multi-tenant SaaS platform is an architecture problem, not just a model problem. Here's how to isolate tenant data, design per-tenant model context, and choose between shared and dedicated inference infrastructure.
Adding AI features to an existing multi-tenant SaaS platform is rarely a pure model problem. It is an architecture problem. Many scale-ups get the model right and the isolation wrong — and discover the gap only after a customer asks, in writing, whether their data trained a model that another customer's users can query.
This article walks through the three decisions that matter most: how to isolate tenant data through the AI layer, how to design per-tenant model context, and when to run shared versus dedicated inference infrastructure.
What makes multi-tenancy harder once you add AI?
Multi-tenant architecture is a design pattern where a single application instance serves multiple customers (tenants) while keeping each tenant's data, configuration, and behaviour logically or physically separated. AI features complicate this because they introduce new artefacts — embeddings, retrieval corpora, conversation history, fine-tuned adapters, cached prompts — that did not exist in the pre-AI version of your product, and each one needs its own isolation decision.
A typical SaaS platform already isolates tenants at the database and application layer. Bolting on an LLM feature without extending that isolation model to prompts, retrieval indexes, and session state is the most common gap we see in scale-ups moving fast on AI. The result is usually invisible until a customer's support ticket, security questionnaire, or penetration test surfaces it. This is exactly the kind of gap that a structured ai product strategy engagement is designed to catch before it reaches a customer.
How should you isolate tenant data in an AI-powered SaaS platform?
Tenant data isolation for AI features means every retrieval corpus, embedding store, and conversation log is scoped so one tenant's content can never appear in another tenant's inference request — even under a shared model. This has to be enforced architecturally, not just through application-layer filtering, because a single missed filter in a retrieval query is a data breach.
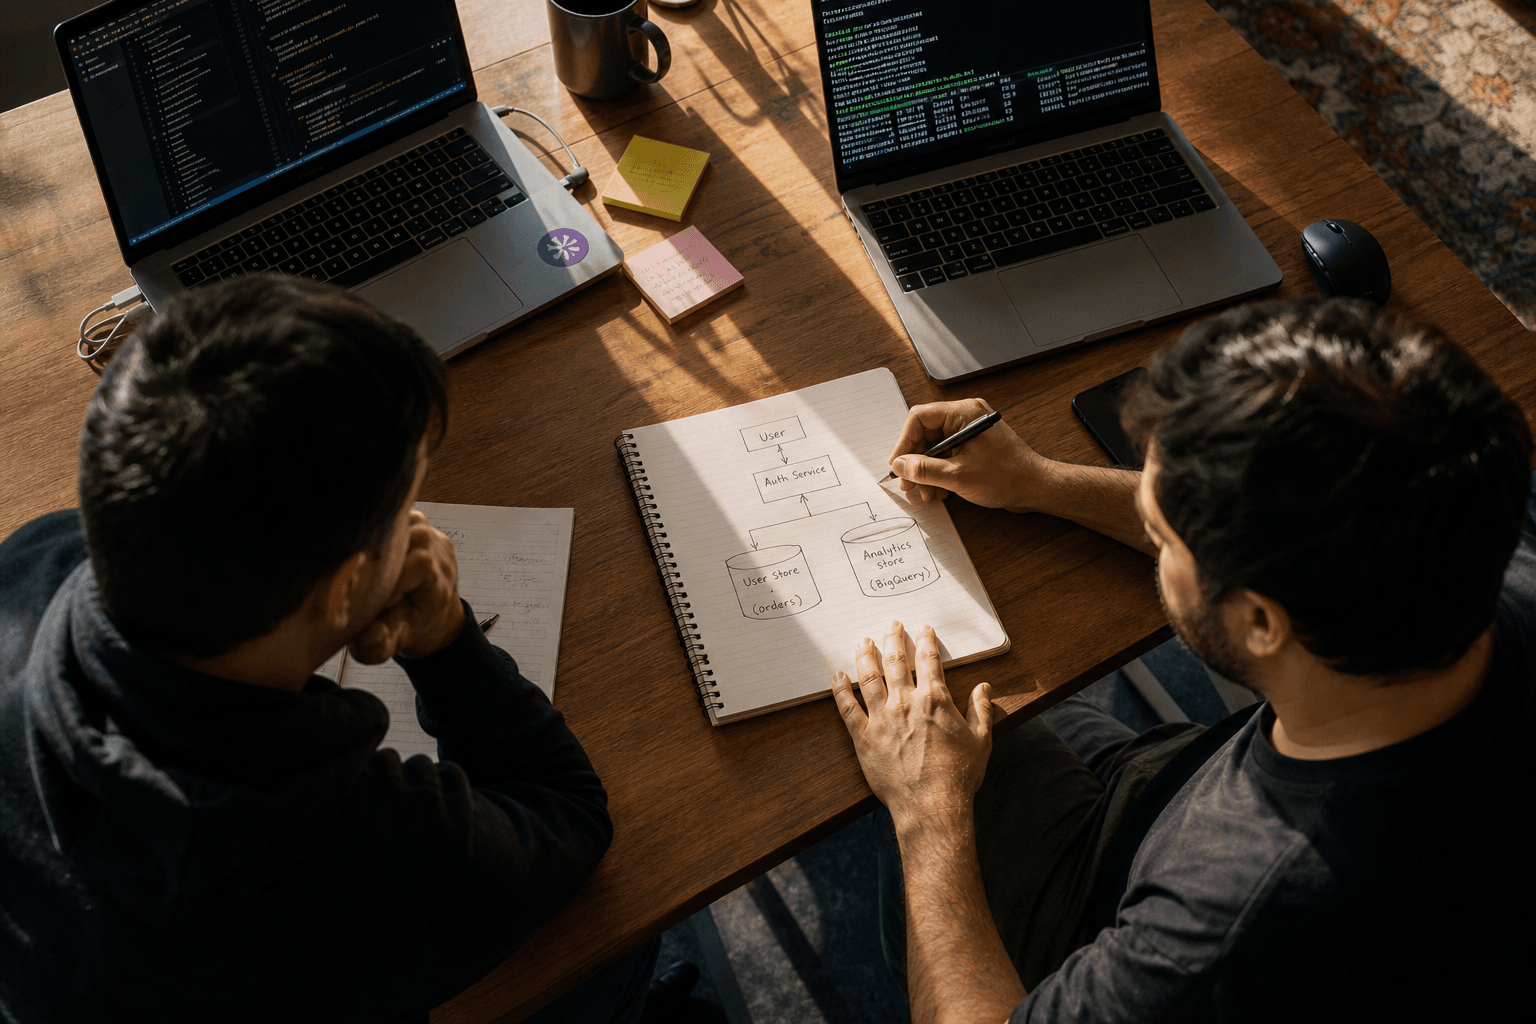
The cleanest pattern is to scope retrieval-augmented generation (RAG) resources per tenant rather than pooling them into one corpus with a tenant-ID filter bolted on afterward. Managed RAG infrastructure on platforms such as Google Vertex AI supports this directly, letting each customer's documents live in a distinct retrieval corpus rather than a shared index with row-level filtering as the only line of defence. The same logic applies to feature stores and vector search: segmenting these resources per tenant, or per tenant group for smaller customers, reduces the blast radius of any single misconfiguration to one customer rather than all of them.
Where a shared index is unavoidable for cost reasons, isolation must be enforced at the query layer with mandatory tenant-scoped filters, and that filter logic deserves the same code review rigour as your authentication layer — because functionally, that's what it is. This is one of the recurring findings from the application modernisation work we do with platforms that added AI features ahead of their underlying data architecture.
What is per-tenant model context, and how do you design it?
Per-tenant model context is the combination of retrieval scope, conversation history, configuration, and behavioural rules that determines how an AI feature responds for a specific customer. Getting this right is what makes an AI feature feel like it belongs to each tenant's instance of your product, rather than a generic layer sitting on top of it.
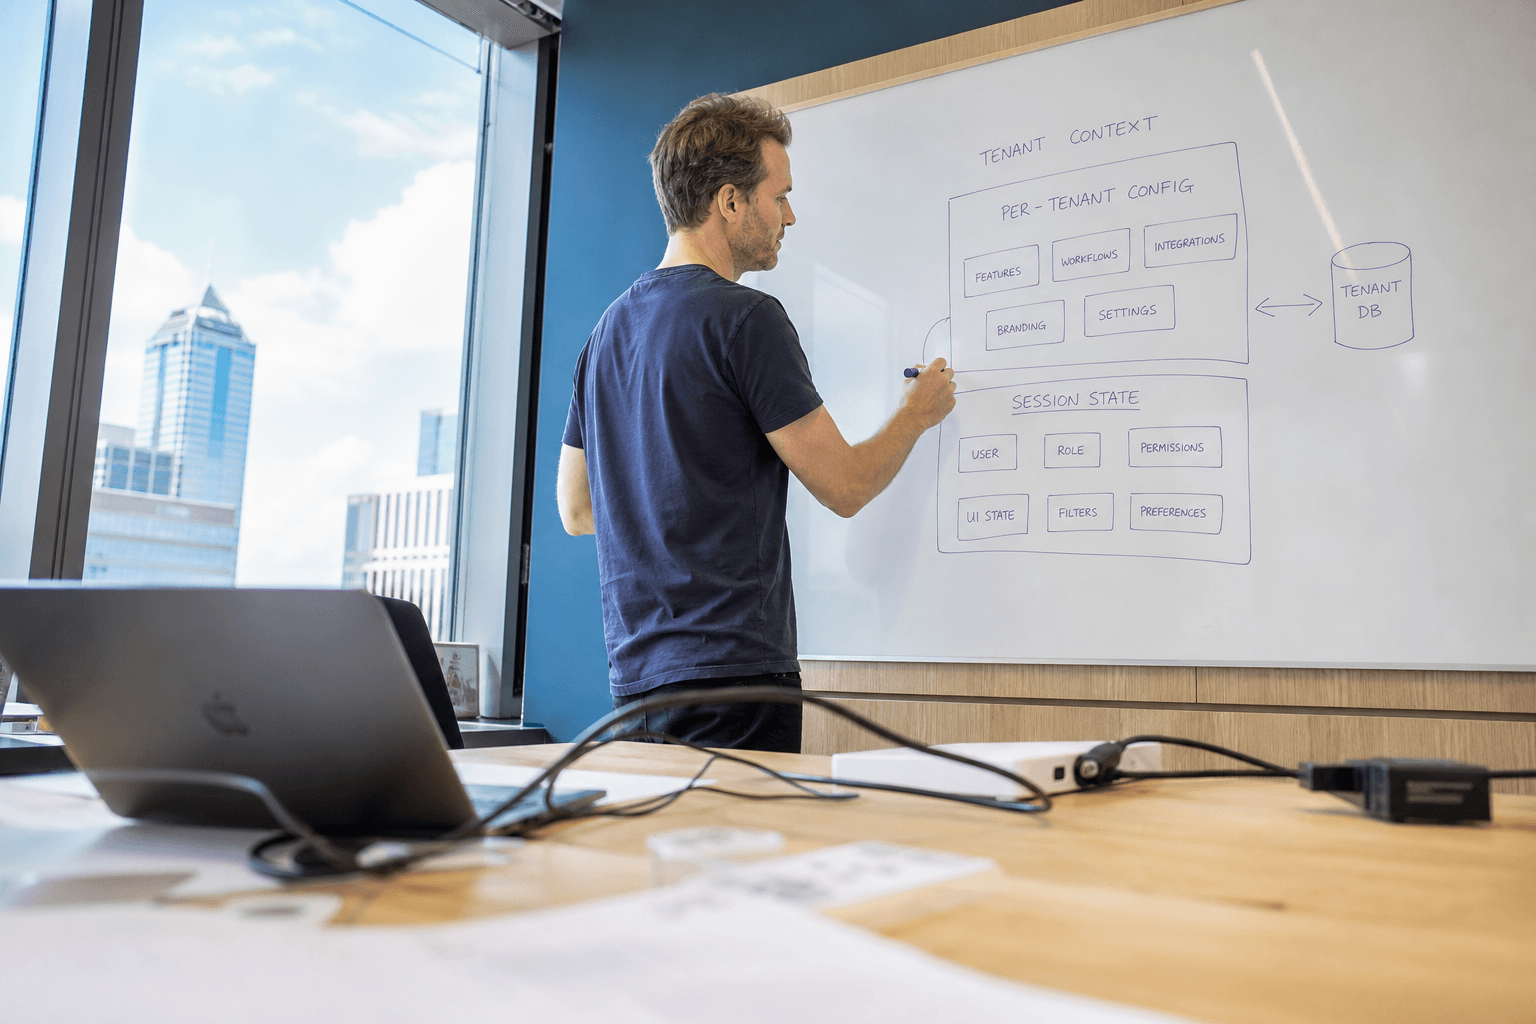
Three components typically need to be tenant-aware:
- Retrieval scope — which documents, records, or knowledge base entries a tenant's queries can draw on.
- Session and conversation state — a stateful agent runtime with per-session management, such as the reasoning and session-tracking layers available on platforms like Vertex AI, lets you isolate a customer's in-progress conversation without leaking context between tenants or between users within the same tenant.
- Behavioural and compliance rules — some tenants, particularly regulated ones, will need different guardrails on AI outputs than others. Governance policies applied at the platform level are one way to enforce per-tenant behavioural controls without maintaining separate application logic for each customer.
The architectural question to answer early is whether tenant configuration lives in the application layer, as a rules engine your team maintains, or is pushed down into the AI platform's native governance and session primitives. Pushing it down usually reduces long-term maintenance burden, provided your platform choice actually supports it — a decision worth validating during design rather than after launch. This is a common thread in our ai engineering engagements, where the platform choice made early on determines how much custom isolation logic a team has to carry indefinitely.
Shared vs dedicated inference infrastructure: which should you choose?
Shared inference infrastructure means multiple tenants' requests are served by a common pool of model endpoints, while dedicated infrastructure provisions separate compute, and sometimes separate model instances, per tenant or per tenant tier. The right choice is rarely all-or-nothing; most mature AI SaaS platforms end up with a hybrid.
| Approach | Isolation strength | Cost efficiency | Typical fit |
|---|---|---|---|
| Shared inference pool | Lower — relies on application-layer isolation | Higher — compute is pooled across tenants | Smaller customers, non-regulated use cases |
| Dedicated inference per tenant | Higher — physical separation of compute | Lower — idle capacity per tenant | Regulated industries, enterprise contracts, strict data residency requirements |
| Hybrid (shared by default, dedicated on request) | Configurable per tenant | Balanced | Growing SaaS platforms serving a mixed customer base |
The hybrid model is what we recommend to most SaaS teams building AI features today: default new tenants into the shared pool, and give sales or customer success the ability to move a specific tenant to dedicated infrastructure when a contract, a security review, or a data residency requirement demands it. Building that switch in from the start is considerably cheaper than retrofitting it once a large customer asks for it during procurement.
How do you avoid the most common isolation mistakes?
Most of the isolation failures we see in AI-powered SaaS platforms trace back to the same root cause: the AI feature was designed and shipped by a team optimising for a demo, not for the multi-tenant reality of the platform it was landing on. A few practical habits reduce that risk substantially.
Treat every new AI artefact — a retrieval index, a cached prompt, a session store, a fine-tuned adapter — as a first-class tenant-scoped resource from day one, not something to retrofit once a customer notices. Review isolation logic in retrieval and prompt-construction code with the same rigour as authentication code, because a leaked tenant filter has the same blast radius as a broken login check. Decide early whether tenant configuration lives in your application or in the AI platform's native governance layer, since retrofitting that decision later is expensive. And build the shared-to-dedicated infrastructure switch before a large customer's procurement team asks for it, not after.
None of this is exotic engineering. It is the same discipline SaaS teams already apply to database-level tenant isolation, extended to cover the new categories of data that AI features introduce. Teams that treat AI isolation as an extension of existing architecture discipline, rather than a bolt-on afterthought, consistently ship these features with fewer surprises during customer security reviews.
If you're adding AI features to a multi-tenant platform and want a second set of eyes on the isolation model before it ships, or you're seeing early signs that your current approach won't hold up under a security questionnaire, get in touch — we're happy to talk through where the risk actually sits in your architecture. You can also browse more insights on AI adoption and platform modernisation from our team.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.