From Spreadsheets to Data Infrastructure: A Migration Path
Many growing Australian companies still run finance and operations reporting on spreadsheets long after they've outgrown them. This guide covers the signs it's time to move, what a first data infrastructure build should include, and how to sequence the migration without disrupting month-end.

Why do finance and ops teams outgrow spreadsheets?
Spreadsheets work well when data volume is low, one person owns the file, and reporting happens monthly. They break down when multiple teams need the same numbers, when data has to be pulled from several systems, and when decisions depend on data being current rather than a week old. The signs are usually operational before they're strategic — a reconciliation that takes days instead of hours, a version-control mess across shared drives, or a report that three people produce three slightly different versions of.
Data infrastructure, in this context, is the set of systems and processes that automatically extract, store, transform, and serve data from source systems so that finance and ops teams can report and analyse without manual file handling. It's not a single tool — it's a pipeline: source systems, a central data store, transformation logic, and a reporting layer sitting on top.
What are the practical signs it's time to move?
The clearest signal is time spent on data assembly rather than data analysis. If your finance or ops team spends more hours each month collating, checking, and reconciling spreadsheets than they spend interpreting the numbers, the process itself has become the bottleneck.
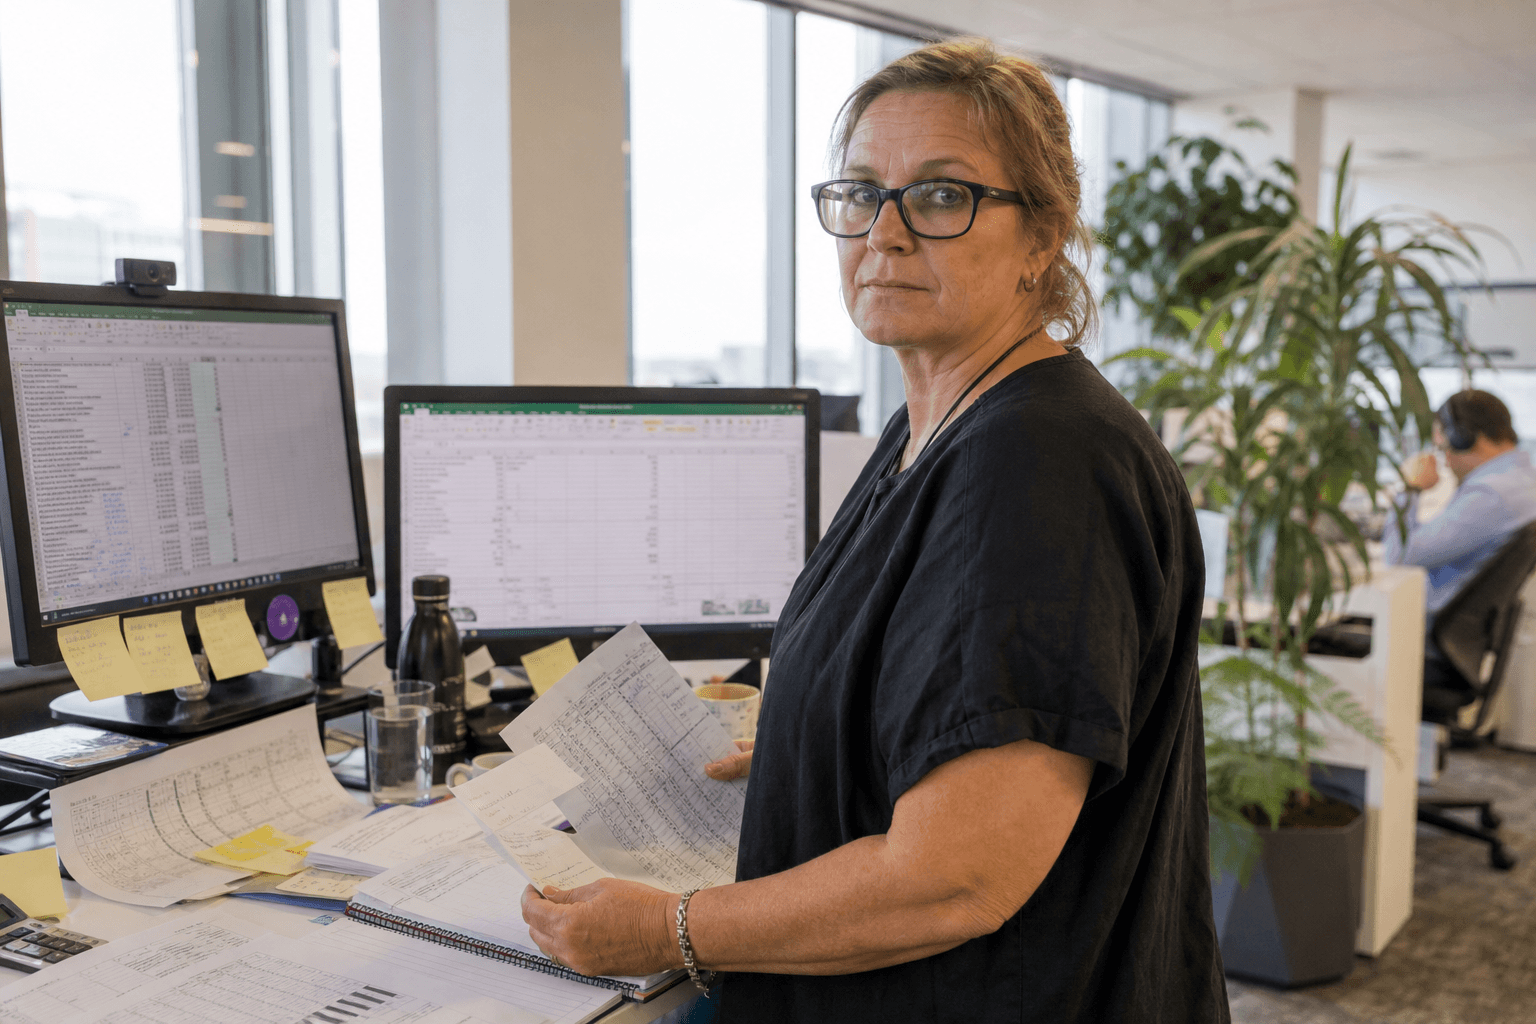
Other common triggers include: month-end close taking longer as the business grows rather than staying flat or shrinking; multiple "source of truth" spreadsheets that periodically disagree; manual copy-paste between systems (e.g. from an ERP or CRM into a workbook); reports that can't answer a new question without rebuilding the whole model; and a growing risk that one person's spreadsheet logic isn't understood by anyone else on the team. None of these are dramatic failures on their own — they're gradual friction that compounds as headcount, transaction volume, and reporting complexity grow.
What should a first data infrastructure build include?
A first build should cover four things: reliable extraction from your core systems, a central place to store and model that data, a transformation layer that encodes your business logic once, and a reporting layer your finance and ops teams already know how to use. The goal isn't a platform overhaul — it's replacing the fragile parts of your current process with something repeatable.
In practice, this usually means:
- Extraction: automated, scheduled pulls from source systems (accounting platform, CRM, inventory or ops system) instead of manual exports.
- Storage and modelling: a central data warehouse or database where data lands in a structured, queryable form, rather than living across disconnected files.
- Transformation: a documented, version-controlled set of rules for how raw data becomes the numbers finance and ops actually use — replacing formulas buried in spreadsheet cells.
- Reporting: a dashboard or BI layer connected directly to the transformed data, so reports update automatically rather than being rebuilt each cycle.
It's worth being honest about scope here: a first build does not need to ingest every system or answer every future question. It needs to reliably replace the highest-friction manual processes and give the team a foundation they can extend. Over-scoping a first data infrastructure project is one of the more common ways these initiatives stall before they deliver value.
How do you sequence the migration without disrupting month-end?
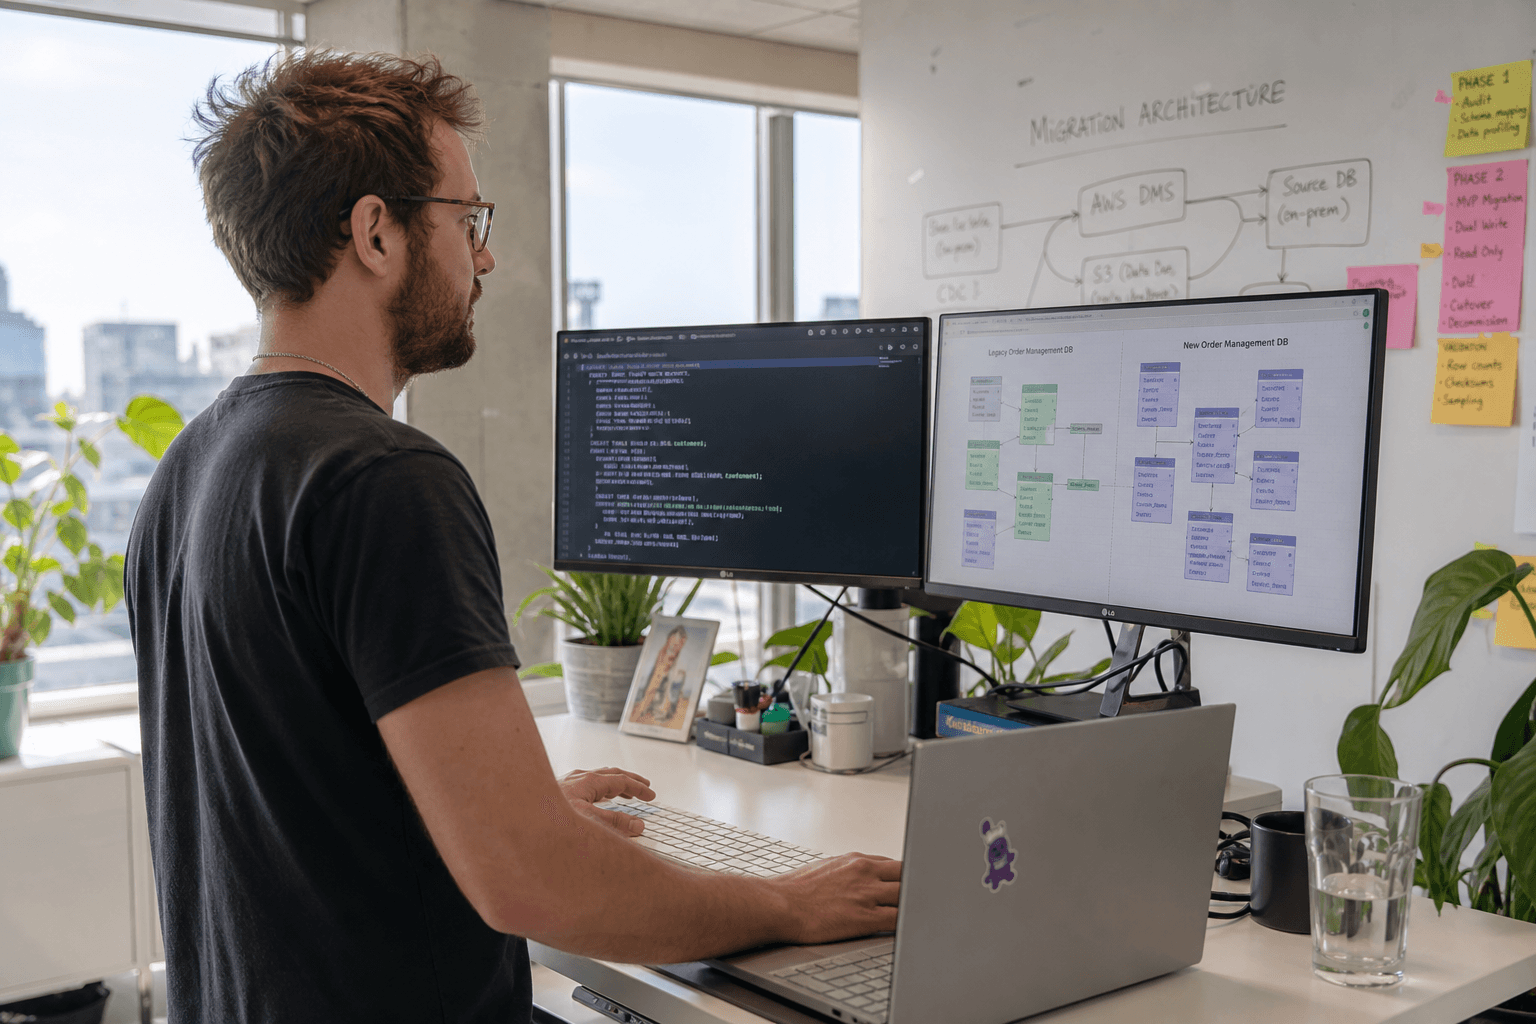
The safest sequencing runs the new pipeline in parallel with the existing spreadsheet process until outputs match, rather than cutting over in one step. This protects the business from a broken month-end while still making steady progress toward the new system.
A practical order looks like:
- Map the current process — document every spreadsheet, its inputs, its owner, and what decisions depend on it. This is often the step teams skip, and the one that surfaces the most risk.
- Pick the highest-friction workflow first — usually the report that takes longest to produce or has caused the most reconciliation errors, not the most technically interesting one.
- Build and validate in parallel — run the new pipeline alongside the existing spreadsheet for at least one full reporting cycle, comparing outputs line by line.
- Cut over one workflow at a time — retire the spreadsheet only once the parallel run has matched for a full cycle, and only for that one workflow.
- Extend incrementally — once the first workflow is stable, move to the next highest-friction process, reusing the same extraction and transformation foundations.
This staged approach takes longer than a full replacement in one go, but it means month-end close never depends on an unproven system, and it gives the finance or ops team confidence in the new numbers before they stop checking against the old ones.
Spreadsheets vs data infrastructure: a comparison
| Dimension | Spreadsheet-based process | Data infrastructure |
|---|---|---|
| Data freshness | Manual refresh, often lagging | Automated, near real-time possible |
| Single source of truth | Multiple versions common | Centralised, modelled once |
| Auditability | Difficult to trace formula logic | Version-controlled transformation logic |
| Scalability | Breaks down as volume grows | Designed to scale with data volume |
| Reporting speed | Manual rebuild each cycle | Automated dashboards |
| Effort to extend | Rebuilding models from scratch | Adding to existing pipeline |
Do you need a full data platform to get started?
No — most growing companies don't need an enterprise-scale data platform for their first move away from spreadsheets. What they need is a right-sized pipeline covering their core reporting workflows, built on infrastructure that can grow with them rather than a large, complex platform that requires a dedicated team to operate.
This is a genuine trade-off worth naming honestly: heavier platforms bring more capability but also more operational overhead, and for a first build that overhead often outweighs the benefit. The better starting point is usually a lean pipeline that solves the specific reporting and reconciliation problems causing the most pain today, built in a way that supports adding new data sources and use cases later — including AI and advanced analytics — without a rebuild.
Where does this fit with AI and broader modernisation plans?
Data infrastructure is usually the prerequisite, not a parallel project. Most AI initiatives that stall do so because the underlying data isn't structured, accessible, or trustworthy enough to build on. Getting finance and ops reporting onto solid infrastructure is often the first real step toward broader ai-product-strategy work, because it establishes the data foundation that AI and analytics initiatives depend on.
If your finance or ops data sits on top of a legacy core system that itself needs attention, it's worth considering the data migration alongside a broader look at application-modernisation, since the two often need to be sequenced together rather than treated as separate projects.
For more on building this kind of foundation, see our work on data-infrastructure, and for teams thinking about what comes after — production AI, agents, or automation — our ai-engineering capability covers what's needed once the data foundation is in place. You can also browse our insights for related thinking on modernisation and data strategy.
Getting started
Moving off spreadsheets doesn't have to mean a disruptive, all-at-once platform migration. The teams that do this well start by mapping their current process honestly, tackle the highest-friction workflow first, and validate every step in parallel before retiring anything. If you're exploring how to move your finance or ops reporting onto proper data infrastructure without risking month-end, we can help — start with a conversation about where the friction actually is before committing to a build.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.