Data Annotation Pipeline Strategy for Custom AI Models
A practical guide for Australian data leaders on building or outsourcing data annotation pipelines for custom AI models — covering workforce models, quality control, and the Privacy Act considerations that apply when labelling sensitive business data.
Custom AI models are only as good as the labelled data that trains them. For Australian data leaders, building a reliable annotation pipeline raises questions that generic AI advice rarely covers: who should label sensitive business data, how do you catch quality problems before they reach production, and what does the Privacy Act 1988 actually require when your training data includes customer or patient records? This guide works through the practical decisions.
What is a data annotation pipeline?
A data annotation pipeline is the end-to-end process of taking raw data — text, images, audio, transcripts, documents — and attaching the structured labels a machine learning model needs to learn from it, along with the tooling, workforce, and quality checks that keep those labels accurate and consistent over time. It is not a one-off task. For most custom model projects it is an ongoing operational process that runs alongside model development, retraining, and monitoring.

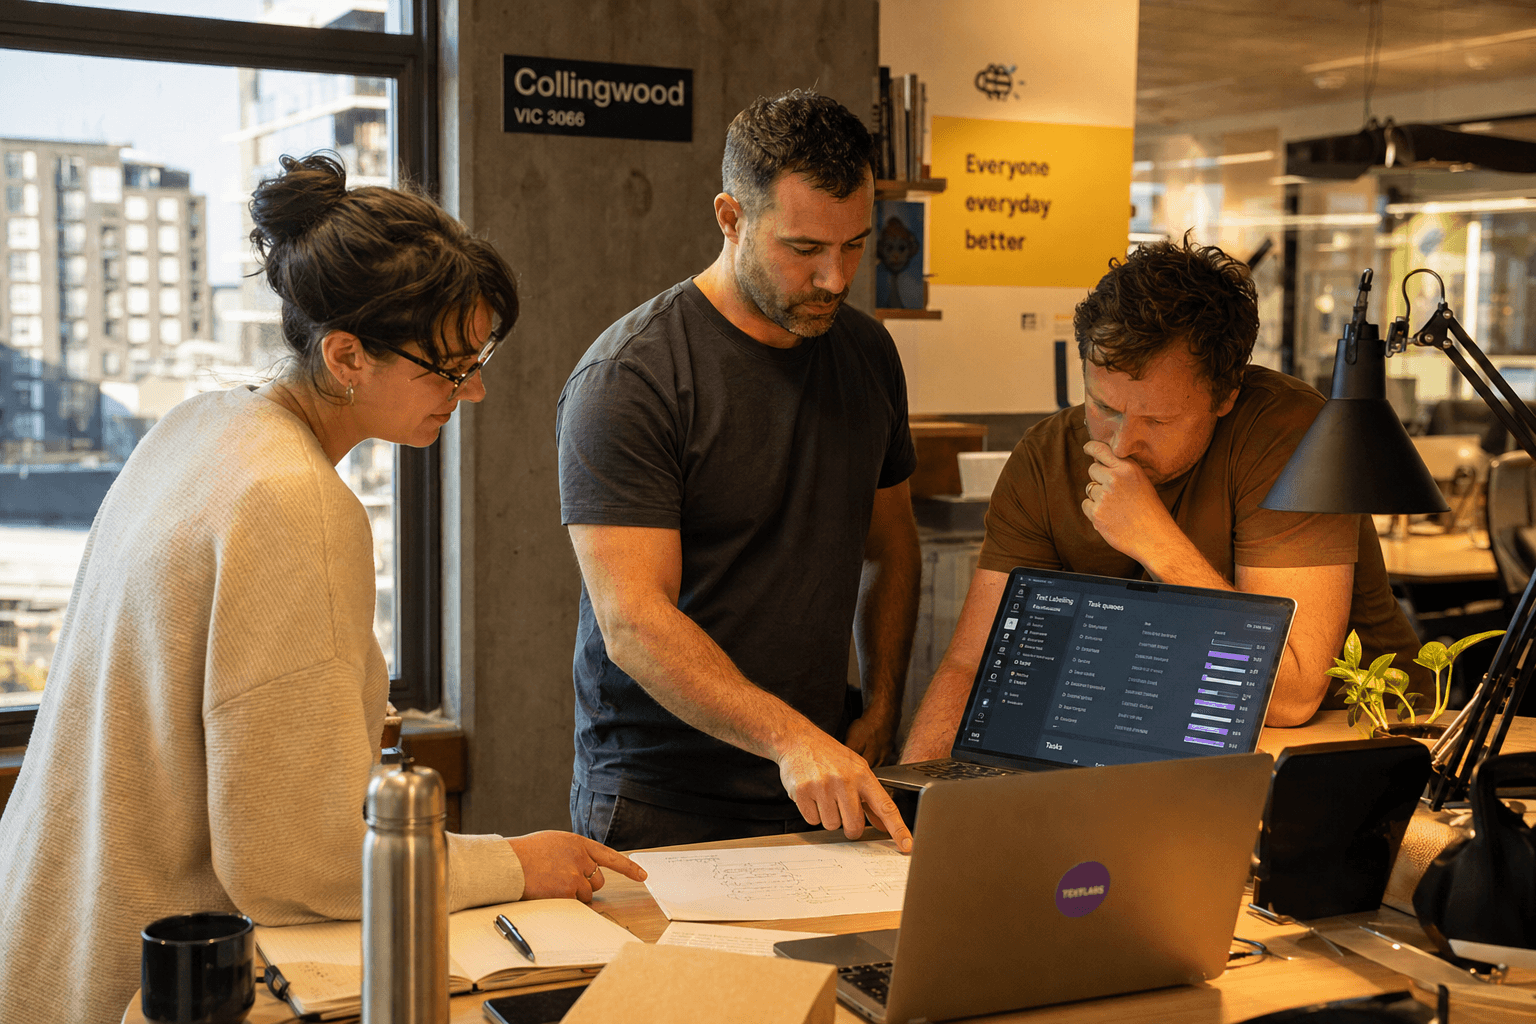
A well-designed pipeline has four moving parts: the annotation tooling (interfaces, task queues, label schemas), the workforce doing the labelling, the quality control layer that checks their work, and the governance layer that tracks who touched the data, when, and under what access controls. Weakness in any one of these undermines the model regardless of how good your architecture is.
Why does annotation strategy matter more for Australian businesses?
Annotation strategy matters more when the data being labelled is sensitive — financial transactions, health records, legal documents, or customer communications — because the labelling process itself becomes a point of privacy and security exposure, not just a data-quality exercise. In Australia, this is where the Privacy Act 1988 and the Australian Privacy Principles (APPs) come into play directly, because labelling often requires a human to view and interpret personal or sensitive information.
If your training data includes personal information as defined under the Privacy Act, APP 6 (use and disclosure) and APP 11 (security) apply to how that data is handled during annotation, not just during storage. That has direct implications for whether annotation work can be sent offshore, how access is logged, and whether de-identification needs to happen before data reaches an annotation workforce at all. The Office of the Australian Information Commissioner (oaic.gov.au) is the relevant regulator and a useful reference point when scoping these requirements with legal counsel.
Should you build an in-house annotation team, outsource, or use a hybrid model?
The right choice depends on data sensitivity, label complexity, and how often the model needs retraining — not on cost alone. Highly sensitive or domain-specific data (clinical notes, legal contracts, proprietary engineering data) generally favours smaller, trained in-house or specialist teams. High-volume, lower-sensitivity data (general image tagging, public text classification) is often well suited to outsourced or crowdsourced workforces with strong QA layers.

| Approach | Best suited to | Key consideration |
|---|---|---|
| In-house annotation team | Sensitive, domain-specific, or regulated data | Higher control, higher ongoing cost, requires management overhead |
| Specialist outsourced vendor | Domain expertise at scale (medical, legal, technical) | Vendor due diligence and contractual data handling terms are critical |
| Crowdsourced platforms | High-volume, low-sensitivity, general-purpose data | Lower cost per label, more variance in quality, not suited to sensitive data |
| Hybrid (in-house QA over outsourced labelling) | Most mid-to-large scale custom model projects | Balances cost and control; requires a defined review workflow |
Many growing Australian businesses land on a hybrid model: outsourcing high-volume first-pass labelling while keeping a small internal team responsible for quality review, edge cases, and anything touching genuinely sensitive data. This keeps cost manageable without losing control over the data that matters most.
How do you build quality control into an annotation pipeline?
Quality control works best as a layered process: inter-annotator agreement checks, a review/adjudication step for disagreements, periodic audits against a gold-standard dataset, and a feedback loop that routes model errors back to annotation guidelines. A pipeline without at least two of these layers tends to degrade quietly — labels drift as guidelines are interpreted differently over time, and nobody notices until model performance drops.
Human-in-the-loop review is particularly important in the early stages of a custom model, when label schemas are still being refined. Treat your labelling guidelines as a living document: when annotators disagree, that disagreement is signal, not noise, and it usually means the guideline itself needs clarifying. Active learning — where the model flags the examples it is least confident about for priority human review — can reduce the volume of data that needs full manual review, but it does not replace a baseline QA process; it sharpens where that QA effort gets spent.
Where should your labelling platform or workforce actually sit?
This is as much a data residency and access-control question as a tooling one. If the data being labelled must stay within Australian jurisdiction — common in health, financial services, and government-adjacent work — your annotation tooling, workforce location, and any vendor subcontracting arrangements all need to be checked against that requirement, not just your model hosting environment.
Platform tools can handle task management and interface workflows well, but they still require an internal team to operate them, define label schemas, manage workforce access, and interpret ambiguous edge cases — the platform doesn't remove that expertise gap on its own. This is one of the reasons some data teams choose to bring in embedded specialists for the setup phase: designing the schema, workforce model, and QA process, then handing over a pipeline the internal team can run day to day. Our data-infrastructure and ai-engineering work often starts exactly here — before a model is trained, making sure the data feeding it is labelled consistently, securely, and in a way the team can maintain.
What should data leaders do before starting a custom model project?
Before committing to an annotation workforce or platform, map out three things: what data you actually need labelled and at what volume, what sensitivity classification that data carries under Australian privacy law, and what level of ongoing labelling the model will need post-launch (most production models need continuous labelling as data drifts, not just a one-off batch). Skipping this mapping is the most common reason annotation costs blow out or quality problems surface late.
It's also worth deciding early whether annotation sits inside a broader ai-product-strategy conversation — because the labelling schema you choose shapes what the model can and can't do later, and changing it after training has started is expensive. If your underlying systems are still on legacy infrastructure, it's also worth reviewing that alongside your annotation plans; our application-modernisation work frequently surfaces data access and governance issues that affect how safely annotation can happen at all.
For more on the broader build-versus-buy decision for AI capability, see our insights on choosing between in-house AI capability and external support.
Get the foundations right before you label
Annotation pipeline strategy is a data governance decision as much as a machine learning one, and it deserves the same rigour you'd apply to any system handling sensitive Australian business data. If you're exploring how to structure an annotation pipeline for a custom model — whether that means scoping a workforce model, setting up QA processes, or working through data residency requirements — we can help. Start a conversation and we'll work through what fits your data, your sensitivity constraints, and your team's capacity to maintain it.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.