AI Compute Capacity Planning for Australian Tech Leaders
GPU supply constraints hit Australian organisations earlier and harder than larger markets. Here's how to plan compute capacity as a standing input to your technology roadmap, not a reactive scramble.
AI compute capacity planning is the process of forecasting, securing, and architecting around the processing power — primarily GPUs and other accelerators — needed to train and run AI models reliably. It covers decisions about where that compute lives (local cloud regions versus offshore), how much of it to commit to in advance, and how to design systems so a shortage in one location doesn't stall the whole roadmap. For Australian technology leaders, this matters more than it might elsewhere: GPU supply is tight globally, and Australia's smaller cloud market means local capacity constraints can show up earlier and last longer than in the US or Europe.
Done well, capacity planning sits alongside budget and headcount planning as a standing input to the technology roadmap, not a one-off exercise triggered by a shortage. The organisations that handle this smoothly tend to treat compute availability as a design constraint from the start, rather than a surprise they architect around after the fact.
Why is GPU and cloud capacity constrained in Australia?
Australia draws on the same global GPU supply chain as every other market, but with a smaller local data centre footprint and fewer hyperscaler regions offering the latest accelerator generations. When global demand spikes — as it has with the growth in generative AI workloads — Australian customers are often further down the allocation queue than customers in larger markets, and newer GPU hardware can take longer to land in local availability zones.
This isn't unique to any one provider. AWS, Microsoft Azure, and Google Cloud all operate Australian regions (primarily Sydney, with growing Melbourne presence), but not every region carries the same accelerator types, and capacity for the newest GPU families is frequently rationed through quotas, waitlists, or reserved-instance programs before it's available on-demand.
Should you run AI workloads on local or offshore compute?
The honest answer is: it depends on your workload, your data obligations, and your tolerance for latency. There's no universally correct choice — only trade-offs that need to be weighed against your specific constraints.
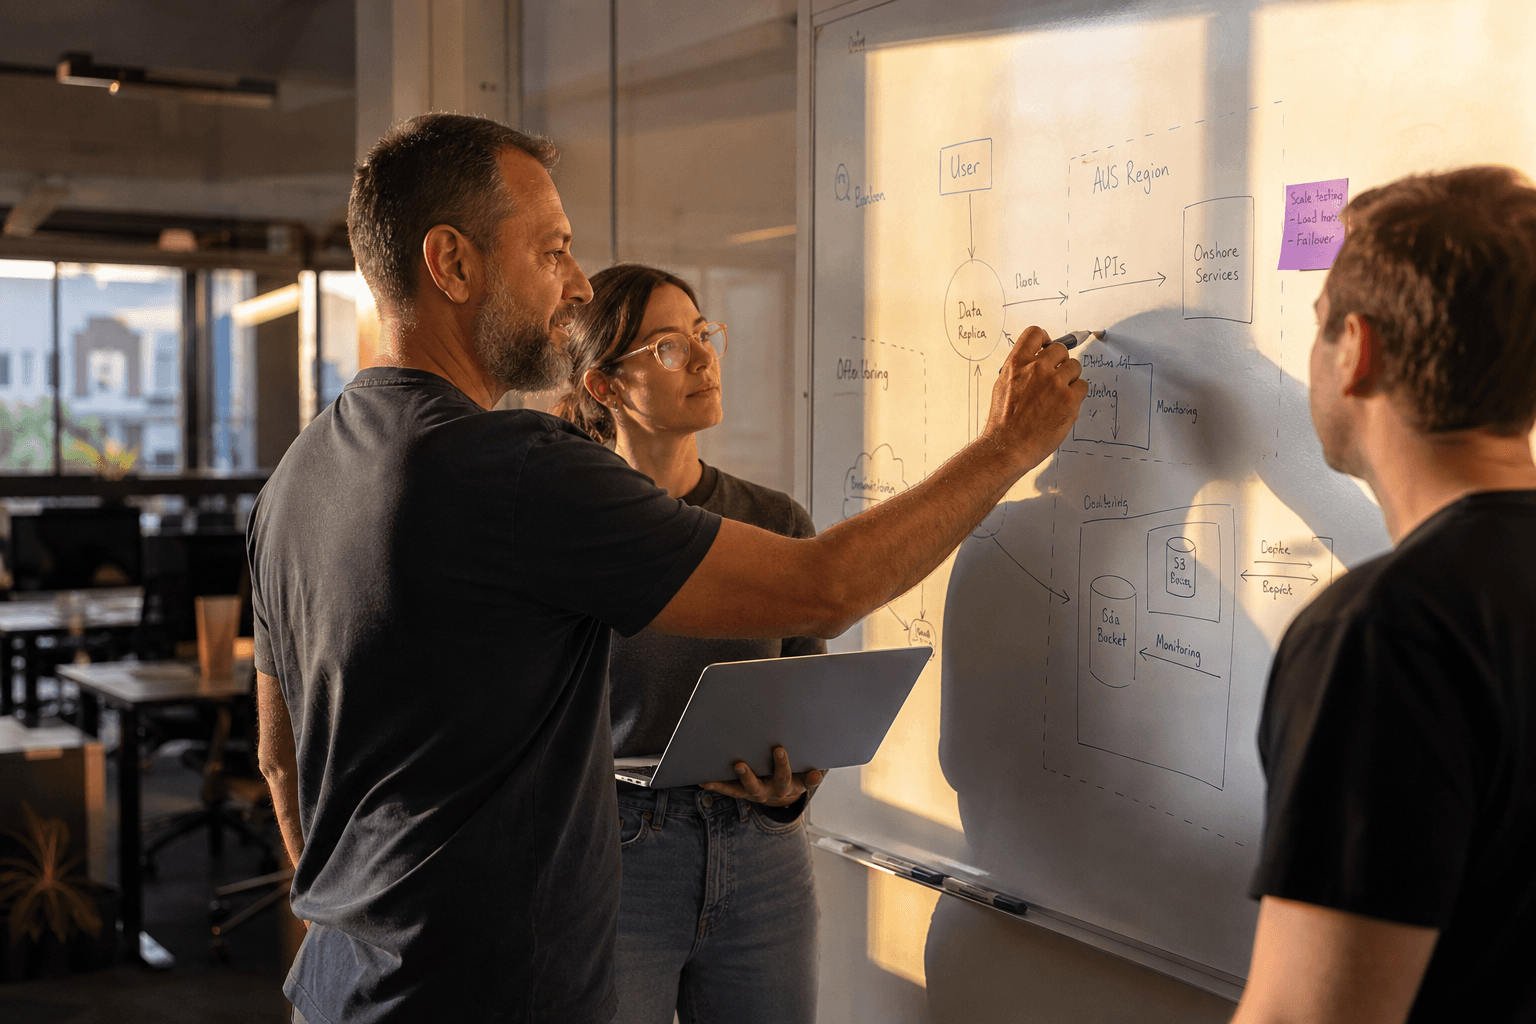
| Consideration | Local (Australian region) | Offshore (US/Asia region) |
|---|---|---|
| GPU availability for latest hardware generations | Often more constrained, longer waitlists | Typically wider availability |
| Data residency and sovereignty | Easier to meet Australian Privacy Principles and sector rules (e.g. APRA requirements for regulated financial services) | Requires careful contractual and technical controls |
| Network latency to Australian users | Lower | Higher, though often acceptable for batch/training workloads |
| Pricing and discount programs | Can be less competitive due to lower regional capacity | Often more options for committed-use discounts |
| Suitability for training vs inference | Good for latency-sensitive inference | Often better fit for large-scale training runs |
Many organisations land on a hybrid pattern: inference and any workload touching regulated or sensitive data stays local, while large training runs or less time-critical batch jobs use offshore capacity where it's more readily available. This isn't a compromise so much as matching the workload to the region that actually fits it. Getting this balance right is often part of a broader ai product strategy conversation — where you run compute is a downstream decision from what you're actually trying to build and who it serves.
Do reserved capacity commitments make sense for your organisation?
Reserved capacity — committing to a baseline level of GPU usage over a fixed term in exchange for pricing and availability guarantees — makes sense once your AI workloads have moved from experimentation to steady production usage. Committing too early, before usage patterns are established, risks locking in capacity you don't end up needing.
The calculus is different for training and inference. Inference workloads tend to have more predictable, recurring demand, which makes them a reasonable candidate for reservations once a product feature is live. Training workloads are spikier and often better served by on-demand or spot capacity, reserved only when you have a recurring retraining cadence that justifies it.
Before committing, it's worth modelling realistic utilisation under different adoption scenarios — commitments that look efficient at projected usage can become expensive if adoption is slower than planned, or insufficient if it's faster. This kind of forecasting is one of the practical outputs of good ai engineering work: translating a product roadmap into a defensible compute and cost plan, rather than guessing.
Which architectural choices reduce dependence on scarce compute?
The most resilient AI systems are designed to need less compute, not just to access more of it. A handful of architectural choices consistently reduce exposure to GPU scarcity: using the smallest model that meets the accuracy bar for a given task rather than defaulting to the largest available model, caching and reusing inference results for repeated queries, batching workloads to improve GPU utilisation, and choosing retrieval-augmented approaches over full fine-tuning where they achieve comparable results with far less training compute. Our breakdown of RAG vs fine-tuning goes into this trade-off in more detail.
Multi-cloud and multi-region design is another lever. Architecting workloads so they can shift between providers or regions — rather than being hard-wired to a single GPU pool — gives you optionality when one region is capacity-constrained. For organisations still running on legacy or monolithic infrastructure, this kind of flexibility often depends on groundwork done earlier — see our thinking on application modernisation for how that foundation gets built. For more on related topics, browse more insights from our team.
Compute capacity planning isn't a problem you solve once — it's an ongoing input to how you design, deploy, and scale AI systems in a market with real supply constraints. If you're working through how this applies to your own roadmap, get in touch and we can talk through where you sit today.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.