Usage-Based Billing for AI SaaS Features: A Metering Guide
AI features have volatile unit economics, and billing is often built last. This guide leads with what usage-based billing actually is, then covers metering architecture, pricing model trade-offs, and margin protection for AI SaaS features.
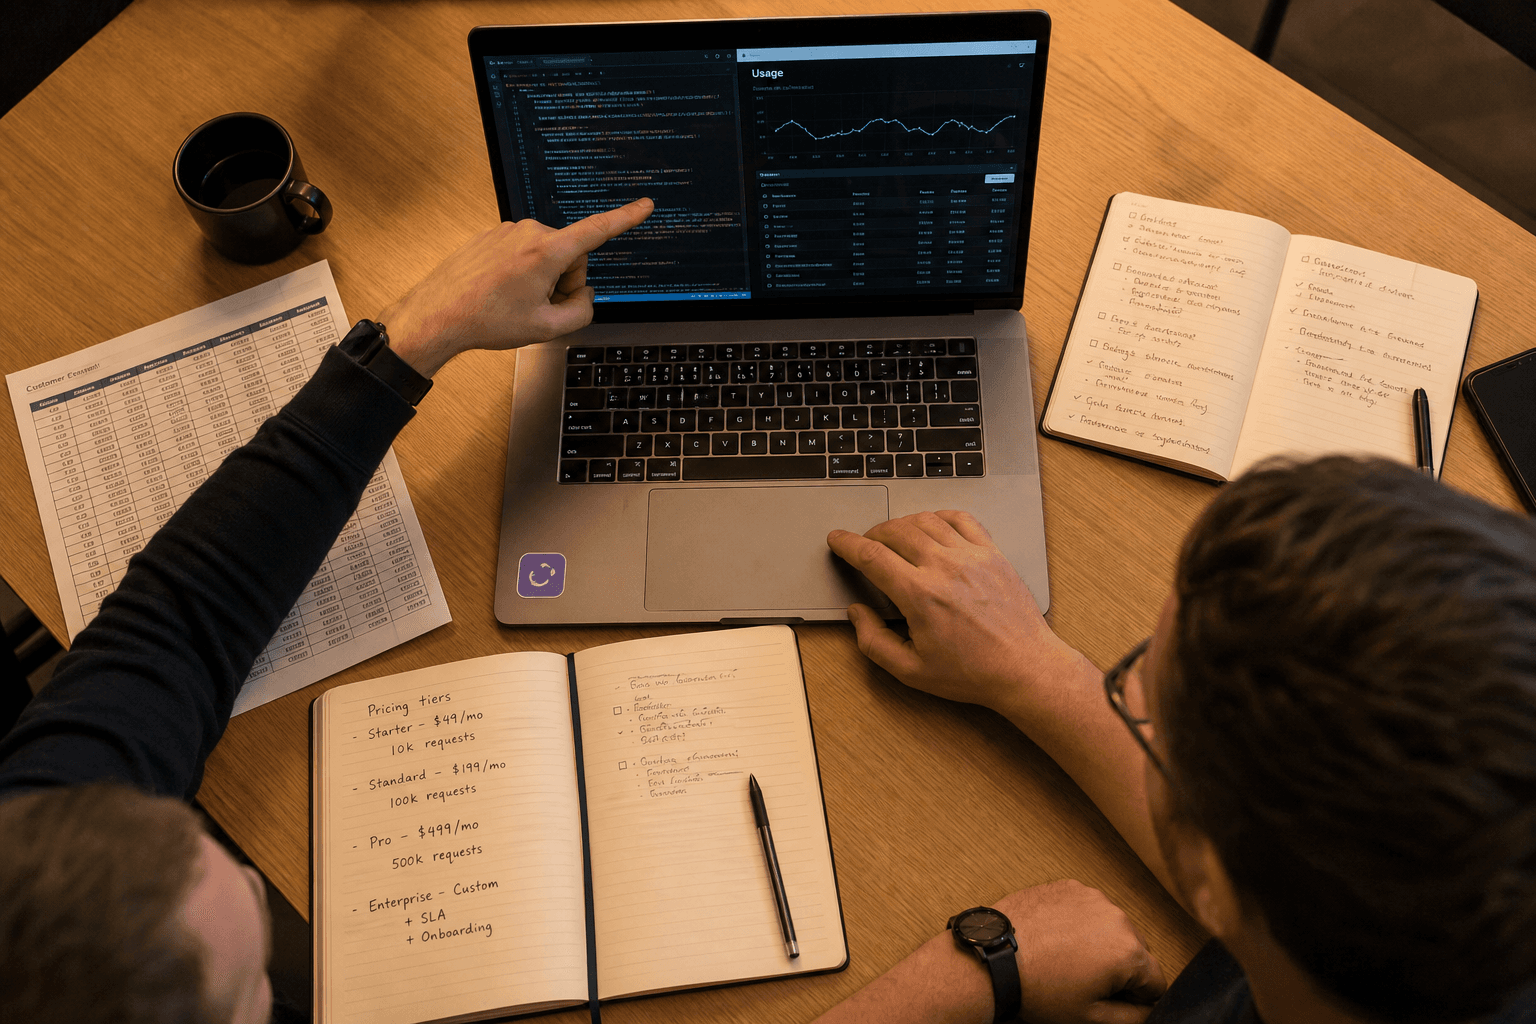
Usage-based billing charges customers for what they actually consume — tokens processed, API calls made, documents analysed, or agent actions completed — rather than a flat, seat-based fee. For AI features specifically, this means metering the underlying compute or inference events that drive cost, then translating them into a customer-facing unit that's simple to understand, such as "credits" or "AI actions."
Getting this right matters more for AI features than for traditional SaaS functionality, because AI unit economics are volatile in a way most engineering teams haven't had to price for before. A single user query might cost a fraction of a cent or several dollars, depending on model choice, context length, and retrieval overhead. For SaaS engineering leaders bolting AI into an existing product, the billing and metering layer often gets built last — and it shows up as margin erosion within months of shipping.
What is usage-based billing for AI features?
The core challenge is translating a highly variable, backend cost driver — LLM inference, vector search, embedding generation — into a pricing unit that customers can predict and trust. Get this translation wrong and you either under-charge power users into a loss-making cohort, or over-charge casual users and suppress adoption of the feature you built to differentiate the product.
This is a pricing decision as much as an engineering one. It sits close to ai product strategy: the metering unit you choose shapes how customers perceive value, and how willing they are to experiment with a new AI feature rather than treat it cautiously because the cost is opaque.
Why does metering AI features differ from traditional SaaS metering?
Traditional SaaS metering tracks relatively stable, predictable events — API calls, storage gigabytes, active seats. AI feature metering has to account for cost variance within a single feature: the same "one question" from a user can trigger wildly different compute depending on prompt length, model selection, retrieval depth, and retries. This makes the relationship between customer-visible usage and underlying cost far less linear than legacy metering assumed.
Three factors compound the difficulty. First, model provider pricing changes — sometimes with limited notice — meaning cost-per-unit assumptions baked into your pricing model can shift underneath you. Second, agentic and multi-step AI workflows consume compute across several internal calls (tool use, retries, retrieval, verification passes) that a single customer-facing action doesn't reveal. Third, latency-driven retries and error handling can silently inflate cost without producing any customer value at all — a failed generation still burns tokens.
What does a reliable metering architecture look like?
A reliable AI metering pipeline separates three concerns: usage capture, rating, and billing. Usage capture instruments every cost-generating event as close to the source as possible (inference call, embedding call, vector query). Rating applies business logic to convert raw events into billable units. Billing aggregates rated usage into invoices and enforces plan limits. Treating these as separate, testable layers — rather than one tangled billing script — is what keeps the system maintainable as pricing evolves.
In practice, this means:
- Event-level instrumentation: capture token counts, model used, latency, and success or failure status for every AI call, not just the ones you currently bill for. You will want this data later even if you don't monetise it yet.
- An idempotent event pipeline: usage events must be deduplicated and replay-safe. Double-counted usage during a service retry is one of the most common causes of billing disputes.
- A rating engine decoupled from the LLM call path: pricing logic changes far more often than your inference code. Keeping rating as a separate service means a pricing change doesn't require a redeploy of your AI feature.
- Reconciliation against provider invoices: your internal usage records and your model provider's bill should be reconciled on a schedule, not just trusted to match.
This is fundamentally a data infrastructure problem before it's a billing problem — you need trustworthy, complete, well-modelled event data before any rating logic can be correct. Teams that treat metering as an afterthought to their ai engineering work tend to discover the gaps only when finance asks why gross margin dropped.
For teams still running billing logic inside an ageing monolith, this is often the moment the case for application modernisation becomes concrete — a decoupled billing service is much easier to evolve than pricing logic buried in a legacy codebase that nobody wants to touch.
Flat-rate, usage-based, or hybrid: which pricing model fits?
There is no universally correct answer — the right model depends on cost variance, customer usage patterns, and how predictable you need revenue to be for forecasting and investor reporting.
| Model | Predictability for customer | Margin protection for vendor | Best fit |
|---|---|---|---|
| Flat-rate / seat-based | High | Low — heavy users subsidised by light users | Low variance features, mature stable cost base |
| Pure usage-based (pay-per-unit) | Low | High — cost passed through directly | High variance features, cost-sensitive early rollout |
| Hybrid (base fee + usage overage) | Medium | Medium-high | Most AI features — combines predictable revenue with margin protection at the tail |
| Credits / prepaid pools | Medium | High | Products wanting simplified customer-facing units while still capping exposure |
Many SaaS companies land on a hybrid model: a base subscription tier that includes a usage allowance, with overage billed at a marked-up per-unit rate. This gives customers predictability for typical usage while protecting margin against the smaller cohort of heavy users who drive disproportionate compute cost. Which model fits depends heavily on your specific cost structure and customer base — there's no substitute for modelling your own usage distribution before committing to a pricing approach.
How do you protect margin when LLM costs are unpredictable?
Margin protection starts with visibility, not pricing changes. You cannot price a feature sustainably if you don't know its true cost-to-serve at the customer or cohort level, updated continuously rather than reconstructed at quarter-end.
Practically, this means building cost-to-serve dashboards that break down inference spend by customer, feature, and model — not just an aggregate provider bill at the end of the month. It means setting internal alerting on cost anomalies (a spike in retries, an unexpectedly long context window, a customer running a workflow no one anticipated) before they show up as a bad month in the finance report. And it means revisiting your pricing model on a cadence, because model provider pricing and your own feature usage patterns will both keep shifting — a metering system is not a one-off build, it's an operating discipline.
If you're earlier in the process, it's worth reading more broadly on AI readiness before locking in a metering architecture, since pricing decisions are easier to get right when they follow a clear view of where AI actually creates value in your product, rather than being retrofitted after a feature has already shipped.
Usage-based billing for AI features is solvable with the right architecture, but it rewards teams that treat metering as infrastructure from day one rather than a billing afterthought. If you're weighing up pricing models for an AI feature you're building, or trying to work out why margin on an existing feature doesn't match what you expected, get in touch — we're happy to talk through what we've seen work.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.