Time-Series Demand Forecasting: A Guide for Supply Chain Leaders
A practical decision guide for logistics and manufacturing leaders on building time-series demand forecasting for inventory, production, and fleet planning — covering model selection, data requirements, and ERP/WMS integration.
Demand forecasting sits at the centre of nearly every planning decision in logistics and manufacturing — how much stock to hold, how many trucks to roster, how much raw material to order. Get it wrong and you carry excess inventory or stock out; get it right and working capital, fleet utilisation, and service levels all improve. This guide is for technical and operations leaders deciding whether, and how, to build a forecasting capability in-house.
What is time-series demand forecasting in logistics and manufacturing?
Time-series demand forecasting is the practice of using historical order, shipment, or production data — indexed by time — to predict future demand at a given location, SKU, or route. It differs from general business forecasting because it must account for seasonality, trend, promotional spikes, and external drivers such as weather or macroeconomic conditions. In logistics and manufacturing, the output typically feeds three downstream decisions: inventory replenishment, production scheduling, and fleet or warehouse capacity planning.
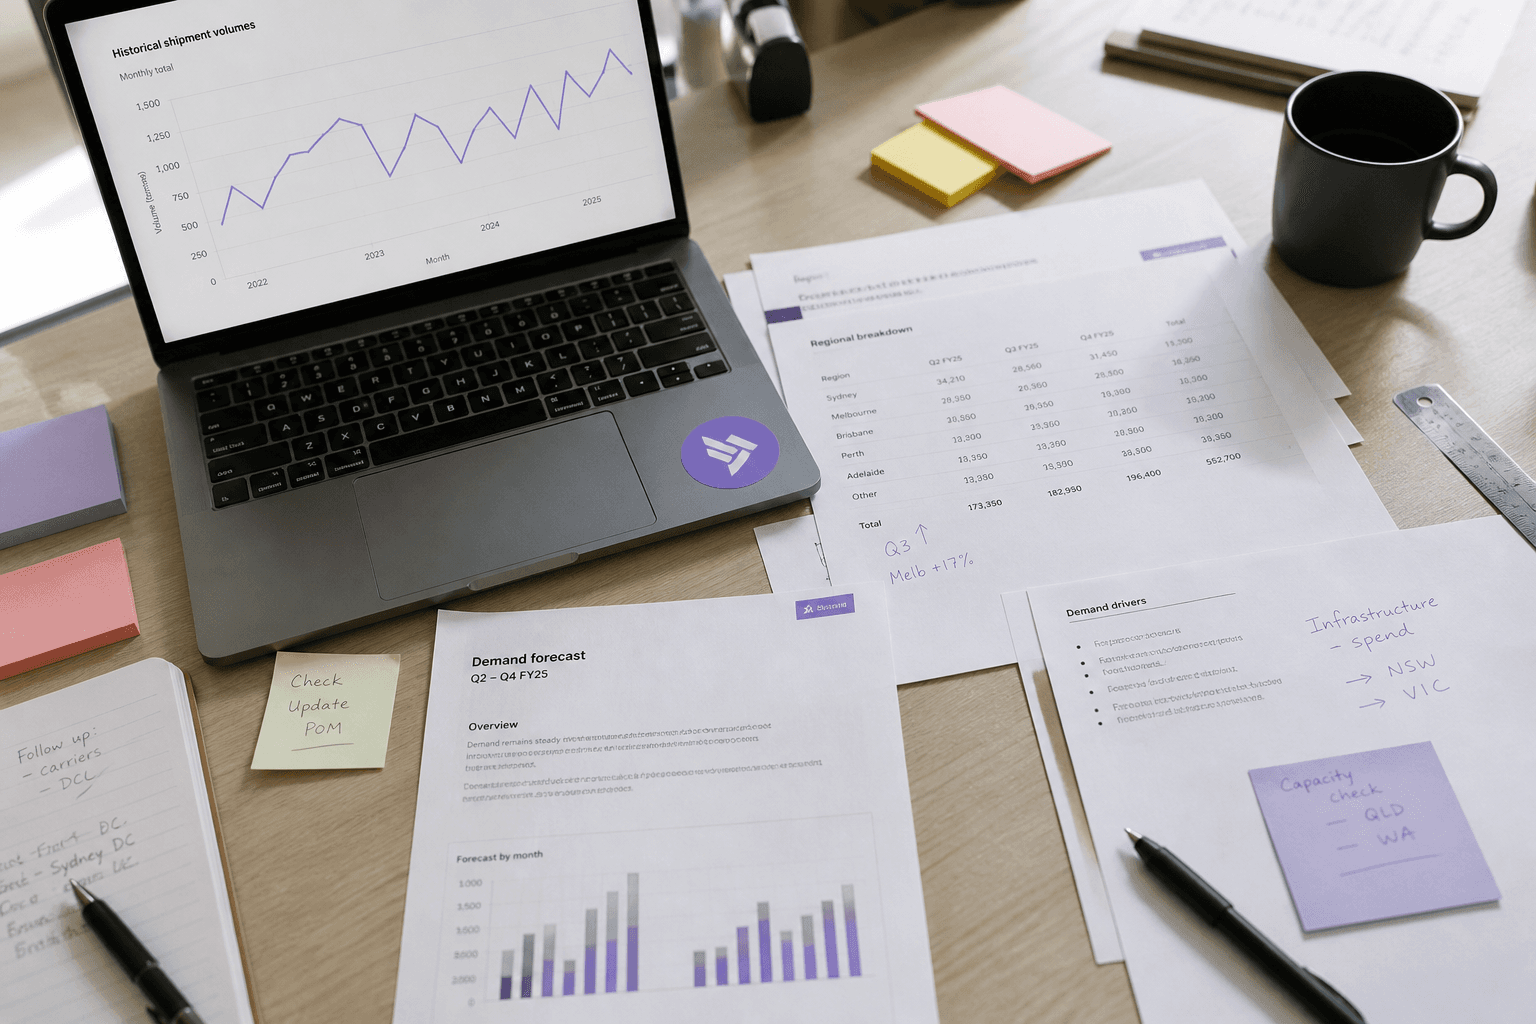
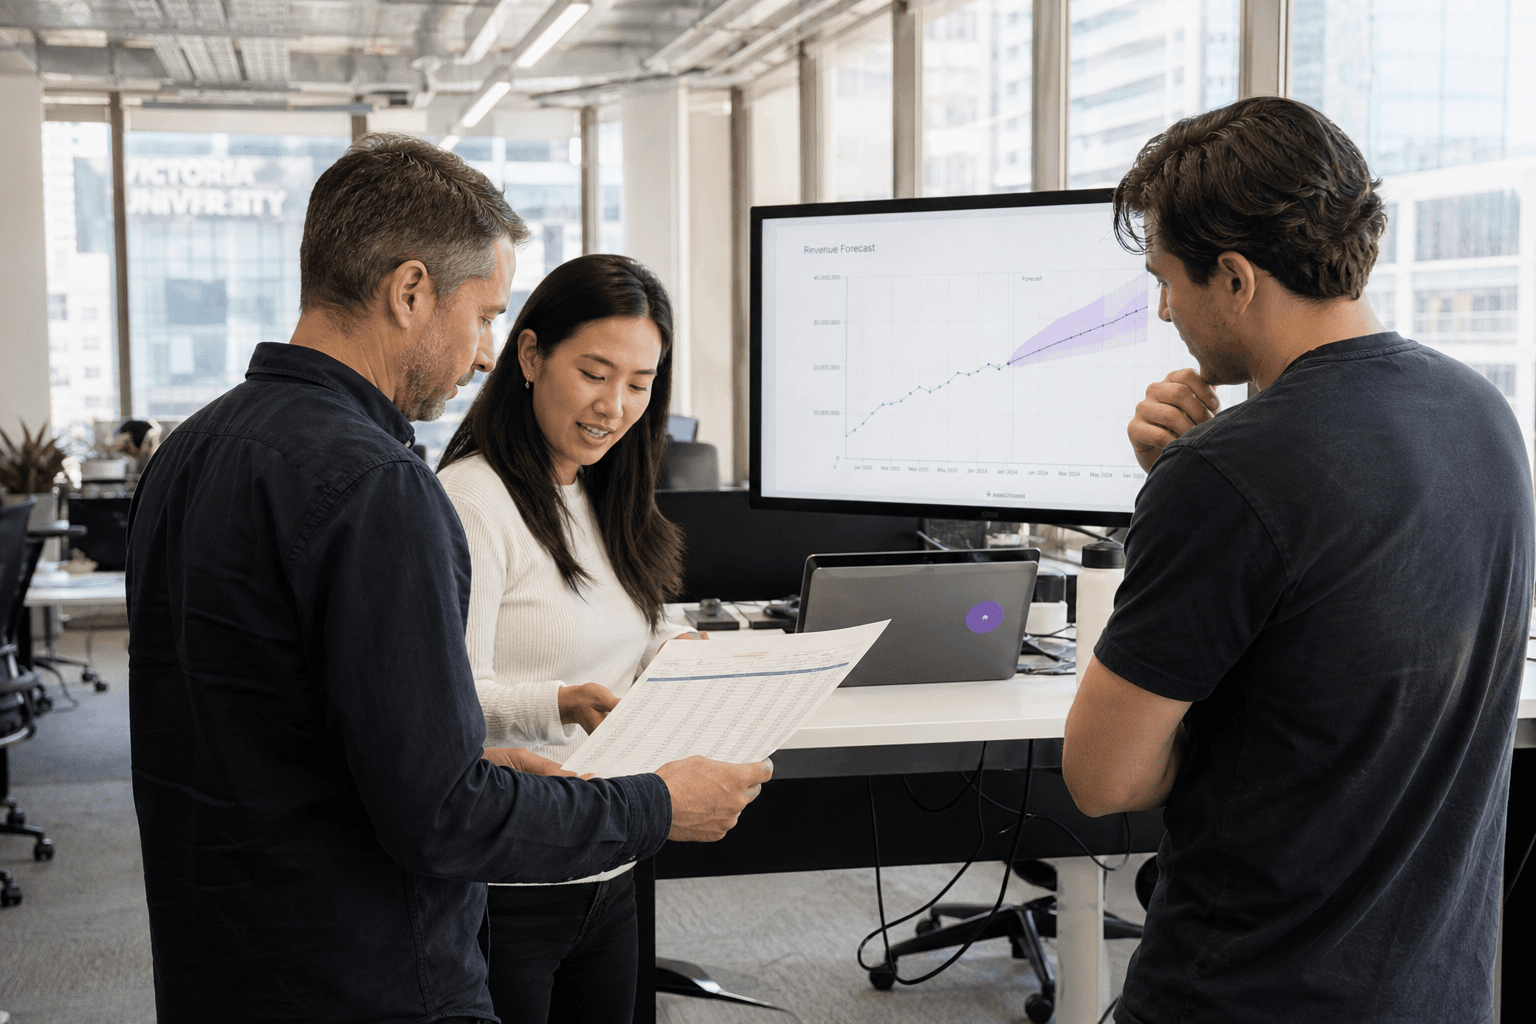
Good forecasts are not single numbers. They are distributions — a central estimate plus a confidence range — because the cost of under-forecasting (stockouts, missed deliveries) and over-forecasting (excess inventory, idle capacity) are rarely symmetric. Any forecasting program that reports only a point forecast is giving planners less information than they need.
How is demand forecasting different from predictive maintenance?
Demand forecasting predicts future order volumes or shipment counts; predictive maintenance predicts equipment failure or degradation. Both are time-series problems and both can live on the same MLOps infrastructure, but they use different data, different feature engineering, and different stakeholders — planning and commercial teams for forecasting, maintenance and operations teams for predictive maintenance.
It's worth separating the two explicitly early in any program. Organisations sometimes bundle them into a single "industrial AI" initiative, which dilutes focus and makes it harder to agree on success criteria for either. We'd generally recommend scoping demand forecasting as its own initiative with its own data pipeline, even if both eventually sit on shared platform infrastructure.
Which forecasting model should you choose?
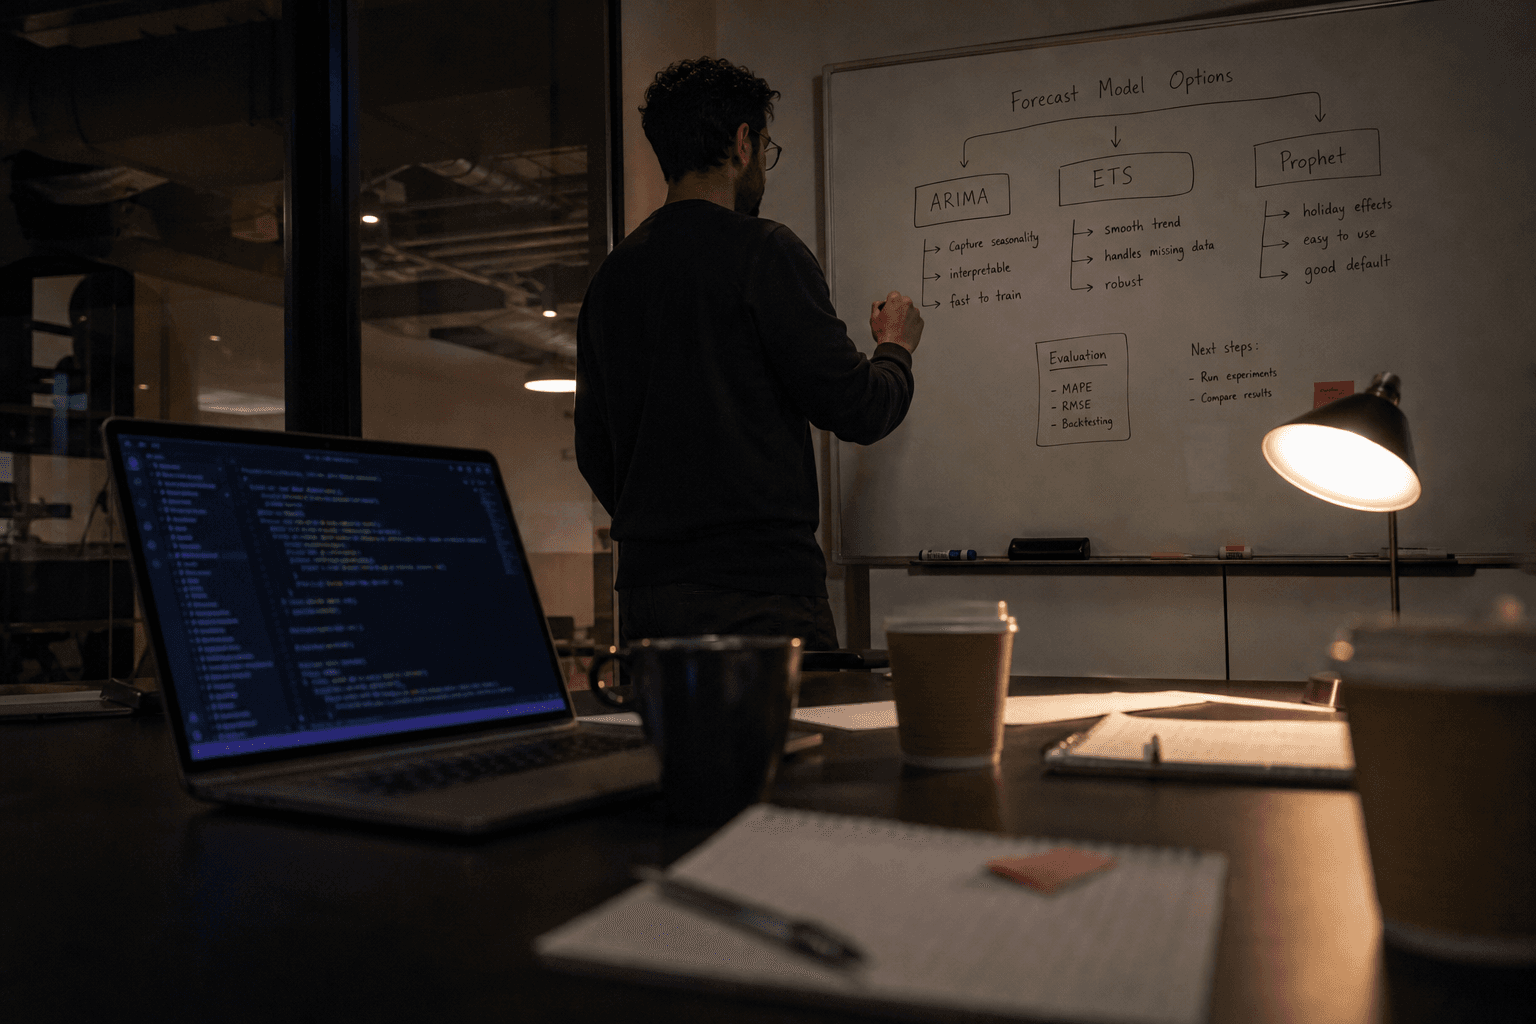
The right model depends on data volume, the number of series you need to forecast, and how much nonlinear structure exists in demand (promotions, cannibalisation effects, cross-SKU substitution). Statistical models remain a strong, explainable default for stable, low-volume series. Machine learning and deep learning models tend to add value when you have many related series, rich external features, or demand patterns that classical models can't capture.
| Approach | Best suited to | Explainability | Data volume needed | Typical effort |
|---|---|---|---|---|
| Classical statistical (ARIMA, exponential smoothing, Prophet-style) | Single or few series, stable seasonality | High | Low–Moderate | Low |
| Gradient-boosted trees on engineered features | Many SKUs/locations, known external drivers | Moderate | Moderate | Moderate |
| Global deep learning models (e.g. DeepAR-style, temporal transformers) | Thousands of related series, shared patterns across SKUs | Lower | High | Higher |
| Hierarchical/reconciliation methods | Forecasts needed at multiple levels (SKU, region, network) that must sum consistently | Depends on base model | Moderate–High | Moderate–Higher |
A sensible default for most logistics and manufacturing businesses starting out is to benchmark a classical model against a gradient-boosted approach before reaching for deep learning. The uplift from more complex models needs to be weighed against the cost of maintaining them in production — a point we cover in our ai-product-strategy work with clients.
What data do you need before you start?
At minimum you need clean, consistent historical transaction data (orders, shipments, or production volumes) at the time grain and hierarchy level you intend to forecast, typically 2–3 years of history to capture seasonal cycles. Beyond that, forecast accuracy usually improves most from adding external context: promotional calendars, pricing changes, known supply constraints, and, where relevant, weather or public holiday data.
The most common blocker isn't model choice — it's data readiness. Order data fragmented across ERP, WMS, and spreadsheets, inconsistent SKU hierarchies, and missing promotional history are the issues that stall forecasting programs long before modelling begins. If your data currently lives in disconnected systems, establishing a proper pipeline and feature store is the prerequisite step; this is the kind of work we scope under data-infrastructure.
Cloud ML platforms now offer purpose-built components for this — feature stores designed to manage time-series and tabular features, managed training and hyperparameter tuning jobs, and pipeline orchestration for retraining on a schedule. These are useful building blocks, but they are generic infrastructure; none of them encode demand forecasting methodology or supply chain domain logic on your behalf. That modelling work still has to be done by a team that understands your specific demand drivers.
How does forecasting integrate with your ERP and WMS?
A forecast only creates value once it reaches the systems planners actually use — typically your ERP for purchasing and production planning, and your WMS or TMS for inventory allocation and fleet scheduling. Integration usually means writing forecast outputs back into existing planning tables or exposing them via an API that your planning tools can consume, rather than asking planners to work from a separate dashboard.
This is often the hardest engineering problem in the whole program, harder than the forecasting model itself. Legacy ERP systems weren't built with machine learning outputs in mind, and many have rigid batch-update cycles or limited API surfaces. Where the existing platform can't accommodate a forecast feed cleanly, some modernisation of the integration layer is usually required — work we cover under application-modernisation. Underestimating this step is one of the most common reasons forecasting pilots never reach production.
What does a realistic rollout look like?
A pragmatic rollout starts narrow: pick one product category or distribution centre, establish a baseline with a simple model, and measure forecast accuracy against what planners currently achieve manually before expanding scope. Treat the first few months as validating the full pipeline — data ingestion, model output, and integration into planning workflows — rather than chasing the most sophisticated model available.
Once the pipeline is proven, expanding to more SKUs, locations, or a hierarchical reconciliation layer is largely an engineering and data scaling exercise rather than a research problem. Ongoing model monitoring matters here: demand patterns shift with market conditions, so forecasts need scheduled retraining and drift monitoring, not a one-off deployment. This operational layer is part of what we build under ai-engineering.
Do you need a dedicated data science team to build this?
Not necessarily, and for many organisations it isn't the most efficient starting point. A small embedded team that understands both the modelling and the ERP/WMS integration can usually get a first production forecast live faster than hiring and building an in-house capability from scratch, particularly if your internal team doesn't yet have deep time-series or MLOps experience.
What matters more than team size is sequencing: get the data foundation right, validate a simple model against a real baseline, and solve the integration problem early — rather than optimising model architecture before you know the pipeline works end to end.
For more on related decisions — including how to evaluate AI investments and when to build versus buy — browse our insights.
If you're exploring time-series demand forecasting for your supply chain, we can help scope a pragmatic first step, from data readiness through to ERP/WMS integration.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.