Self-Serve Analytics Enablement for Non-Technical Teams
Self-serve analytics only works when the data foundation, semantic layer, and training are right — not just the dashboard tool. A practical guide to tooling, access models, and enablement for data leaders.
What Is Self-Serve Analytics Enablement?
Self-serve analytics enablement is the combination of tooling, access design, and training that lets business teams answer their own data questions without filing a ticket with the data team. Done well, it reduces the queue of ad hoc requests landing on data engineers and analysts, while keeping a single, governed version of the truth that everyone queries against.
The promise is simple to state and hard to deliver: give a sales ops manager, a marketing lead, or a customer success team the ability to explore metrics directly, without exposing them to raw tables, inconsistent definitions, or data they shouldn't see. Most organisations that attempt this underestimate the governance and change-management work required and overinvest in the dashboard tool itself.
Why Do Self-Serve Analytics Initiatives Stall?
Self-serve analytics efforts usually stall for one of three reasons: the underlying data isn't trustworthy enough to hand over, there's no agreed definition layer so every team calculates "revenue" or "active user" differently, or the rollout skips training and assumes a nice interface is enough. The tool is rarely the blocker — the data foundation and the operating model are.
A common failure pattern looks like this: a BI tool is purchased, a handful of dashboards are built, and the rest of the organisation is told to "go explore." Without a semantic layer defining shared business logic, different teams quietly produce conflicting numbers for the same board meeting. Trust collapses, and everyone reverts to asking the data team for a bespoke query — which is the exact bottleneck self-serve was meant to remove. This is why foundational work on data infrastructure usually has to come before — or alongside — any tooling decision.
What Tooling Choices Actually Matter?
The tooling decision that matters most isn't which BI product you buy — it's whether you have a semantic layer sitting between raw data and the dashboard. A semantic layer is a governed layer that defines business metrics, dimensions, and relationships once, so every downstream tool and user queries the same consistent definitions rather than writing their own logic.
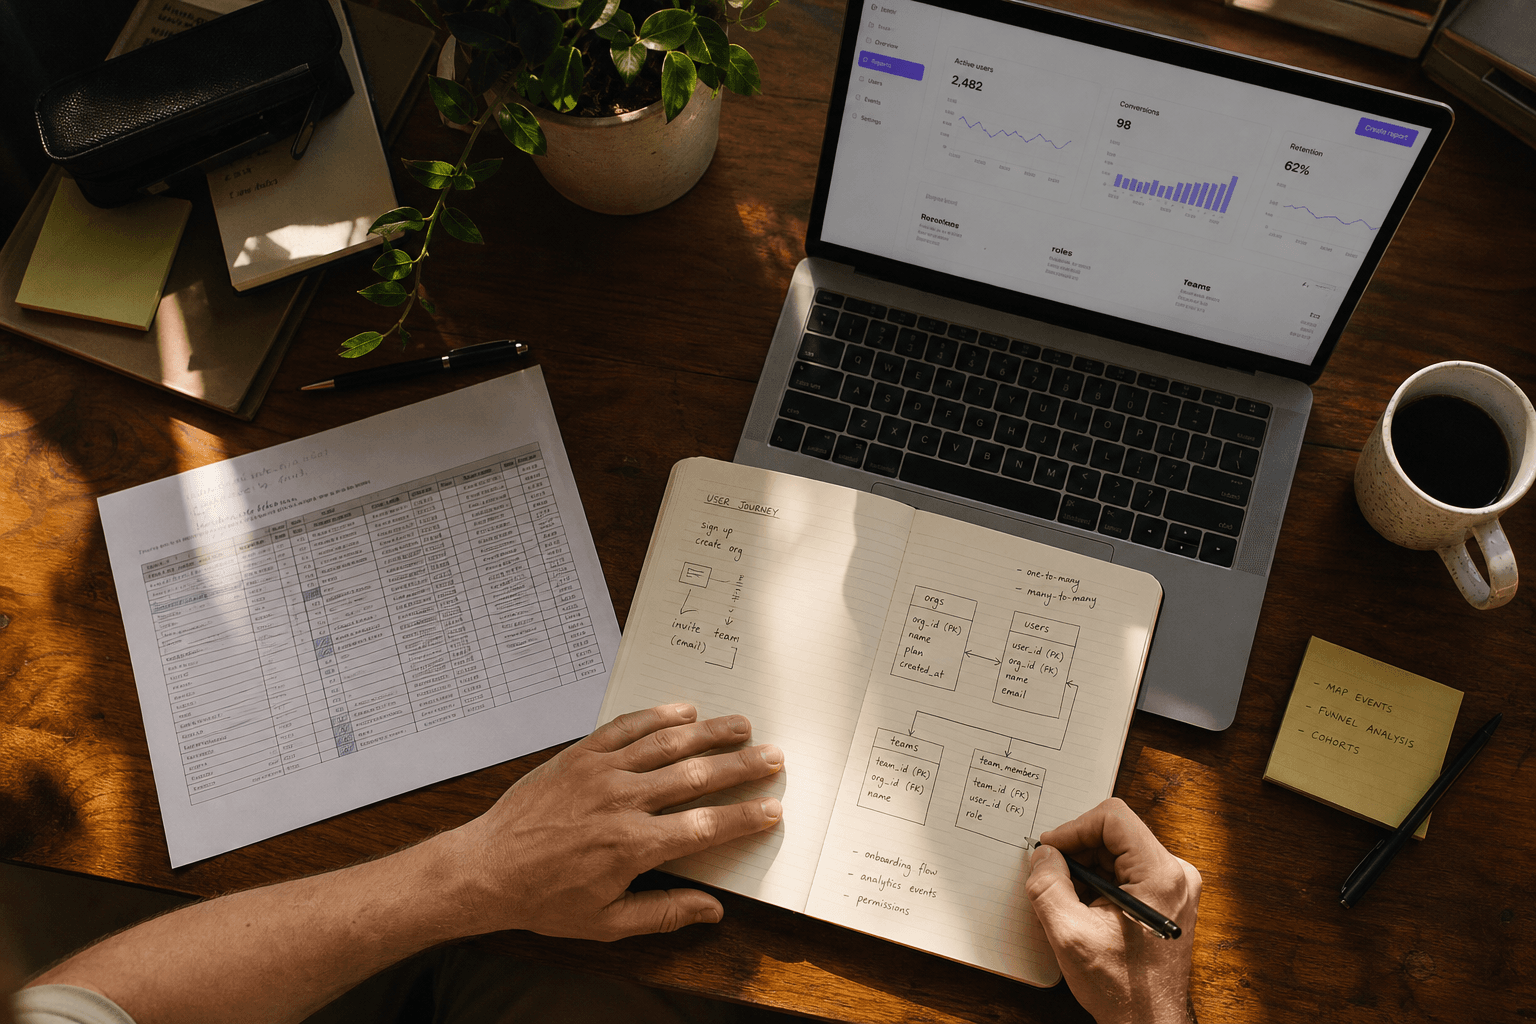
Natural-language query interfaces and AI-assisted analytics features are increasingly bundled into mainstream BI platforms, and they can lower the barrier further for non-technical users by letting them ask questions in plain English. These are genuinely useful for simple lookups, but they inherit whatever ambiguity exists in your underlying metric definitions — an AI assistant answering against an ungoverned data model will produce confident, inconsistent answers just as readily as a human would. The tool is an accelerant, not a substitute, for a clean semantic layer.
| Approach | Governance effort | Risk of inconsistent numbers | Best suited to |
|---|---|---|---|
| Raw table access + SQL | Low setup, high ongoing support burden | High | Small analytics teams, early-stage data maturity |
| Dashboard-only (fixed reports) | Low | Low, but limited flexibility | Stable, repetitive reporting needs |
| Self-serve BI with semantic layer | Higher upfront investment | Low | Growing teams with multiple business functions asking varied questions |
| Self-serve BI with NL/AI query assist | Requires semantic layer as a prerequisite | Low if semantic layer is solid; high if not | Teams wanting to lower the skill barrier further for casual users |
How Should Access and Governance Models Work?
Access design for self-serve analytics should be role-based and tied to certified datasets, not blanket access to every table in the warehouse. Row-level security — restricting which rows a user can see based on their role, region, or team — lets a single dashboard serve many audiences safely, rather than building a separate report per permission tier.
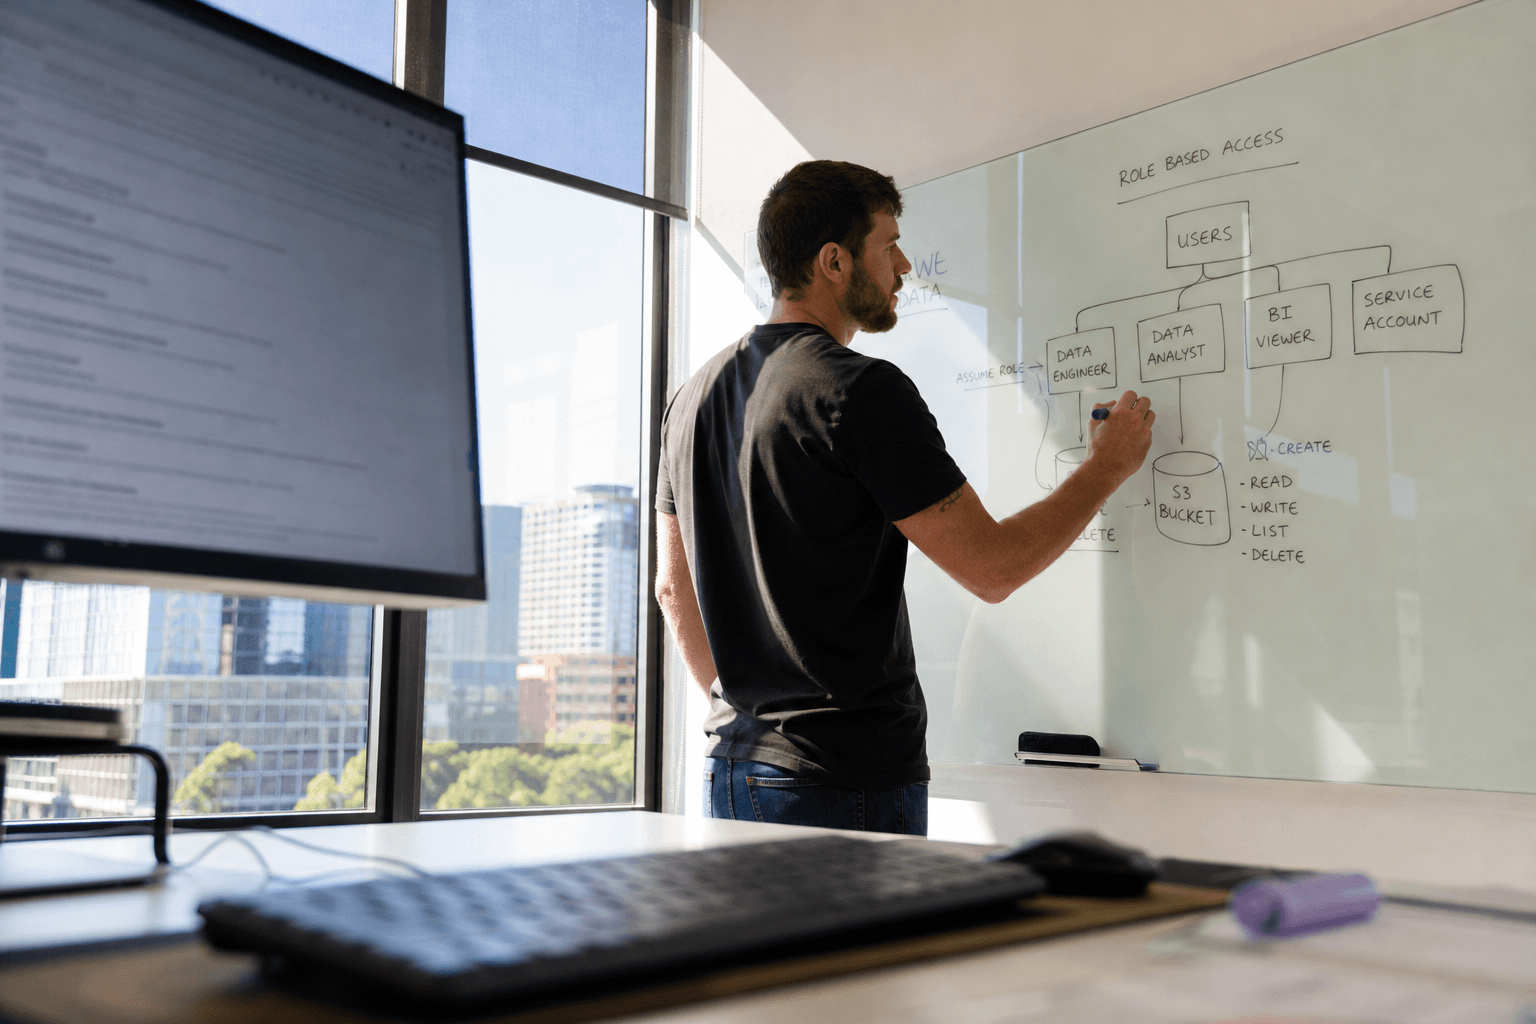
A practical model distinguishes between "certified" datasets that are governed, documented, and safe for broad self-serve use, and "sandbox" datasets still in development that only the data team and advanced analysts touch. This distinction needs to be visible in the tool itself — users should always be able to tell whether they're looking at a trusted, certified source or an exploratory one. Data governance frameworks referenced by the Australian Government's data and digital strategy, and privacy obligations under the Australian Privacy Principles administered by the OAIC, are also worth factoring into access design wherever customer or employee data is involved — self-serve convenience should never come at the cost of compliance.
What Training Approaches Actually Change Behaviour?
Training for self-serve analytics works best when it's tied to real questions the team already has, not a generic tool walkthrough. Running a short session where a sales manager builds the exact dashboard they need for their next pipeline review embeds the skill far more effectively than a one-off onboarding webinar covering every feature in the platform.
Ongoing enablement matters more than the initial rollout. A nominated analytics champion within each business team, a lightweight internal documentation hub describing what each certified metric means, and a regular (even monthly) office-hours session with the data team all help sustain adoption. Without this cadence, usage typically decays within a few months as staff turn over or forget the initial training.
A Practical Rollout Sequence
Most successful rollouts follow a similar sequence: stabilise and document the data model first, define a small set of certified core metrics, build role-based access and a handful of template dashboards, then open up guided self-serve exploration — expanding scope only as trust in the numbers is established. Trying to open full self-serve access on day one, before the data foundation is solid, is the most common reason these programs are abandoned within a year.
For data leaders weighing where AI fits into this picture — whether that's a natural-language query layer, an internal AI agent that answers metric questions, or a retrieval system over your documentation — it's worth scoping that as a distinct, later-stage capability rather than the starting point. Our ai-engineering work with clients usually starts once the governed data foundation is in place, not before. You can read more approaches like this on our insights page.
Where to Start
If your data team is spending more time answering one-off requests than building the infrastructure to prevent them, that's usually a sign the foundation — not the dashboard tool — needs attention first. If you're exploring self-serve analytics enablement for your organisation, we can help assess where the real bottlenecks are and design a governed rollout that your business teams will actually trust and use.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.