MDM and Identity Resolution: A Guide for Data Leaders
Master data management and identity resolution solve the same underlying problem: too many systems, too many conflicting versions of the truth. Here's how matching, merging, and governance actually work in practice.
Master data management (MDM) is the set of processes and tools used to create and maintain a single, trusted, authoritative record for core business entities — customers, products, suppliers, locations — across every system that references them. Identity resolution is the technical matching process underneath it, determining whether records from different systems refer to the same real-world entity. Together they solve a problem most growing companies recognise immediately: a CRM here, a billing platform there, a product catalogue inherited from an acquisition, a support tool nobody fully decommissioned. Each system has its own version of "the customer" or "the product," and none of them agree.
What is master data management?
The outcome of a well-run MDM program is a "golden record": the version of an entity that the rest of the business treats as the source of truth, even though the underlying data still lives in multiple source systems.
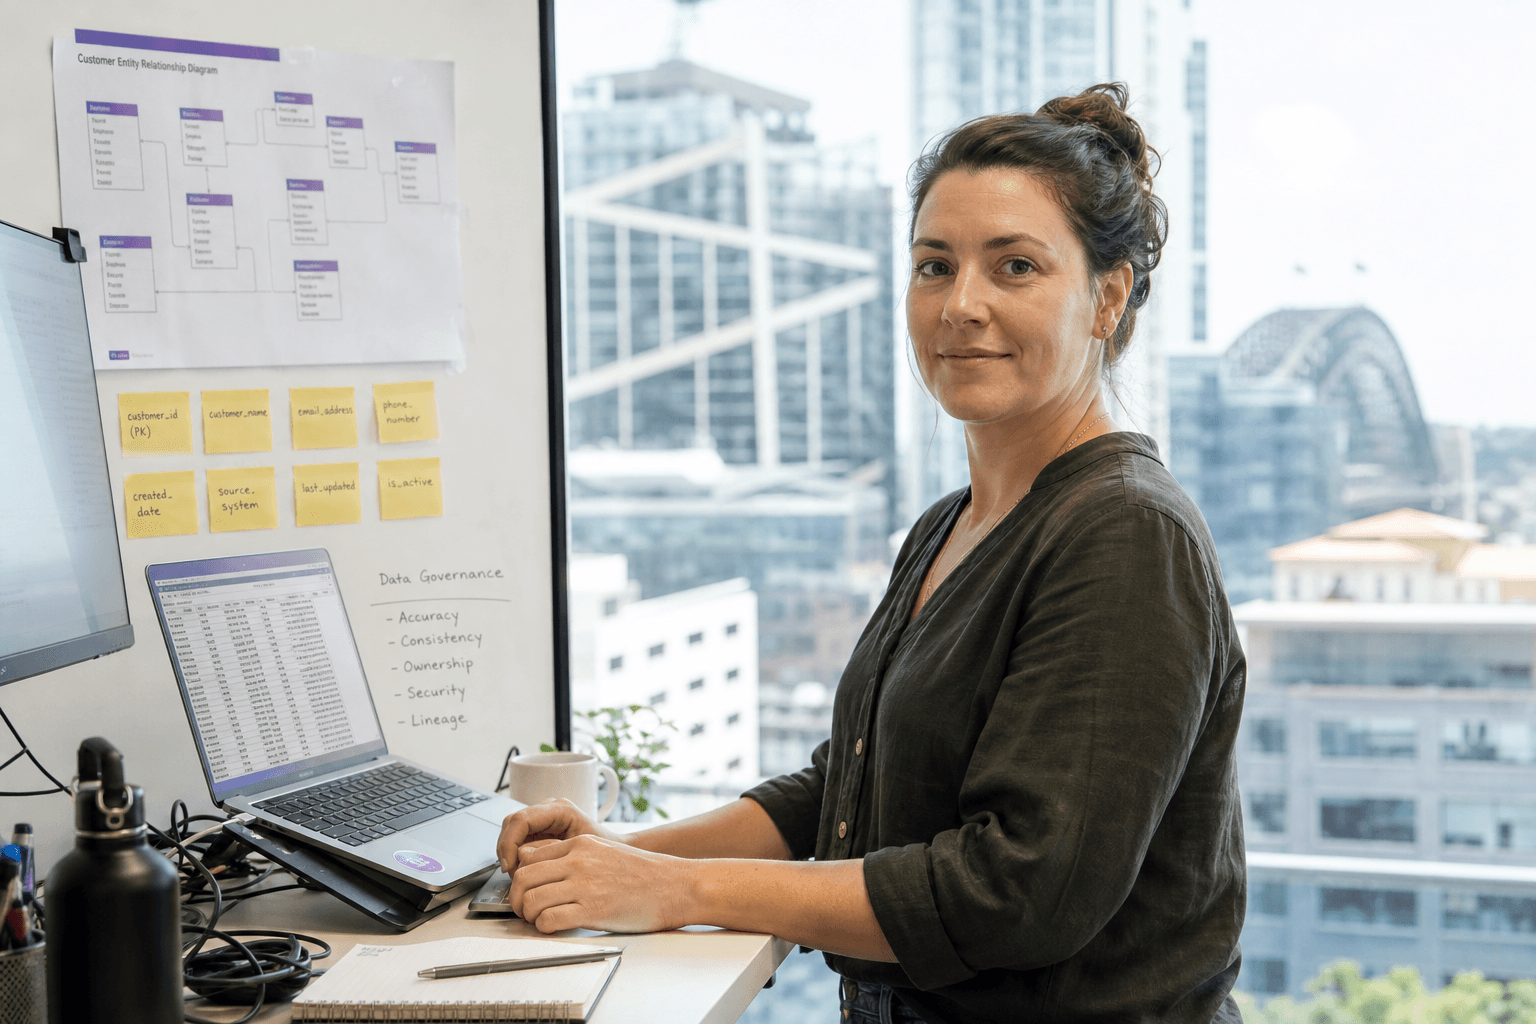
MDM is not a single piece of software. It is a discipline that spans data modelling, matching logic, governance, and ongoing stewardship. Tooling can accelerate parts of this, but tooling alone does not constitute an MDM program. We see this most often in businesses that have grown through acquisition or rapid product expansion, where every new system or integration adds another definition of what should be a shared concept.
What is identity resolution, and how is it different from MDM?
Identity resolution is the specific technical process of determining whether two or more records — possibly from different systems, with different formats and different fields — refer to the same real-world entity. It is the engine underneath MDM: before you can build a golden record, you need to know which records should be merged into it.
In practice, identity resolution answers questions like: is the "J. Smith" in your support ticketing system the same person as "Jane Smith" in your billing platform, and the same account as "Smith, J" in a spreadsheet uploaded by sales three years ago? MDM is the broader governance and record-management layer; identity resolution is the matching mechanics that feed it.
How do match and merge strategies actually work?
Matching approaches generally fall into two camps — deterministic and probabilistic — and most mature identity resolution programs use both, applied in layers rather than as a single pass.
Deterministic matching relies on exact or near-exact agreement on a strong identifier: an email address, an account number, or a combination of fields reliable enough to treat as unique. It is fast, auditable, and easy to explain to a compliance team, but it misses variation — typos, nicknames, format differences, and records that simply don't carry a shared strong identifier.
Probabilistic matching scores the likelihood that two records refer to the same entity based on weighted similarity across multiple fields — name, address, phone, behavioural signals — even when no single field matches exactly. This catches more true matches but introduces false positives, which is why probabilistic systems need a review threshold: auto-merge above a high confidence score, queue for human review in the middle band, and leave unmerged below it.
The merge step itself needs explicit survivorship rules — which source system wins when two records disagree on a phone number, which field takes precedence by recency, and how conflicts get logged rather than silently overwritten. Without documented survivorship rules, every merge becomes a judgement call made differently by whoever happens to run the job.
| Approach | Strength | Weakness | Best suited to |
|---|---|---|---|
| Deterministic matching | High precision, auditable | Misses variation and typos | Entities with a reliable shared identifier |
| Probabilistic matching | Higher recall, catches fuzzy duplicates | Requires tuning, risk of false merges | Customer and contact data with inconsistent entry |
| Rules-based with human review | Transparent, defensible | Slower, labour-intensive at scale | Regulated or high-stakes entity types |
| ML-assisted matching | Improves over time, handles scale | Needs training data and ongoing monitoring | High-volume, high-variability datasets |
Who should own data governance for MDM?
Governance ownership needs to sit with a named data leader, not a committee that meets quarterly and defers every decision. In practice, the most durable model pairs a single accountable owner — typically a Head of Data or Data Engineering Manager — with a small group of data stewards drawn from the business functions that create and consume the data, such as sales operations, product, and finance.
The accountable owner holds the budget and the decision rights on matching rules and survivorship logic. The stewards are the ones who can say, with authority, which source system should be trusted when records conflict, because they understand how the data is actually entered and used day to day. Without stewards embedded in the business, governance decisions get made by whoever wrote the pipeline, which is rarely the right person to adjudicate a business rule.
It's also worth naming data quality as an operational responsibility, not a one-off project. New source systems get added, acquisitions bring in new entity formats, and matching rules that worked at one scale start producing false merges at another. Governance has to be a standing function with a review cadence, not a document that gets written once and filed away.
When is MDM tooling worth the investment?
Dedicated MDM tooling earns its cost once the manual overhead of resolving conflicting records starts outpacing what a small team can manage by hand — typically when you're reconciling more than a handful of source systems, operating across multiple business units, or supporting regulated processes where an auditable match-and-merge trail is a requirement rather than a nicety. Below that threshold, a well-documented set of matching rules, a clear survivorship policy, and disciplined stewardship can get you most of the way there without a new platform purchase.
The decision is rarely about the tool first. It's about whether the underlying data infrastructure can support reliable identifiers, consistent schemas, and a pipeline that can actually execute the matching logic you design. Many organisations buy MDM software before they've resolved these foundational gaps, and end up with an expensive system reinforcing the same inconsistent data it was meant to fix.
This is also where MDM intersects with AI adoption. Clean, trusted master data is a prerequisite for most production AI use cases — a recommendation engine, a support automation workflow, or an ai product strategy built on customer history all depend on knowing, reliably, which records represent which customer. Teams that skip identity resolution often find their AI initiatives stall not because the model is wrong, but because the data feeding it is fragmented. Good ai engineering practice starts with this kind of foundational data work, not after it.
For organisations still running on legacy systems that were never designed to share a common data model, MDM and application modernisation often need to happen together — untangling the data model is part of untangling the platform. We tend to recommend starting with an honest audit of your current source systems, matching needs, and governance capacity before evaluating any tooling. For more on how we approach this kind of work, see more insights on our site.
If you're weighing up whether your organisation needs a formal MDM program, or you're further along and struggling with match quality or governance ownership, we're happy to talk through what we're seeing in similar Australian organisations. Get in touch to start a conversation.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.