Measuring Data Engineering Team Productivity: A Framework
Most engineering teams track DORA metrics for software delivery, but data engineering needs a different lens. This article sets out a practical framework covering throughput, pipeline reliability, and stakeholder satisfaction for growing data functions.
Most engineering leaders have a dashboard for software delivery — deployment frequency, lead time, change failure rate, mean time to recovery. Fewer have an equivalent for their data engineering function, even as pipelines, models, and analytics infrastructure become just as critical to the business. This article sets out a practical way to think about data engineering productivity that doesn't rely on borrowing software metrics that don't quite fit.
What does "productivity" actually mean for a data engineering team?
Data engineering productivity is the rate at which a team delivers reliable, trusted data assets that the business can act on — not simply the volume of pipelines shipped or lines of transformation code written. A productive data function reduces the time between "we need this data" and "we can trust this data enough to make a decision with it." That outcome depends on throughput, reliability, and how well the output serves the people consuming it — three dimensions, not one.
Many growing Australian organisations reach for data maturity because they have accumulated data assets but lack the internal data engineering or ML expertise to turn them into decision-ready infrastructure. That gap — assets without capability — is exactly where productivity measurement becomes useful: it tells you whether the team you're building (or the team you already have) is closing that gap or just adding to the backlog.
Why don't DORA metrics map cleanly onto data engineering?
DORA metrics measure how fast and safely software changes reach production, which assumes a relatively stable notion of "a deploy" and "a failure." Data pipelines break that assumption: a pipeline can deploy cleanly and still produce wrong numbers because of upstream schema drift, a vendor API change, or a subtle data quality issue that has nothing to do with the code that moved.
In software delivery, a failed deploy is usually visible within minutes. In data engineering, a failure might be a slow leak — a dimension table quietly dropping rows for three weeks before someone in finance notices the monthly numbers don't reconcile. That's why data teams need metrics that account for correctness and trust, not just deployment velocity. DORA is still a useful reference point for your platform and application code; it's just not sufficient on its own for the data layer.
What throughput metrics actually matter?
Throughput for a data team should measure how quickly new data becomes usable and how much of the team's capacity goes toward new value versus maintenance. Useful throughput signals include cycle time from data request to delivered, trusted dataset; the ratio of time spent on new pipelines versus firefighting and rework; and the backlog age of outstanding data requests from stakeholders.
Be cautious with pipeline count or lines of transformation logic as headline metrics — they reward volume over value and can incentivise unnecessary pipeline sprawl. A smaller number of well-governed, reusable data assets usually indicates a healthier function than a large number of one-off extracts built to satisfy individual requests.
How do you measure pipeline reliability?
Pipeline reliability measures whether data arrives on time, in the expected shape, and with the expected values — and how quickly issues are caught and resolved when it doesn't. The core signals are pipeline success rate, data freshness against SLA, and time to detect and time to resolve data quality incidents.
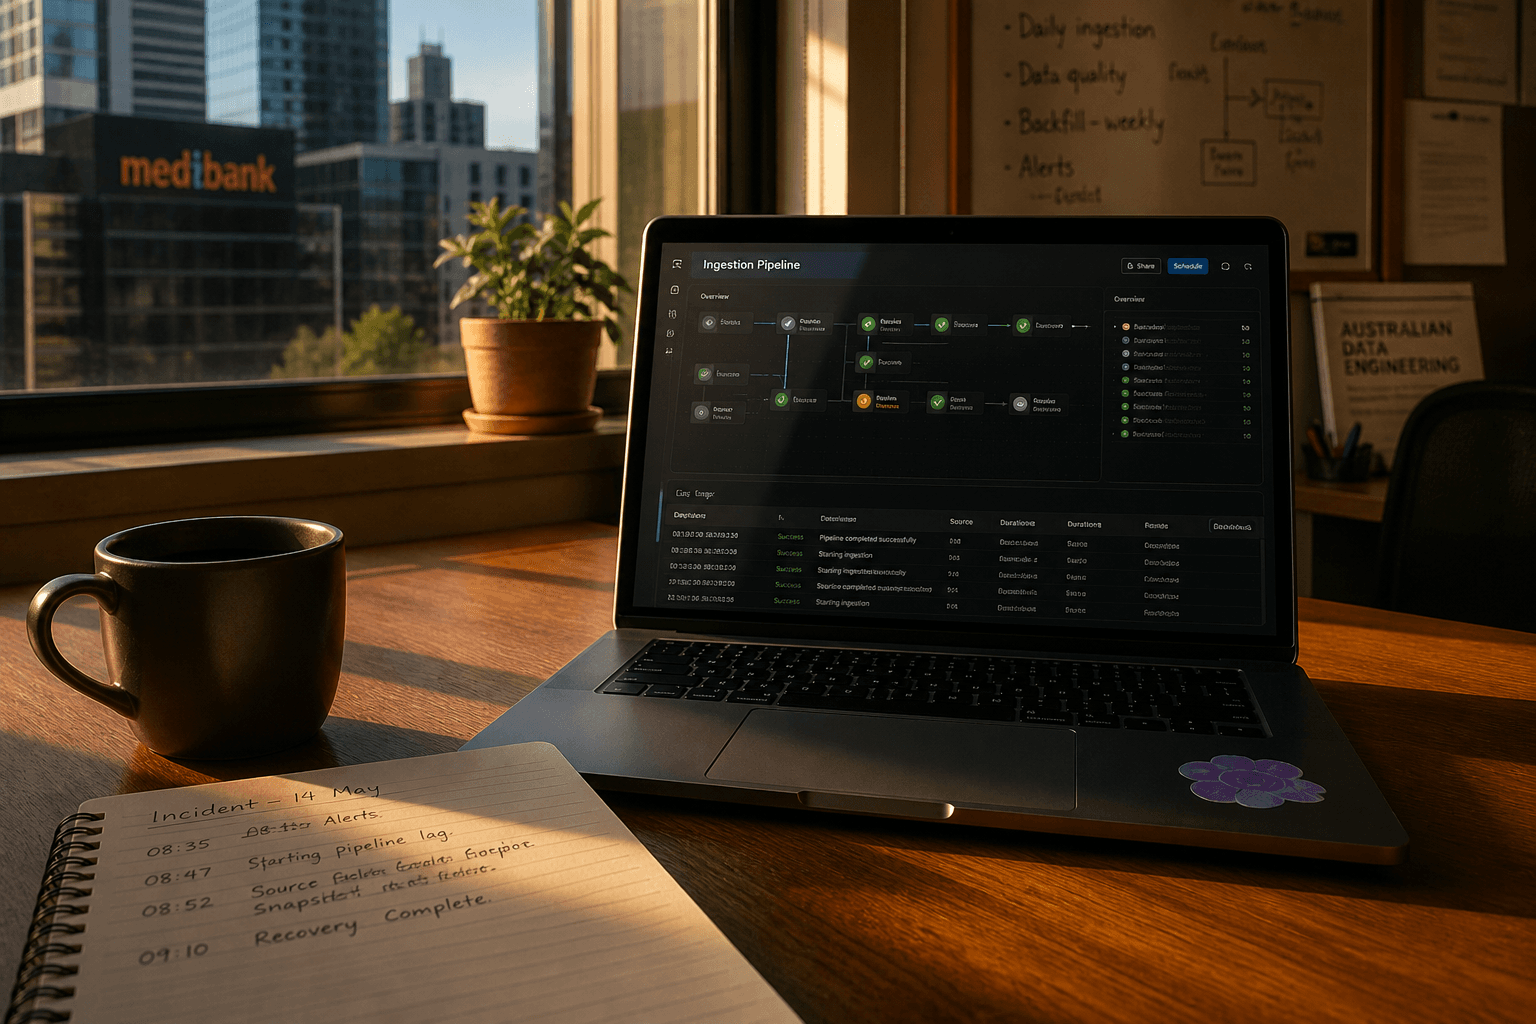
The detection metric matters more than most teams realise. A pipeline that fails loudly and gets fixed in an hour is far less damaging than one that fails silently and gets discovered by a stakeholder three weeks later when a report looks wrong. If your team can't tell you how an incident was first detected — automated test, monitoring alert, or a stakeholder complaint — that's itself a reliability signal worth tracking. Teams with mature data quality practices increasingly treat data SLAs the way software teams treat uptime SLAs, with defined freshness, completeness, and accuracy thresholds per dataset.
How do you measure stakeholder satisfaction?
Stakeholder satisfaction measures whether the people consuming data — analysts, product managers, finance, executives — actually trust and use what the data team delivers. This is the dimension most data functions skip, because it's harder to automate than a dashboard count, but it's often the clearest signal of real productivity.
Practical ways to capture it include a lightweight quarterly survey of data consumers (trust, timeliness, ease of self-serve access), tracking how often stakeholders build workarounds (shadow spreadsheets, manual exports) because the sanctioned data product doesn't meet their need, and monitoring adoption of self-serve analytics tools versus requests routed back to the data team. A data team can hit every throughput and reliability target and still be unproductive in the eyes of the business if the outputs don't answer the questions people actually have.
How do software delivery and data engineering metrics compare?
| Dimension | Software delivery (DORA-style) | Data engineering |
|---|---|---|
| Speed | Deployment frequency | Cycle time from request to trusted dataset |
| Stability | Change failure rate | Data quality incident rate |
| Recovery | Mean time to recovery | Time to detect + time to resolve data incidents |
| Correctness | Not directly measured | Freshness and accuracy against data SLA |
| Consumer trust | Rarely tracked directly | Stakeholder satisfaction and shadow-system usage |
Treat this as a starting structure, not a rigid scorecard. The right mix of metrics depends on how mature your data infrastructure already is and how directly the business relies on data for decisions versus reporting.
How should a growing data function start measuring this?
Start small: pick two or three metrics per dimension, agree on them with the stakeholders who consume data (not just within the engineering team), and review them quarterly rather than weekly. Overbuilding a metrics program before you have reliable instrumentation just creates another maintenance burden.
A sensible sequence is: first get visibility into pipeline health and incident detection, because you can't improve what you can't see; then establish a baseline cycle time for common data requests; then introduce a lightweight stakeholder feedback loop. Organisations with existing data assets but limited internal data engineering depth often find the instrumentation step alone — proper monitoring, lineage, and alerting — delivers the biggest early improvement, because it surfaces problems that were previously invisible. This is foundational work that sits squarely in data infrastructure rather than in any single pipeline build.
When does it make sense to bring in outside support?
It's worth bringing in external expertise when your team has the data assets but not the engineering depth to build reliable pipelines, when you need an independent read on whether current output matches business needs, or when scaling the function faster than you can hire makes sense. This is a common pattern among growing organisations that have invested in data collection ahead of data engineering capability.
An outside review can also help distinguish a genuine capability gap from a prioritisation problem — sometimes the team isn't under-resourced, it's building the wrong things for the business. That assessment often connects naturally to broader questions around AI product strategy and, where legacy systems are constraining pipeline design, application modernisation or AI engineering work to get the underlying platform into a state that supports reliable data delivery.
For more on building the foundations that make these metrics possible in the first place, see our insights on data infrastructure and MLOps practices.
If you're trying to work out whether your data engineering function is delivering the value it should be, we can help — starting with a straightforward look at what you're measuring today and what's missing.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.