Engineering Documentation That Survives Team Turnover
As engineering teams scale, critical system knowledge often lives in one person's head. This guide covers how architecture decision records, runbooks, and onboarding documentation reduce single points of failure and keep knowledge inside the organisation.
Every scaling engineering team eventually hits the same wall: the person who understands why the payments service is architected the way it is, or how to recover the ingestion pipeline at 2am, leaves — and takes that knowledge with them. Documentation is how teams turn tribal knowledge into an organisational asset. This guide covers the three practices that matter most: architecture decision records, operational runbooks, and onboarding documentation, plus how to reduce the single points of failure that make any one departure a crisis.
What is an architecture decision record (ADR)?
An architecture decision record (ADR) is a short, versioned document that captures a significant technical decision, the context that drove it, the alternatives considered, and the trade-offs accepted. ADRs are not design specs — they are a historical record of why, written at the moment a decision is made, so future engineers don't have to reverse-engineer intent from code or Slack threads.
The format matters less than the discipline. Most teams use a lightweight template: title, status (proposed, accepted, superseded), context, decision, and consequences. The structured approach described in the ISO/IEC/IEEE 42010 standard for architecture description is a useful reference point for teams that want a more formal model, though few scale-ups need that level of rigour day to day. What matters is that ADRs live in version control next to the code they describe, not in a wiki that drifts out of sync.
ADRs earn their value on the day someone asks "why didn't we just use a managed queue here?" and the answer already exists, dated, attributed, and honest about the constraints at the time.
What is a runbook, and why does it matter for reliability?
A runbook is a step-by-step operational document that tells an on-call engineer exactly what to do when a specific system fails — how to detect it, how to triage it, how to mitigate it, and who to escalate to if the fix isn't obvious. Runbooks exist to compress the time between "something is broken" and "someone competent is fixing it," regardless of who is holding the pager.
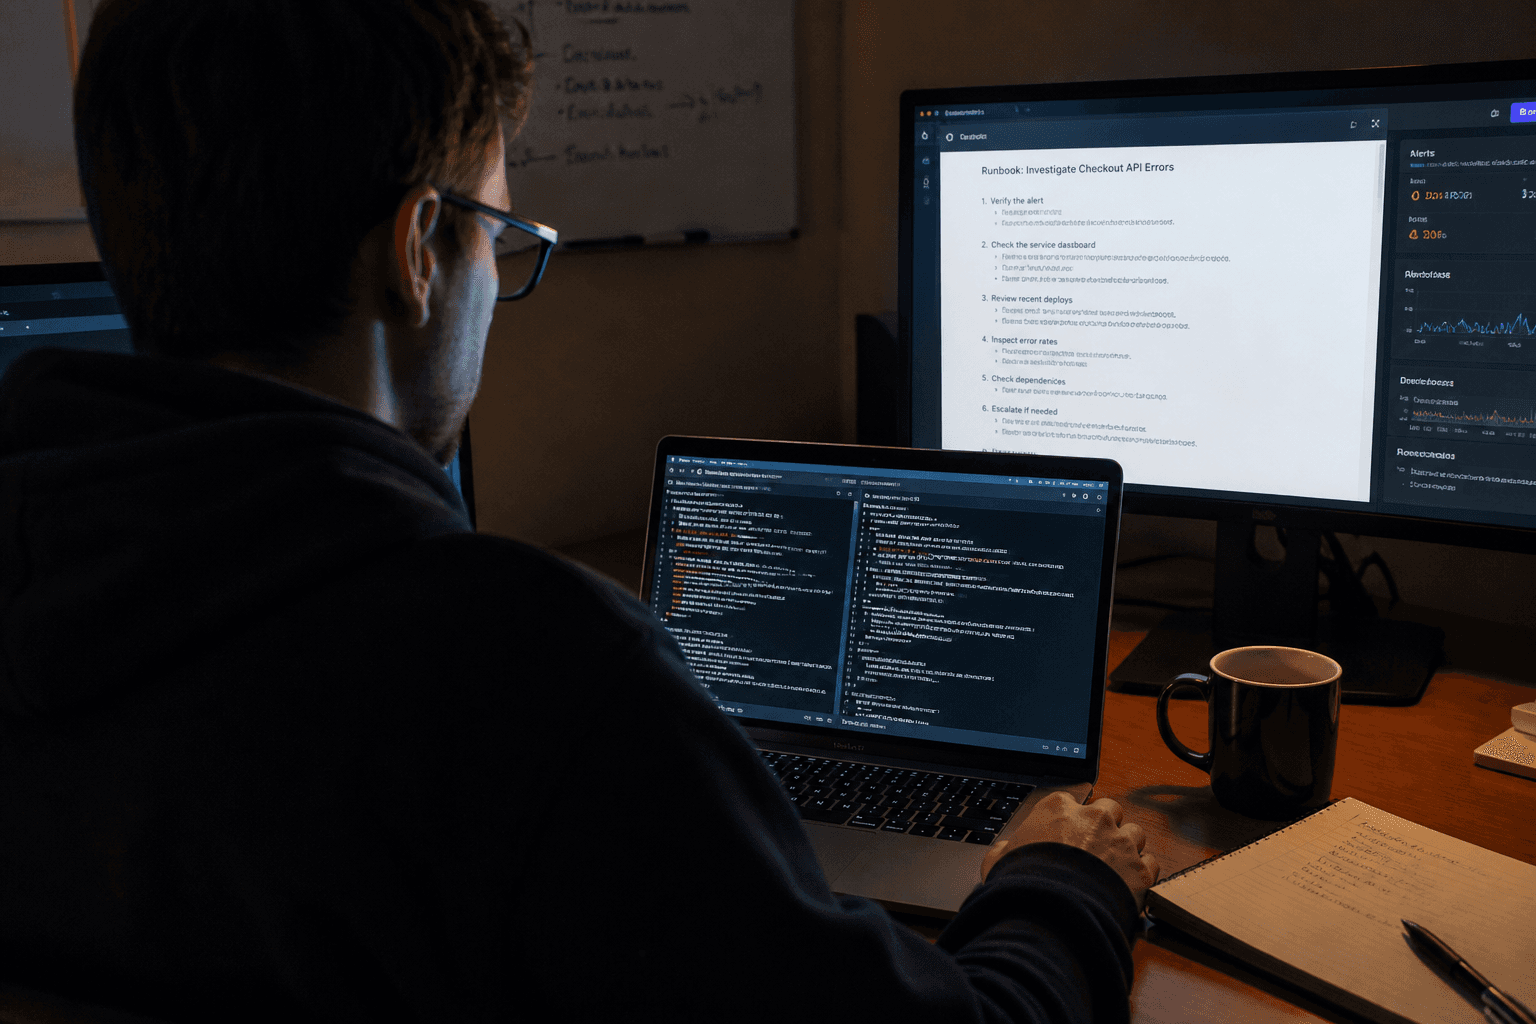
Good runbooks are written for the least experienced person who might reasonably be on call, not the engineer who built the system. They should name the specific dashboards, alerts, and commands involved, describe known failure modes in plain language, and be updated every time an incident reveals a gap. A runbook that hasn't been touched in a year is a liability disguised as an asset — it gives false confidence until the moment it's needed.
Organisations that treat incident response as a documentation exercise, not just a Slack scramble, tend to recover faster and retain the lessons from each incident rather than relearning them.
How do you reduce single points of failure in an engineering team?
A single point of failure, in this context, is any system, decision, or operational process that only one person fully understands. Reducing it isn't about hiring more people — it's about deliberately spreading understanding through pairing, documentation, and rotation before the person holding that knowledge is unavailable, not after.
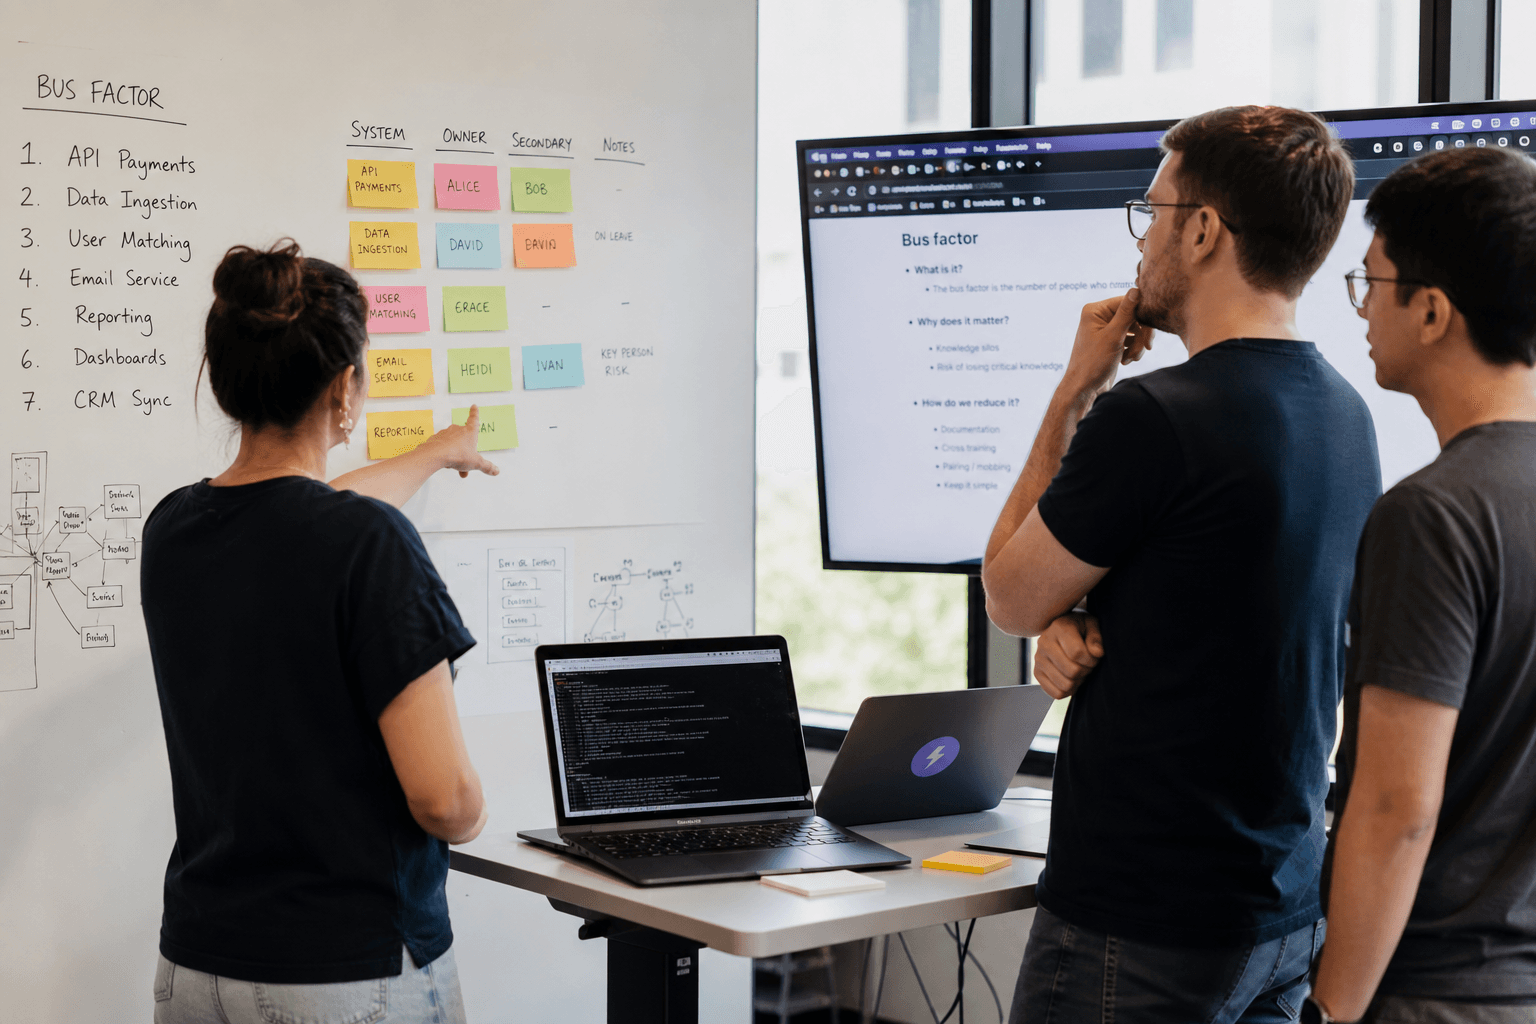
Practical steps that work well for growing teams:
- Rotate on-call and pairing assignments so more than one engineer touches every critical system, even systems with a clear "owner."
- Require an ADR for any decision that would be expensive to reverse — data model choices, vendor selection, service boundaries — not for every minor implementation detail.
- Run documentation reviews as part of code review, not as a separate, deprioritised task that only happens during onboarding pushes.
- Track a lightweight bus-factor map: for each critical system, who can operate it, and who is the backup? If the answer is "one person" for anything customer-facing, that's a flagged risk, not a footnote.
- Treat onboarding documentation as a living product, tested by having new hires actually use it in their first week and report where it broke down.
None of these require heavyweight process. They require the habit of writing things down at the moment of decision, not the moment someone asks.
Comparing the three core documentation types
Each type of documentation serves a different audience and a different moment in a system's life. Confusing them — for example, treating a runbook as a place to explain architectural rationale — is a common reason documentation programs stall.
| Type | Purpose | Written when | Primary audience | Review cadence |
|---|---|---|---|---|
| Architecture Decision Record (ADR) | Capture why a decision was made and what was traded off | At the moment of the decision | Future engineers, new hires, auditors | Rarely edited; superseded by new ADRs |
| Runbook | Guide incident response for a specific system or failure mode | Before first production incident, updated after each real one | On-call engineers, support staff | After every incident that touches it |
| Onboarding documentation | Orient a new engineer to the system, tooling, and team norms | Continuously, informed by new-hire feedback | New hires, contractors | Quarterly, or when it visibly fails a new hire |
Where does documentation fit into modernisation and platform work?
Documentation debt tends to surface at the same time as technical debt — a monolith nobody fully understands is usually also a system nobody has written an ADR for in years. When we work with engineering teams on application-modernisation, reconstructing the decision history of a legacy system is often the first step, because you can't safely decompose what you don't understand. The same applies to data-infrastructure work: pipelines built by a single data engineer who has since moved on are a common reason companies bring in outside help to rebuild with documentation and ownership built in from day one.
This is also why the engagement model matters. An embedded consultancy that transfers knowledge and leaves your team with something they own is a fundamentally different outcome to a tool your team has to operate without support. Documentation discipline is one of the clearest signals of which kind of engagement you're getting — if an engagement ends and nobody on your team can explain the decisions embedded in the system, the knowledge never actually transferred.
If you're building AI-driven capability into your product, the same discipline applies. Model selection, prompt design decisions, and evaluation criteria all deserve ADR-level treatment — see our related thinking in ai-engineering and ai-product-strategy for how we approach decision traceability in AI systems specifically. For more on how growing teams manage technology risk more broadly, browse our insights.
Getting started without boiling the ocean
You don't need a documentation platform overhaul to start. Pick your three most critical, least-understood systems, write a runbook for each, and require an ADR the next time someone proposes a decision that would be expensive to reverse. Review both in your next retrospective. The discipline compounds faster than the tooling does.
If your team is scaling and you're worried about what leaves when a key engineer does, we can help assess where your bus-factor risk actually sits and build the documentation habits that reduce it.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.