GraphRAG vs Vector Search: When Knowledge Graphs Win
Vector search is the right default for most RAG applications, but relationship-heavy enterprise data — fraud chains, compliance traceability, multi-hop customer views — often needs a knowledge graph instead. Here's how to decide which architecture fits your use case.
Enterprise teams building retrieval-augmented generation (RAG) systems default to vector search almost by habit. It is fast to stand up, works well with existing embedding models, and handles the majority of document Q&A use cases. But when your data is defined by relationships — who reports to whom, which supplier feeds which product line, how a claim links to a policy and a prior incident — vector similarity alone starts to miss the point. This is where GraphRAG and knowledge-graph-based retrieval come in.
This guide compares the two architectures on their own terms: what each does well, where graph-based retrieval earns its added complexity, and how to decide which one (or which combination) fits your enterprise AI roadmap.
What is vector search and when does it work well?
Vector search is a retrieval method that converts text into numerical embeddings and finds matches based on semantic similarity in that embedding space. It answers questions like "find me documents about this topic" extremely well, because it does not require exact keyword matches — it captures meaning.
Vector search is the right default for most RAG applications: internal knowledge bases, support documentation, policy lookup, and general-purpose question answering over unstructured text. It is comparatively simple to build, well supported by mature tooling, and cheap to maintain once embeddings are generated. If your data is mostly flat documents — PDFs, wikis, support tickets — and your questions are mostly "find relevant content," vector search alone is usually sufficient. Adding a graph layer here is often unnecessary complexity for marginal gain.```
The limitation shows up when a query depends on structure rather than similarity. "Which customers are affected if this supplier fails?" is not a similarity question — it is a traversal question. Vector search has no native concept of relationships, so it cannot reliably answer it, no matter how good the embeddings are.
What is GraphRAG and how is it different?
GraphRAG is a retrieval approach that combines a knowledge graph — a structured network of entities and the relationships between them — with a language model, so that retrieval follows explicit connections rather than relying solely on semantic similarity. A knowledge graph is a data model that represents entities (people, products, accounts, documents) as nodes and their relationships as edges, making those relationships queryable directly.
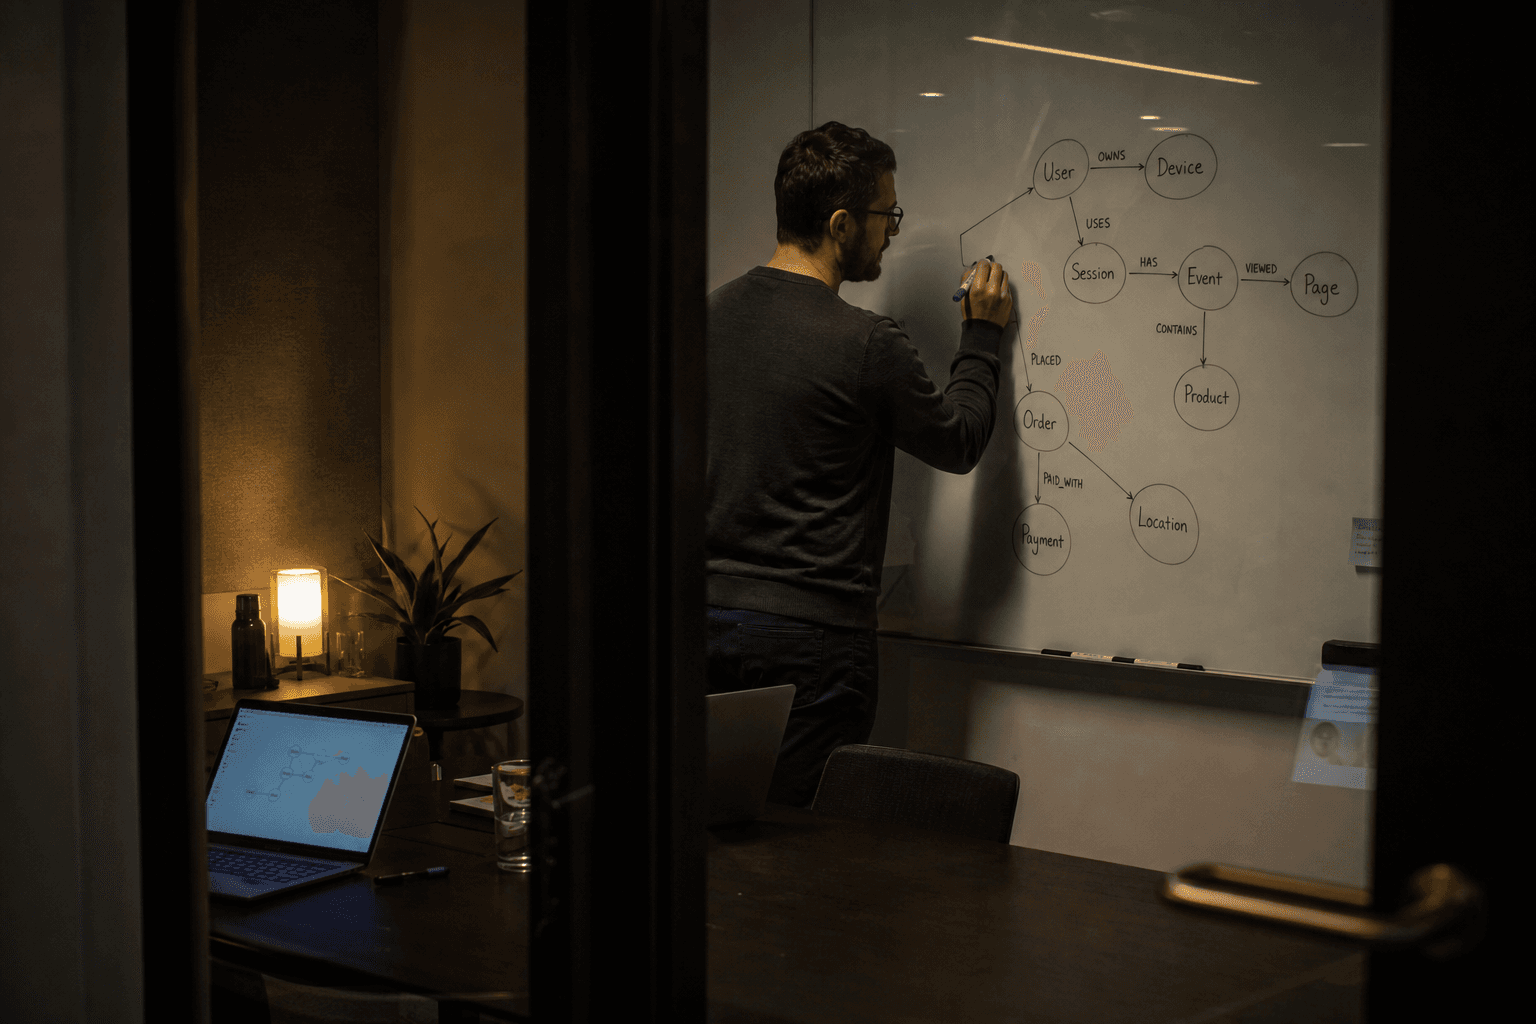
Instead of asking "what text looks similar to this query," GraphRAG asks "what is connected to this entity, and how." That makes it well suited to multi-hop reasoning: answering a question that requires following a chain of relationships across several steps, such as tracing an incident back through a dependency chain, or summarising everything connected to a specific customer across multiple systems.
GraphRAG implementations typically still use embeddings and vector search as part of the pipeline — for example, to identify starting entities or to retrieve supporting text alongside graph traversal results. It is rarely graph-only in practice; it is graph-plus-vector, used deliberately.
When does graph-based retrieval actually outperform vector search?
Graph-based retrieval tends to outperform vector search when the value of an answer depends on relationships, not just relevant content. Three patterns show up consistently in enterprise settings.
The first is multi-hop questions, where the answer requires connecting several pieces of information that are not adjacent in any single document — for example, linking a regulatory requirement to the specific products it affects and the customers holding those products. The second is entity-centric reasoning, where the organisation needs a complete, structured view of one entity (a customer, a device, a transaction) pulled from fragments scattered across many systems. The third is explainability requirements, where a decision — particularly in regulated sectors such as financial services or insurance — needs to be traceable through a visible chain of relationships rather than a similarity score the model cannot fully justify.
If none of those three patterns describe your use case, a knowledge graph is probably solving a problem you do not have yet.
How do the two architectures compare in practice?
The table below compares the two approaches qualitatively — not on invented performance numbers, but on the operational and architectural trade-offs that matter when deciding which to build.
| Dimension | Vector search (standard RAG) | GraphRAG (knowledge-graph retrieval) |
|---|---|---|
| Best suited to | Unstructured documents, general Q&A | Relationship-heavy, structured domains |
| Reasoning style | Semantic similarity, single-hop | Multi-hop traversal across entities |
| Explainability | Similarity score only | Traceable path through relationships |
| Build complexity | Lower — embedding pipeline and vector store | Higher — entity extraction, graph schema, ongoing maintenance |
| Data preparation | Chunking and embedding | Entity resolution, relationship extraction, schema design |
| Maintenance overhead | Re-embed on content change | Keep graph schema and entities current as the business changes |
| Typical use cases | Support knowledge bases, policy search | Fraud investigation, compliance tracing, supply chain impact analysis |
The honest takeaway from this comparison is that GraphRAG is not a universal upgrade over vector search — it is a different tool with a different cost profile. Building and maintaining a knowledge graph means ongoing investment in entity resolution and schema governance, and that investment only pays off if your queries genuinely need relationship traversal.
Do you need a hybrid approach?
Most mature enterprise AI implementations end up hybrid rather than purely one or the other. A common pattern uses vector search to find relevant starting points or supporting passages, then uses the knowledge graph to traverse relationships from those points and assemble a structured answer. This gets the strengths of both: the recall and flexibility of semantic search, and the precision and explainability of graph traversal, without forcing every query through a heavyweight graph pipeline.
Deciding where the boundary sits — which queries route to vector search, which route through the graph, and how results are merged — is itself a design decision that benefits from upfront architecture work rather than trial and error in production. This is the kind of decision we work through with clients as part of ai-product-strategy, before any retrieval pipeline gets built.
What does it take to build and maintain a knowledge graph?
A knowledge graph is only as good as the entity extraction and relationship modelling behind it, and that work does not stop once the graph is live. Entities need to be resolved consistently (the same customer appearing under slightly different records needs to be recognised as one node), relationships need to be kept current as the business changes, and the schema needs ongoing governance so the graph does not drift from reality.
For organisations without existing data infrastructure maturity, this is usually the real blocker — not the AI layer itself. Standing up reliable entity resolution and relationship pipelines is a data-infrastructure problem as much as an AI one, and it is worth solving in that order. We have written previously about building the data foundation AI depends on, which covers the groundwork this kind of project typically needs before a graph layer makes sense.
Once the foundations are in place, the ongoing engineering work — keeping the graph synchronised with source systems, monitoring retrieval quality, and evolving the schema as new entity types emerge — sits squarely in ai-engineering territory, and is worth resourcing as a continuing capability rather than a one-off build.
Is GraphRAG worth it for Australian enterprise teams?
For Australian organisations in regulated or relationship-dense sectors — financial services, insurance, healthtech, logistics and supply chain — GraphRAG is often worth serious evaluation, particularly where explainability matters to regulators or auditors. APRA-regulated entities and organisations subject to the Australian Privacy Act already carry obligations around decision traceability, and a graph-based retrieval layer can make that traceability concrete rather than aspirational.```
For organisations earlier in their AI maturity, or where the primary need is simply surfacing relevant content quickly, standard vector search remains the more pragmatic starting point. The right sequencing is usually: get retrieval working well with vector search first, identify the specific queries where it falls short, and only then evaluate whether a graph layer addresses those gaps. Jumping straight to GraphRAG without that evidence tends to produce complexity without a corresponding return.
If you are weighing up retrieval architecture for an enterprise AI project — or trying to work out whether your data is relationship-heavy enough to justify a graph layer — we can help. You can also browse our insights for more on retrieval architecture, data infrastructure, and AI implementation decisions.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.