Distributed SQL and Database Scaling: A Decision Guide
A practical decision guide for engineering leaders weighing read replicas, manual sharding, and distributed SQL against real write-throughput bottlenecks — not architectural fashion.
When does a single-primary database stop being enough?
A single-primary relational database stops being enough when write throughput, not read throughput, becomes the bottleneck. Read replicas and caching layers solve read-heavy problems — dashboards, reporting, catalogue browsing. They do nothing for write contention, lock pressure, or a dataset that has outgrown a single machine's disk and memory. If your engineering team is adding replicas and still seeing write latency climb, replicas are not the fix.
Most growing Australian SaaS platforms follow a predictable path. They start with a single PostgreSQL or MySQL instance, add a read replica or two when dashboards slow down, bolt on a caching layer (Redis or similar) to protect the primary from repeated queries, and that combination carries them a long way. The trouble starts when the write path itself — new signups, transactional updates, usage events, multi-tenant writes — exceeds what one primary can process, no matter how well it is tuned. This is a common trigger point we see during application modernisation engagements, where a platform that was fine at launch starts showing strain as the customer base scales.
What is distributed SQL and how is it different from sharding?
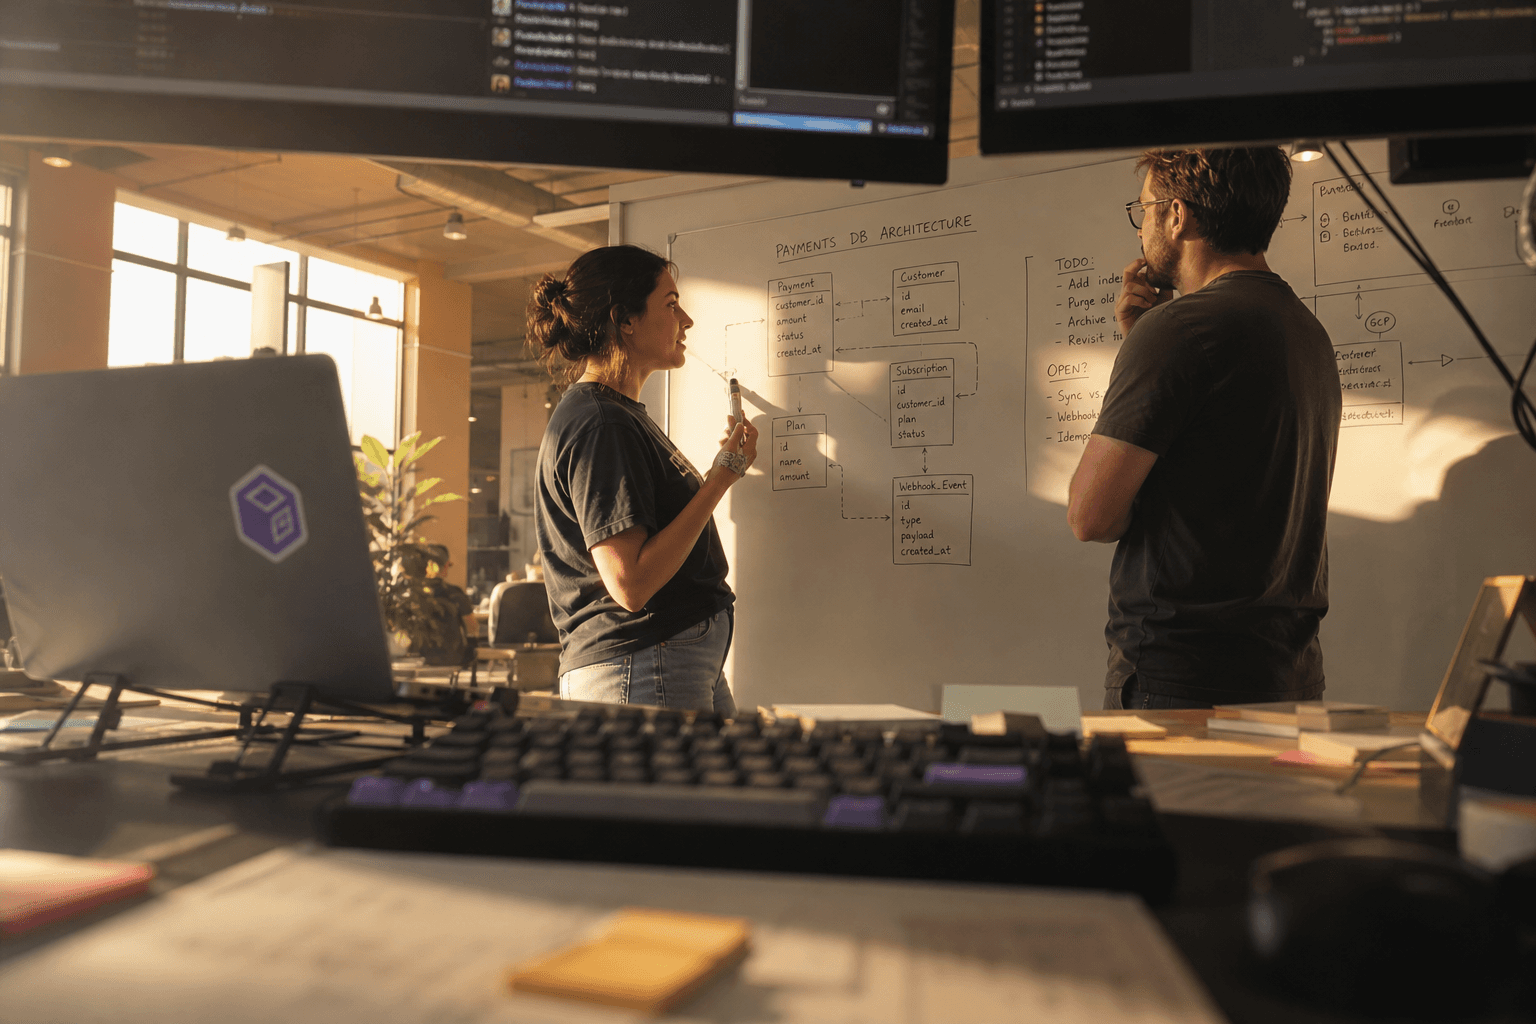
Distributed SQL is a database architecture that automatically partitions and replicates relational data across multiple nodes while preserving a standard SQL interface and transactional (ACID) guarantees. Sharding is the older, more manual approach: splitting data across independent database instances — usually by customer ID, tenant ID, or geography — and handling the routing, rebalancing, and cross-shard queries in application code.
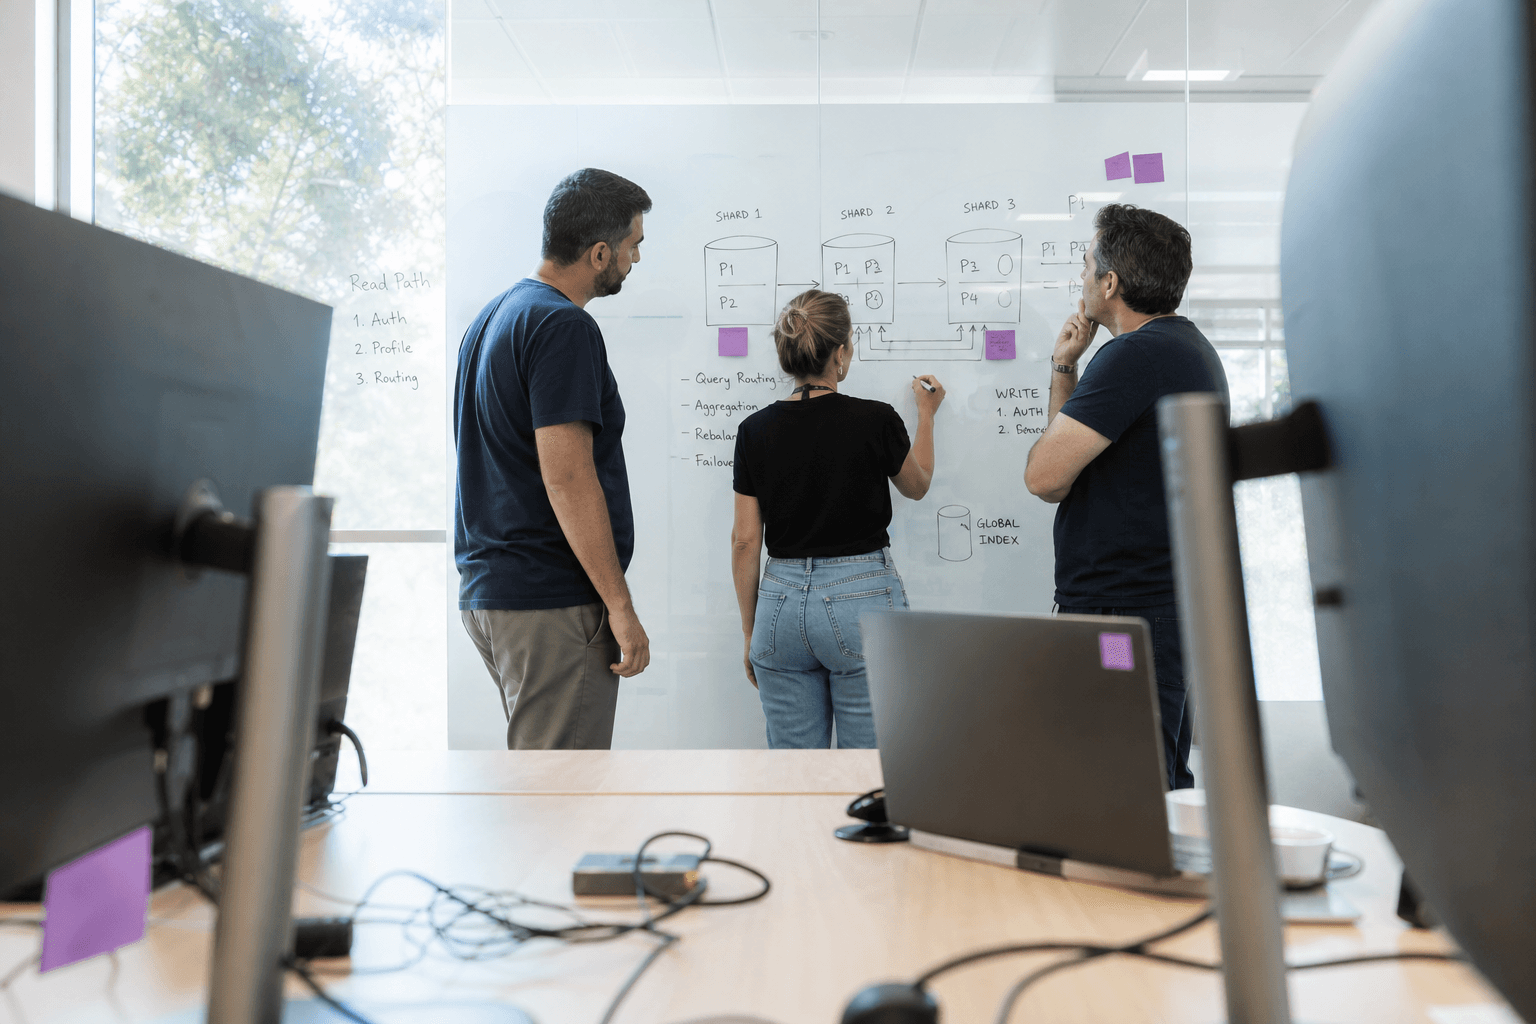
The practical difference is where the complexity lives. With manual sharding, your engineering team owns the partitioning logic, the rebalancing when a shard gets too large, and the application-level joins when a query needs data from more than one shard. With distributed SQL, the database handles partitioning and rebalancing internally, and in most cases still presents a single logical database to your application layer. You write fewer workarounds, but you take on a different database engine, a different operational model, and in some cases different consistency trade-offs than you are used to.
Neither approach is free. Distributed SQL reduces application-level complexity at the cost of operational and architectural change. Manual sharding keeps you on a database engine your team already knows, at the cost of carrying the partitioning logic yourselves, indefinitely.
How do read replicas, sharding, and distributed SQL actually compare?
The right choice depends on which constraint you are actually hitting — read load, write load, dataset size, or multi-region requirements — not on which option sounds most modern. The table below is a qualitative comparison; actual performance depends heavily on workload shape, schema design, and query patterns.
| Dimension | Read replicas + caching | Manual/application-level sharding | Distributed SQL |
|---|---|---|---|
| Solves read bottlenecks | High | High | High |
| Solves write bottlenecks | Low | High | High |
| Operational complexity to introduce | Low | High | Medium–High |
| Ongoing engineering overhead | Low | High (routing, rebalancing, cross-shard queries) | Medium (new engine to operate, but partitioning is automatic) |
| Preserves existing SQL/ORM patterns | High | Medium (cross-shard joins often break) | Medium–High (varies by product) |
| Multi-region write support | Low | Medium (with significant custom work) | Medium–High (varies by product) |
| Migration effort from a single-primary setup | Low | High | High |
For most teams, read replicas and caching remain the right first move — they are cheap, well understood, and solve the most common early bottleneck. The decision to move further only becomes urgent once write throughput, not read throughput, is the limiting factor.
What triggers should engineering leaders actually watch for?
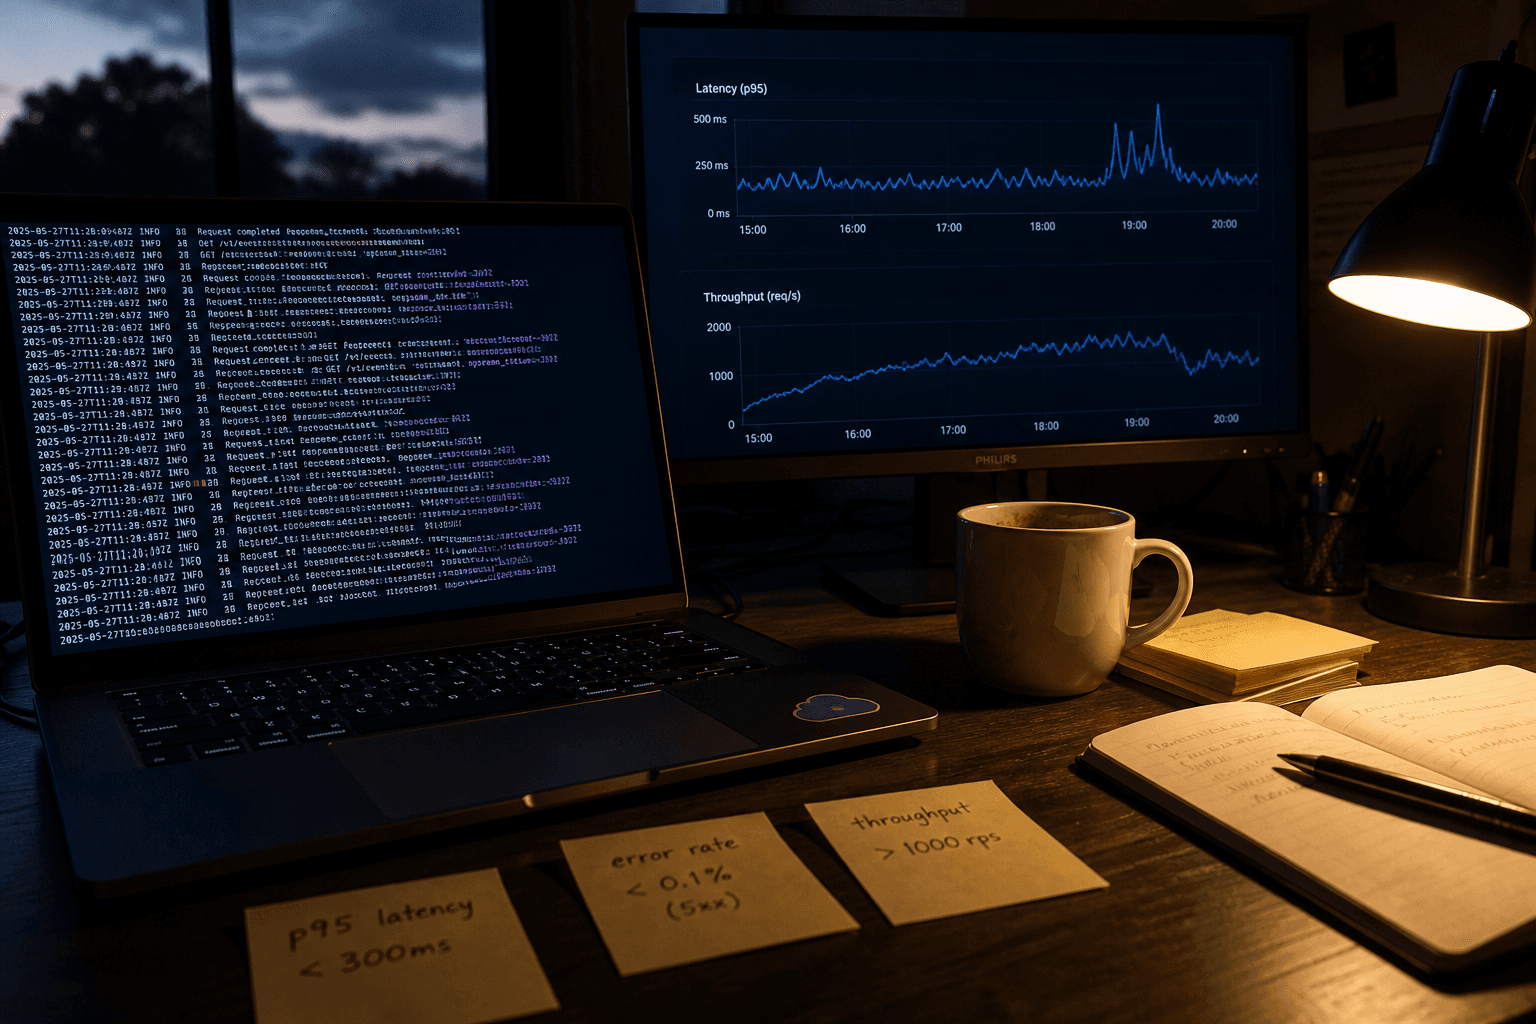
The decision to move beyond replicas and caching should be triggered by specific, measurable signals — not by a sense that the architecture feels dated. Watch for sustained write latency growth under normal load, a primary database approaching the practical limits of vertical scaling (bigger instance types stop helping or stop being available), multi-tenant "noisy neighbour" problems where one customer's load degrades others, or a genuine multi-region requirement for data residency or latency reasons.
It is also worth being honest about triggers that are not good reasons to migrate: a single painful incident, a new engineering hire's prior experience with a different database, or competitive pressure to use newer technology. Database migrations of this scale carry real risk and real cost, and they should be driven by workload evidence, not architectural fashion.
What should an Australian SaaS platform weigh before migrating?
An Australian SaaS platform evaluating this shift should weigh data residency obligations, the maturity of its existing schema, and whether the business genuinely needs multi-region writes or is solving a single-region write-throughput problem. The Office of the Australian Information Commissioner and sector-specific regulators (particularly relevant for fintech and healthtech platforms) may constrain where data physically resides — a factor that shapes whether distributed SQL's multi-region capabilities are a genuine requirement or an unused feature.
Schema maturity matters just as much as the regulatory picture. A schema with deeply nested joins, heavy reliance on database-level triggers, or extensive use of engine-specific SQL extensions will need rework before it can move cleanly to most distributed SQL engines, and that rework is often the bulk of the migration effort — not the database swap itself. Teams considering this path are well served by an honest audit of query patterns, transaction boundaries, and existing operational tooling before committing to a migration timeline.
It is also worth asking whether the write-throughput problem is actually a database problem at all. Sometimes the real constraint is an application layer that is doing more synchronous writes than it needs to, or a data model that was never designed with multi-tenancy in mind. In those cases, the right first step is application modernisation or targeted re-architecture, not a database migration. Where the data itself is the growth constraint — rather than how it is queried — this is also the point at which teams start to formalise their broader ai product strategy, since many AI features depend on the same write-heavy, low-latency data paths that are forcing the scaling conversation in the first place.
If the business case holds up — genuine write-throughput ceiling, real multi-region need, schema ready for the change — the migration itself still needs careful sequencing: dual-write periods, data validation, and a rollback plan that does not assume everything will go smoothly on the first attempt. This is where ai engineering and broader platform engineering practices intersect with data infrastructure decisions, particularly for platforms that are building ML or AI features on top of the same transactional data.
For more on related architecture decisions, see our more insights on legacy migration and data infrastructure.
If your team is weighing this decision and wants a second opinion grounded in your actual workload data rather than general advice, get in touch — we are happy to look at what you are seeing and talk through whether a migration is actually warranted.
Chris Kerr
Partner at Horizon Labs, an AI product consultancy and venture studio. A commercially focused product and technology leader with 20+ years building and scaling digital platforms, teams, and businesses across SaaS, travel, eCommerce, logistics and transport, and digital marketing — operating at the intersection of product, engineering, and data. Writes about platform strategy, AI transformation, modern data ecosystems, and the operational discipline that separates AI demos from AI products.